

Building Memory @cludeproject Prev ByteDance AI, DBS, StarHub Member @superteamsg
Joined June 2009
- Tweets10.5K
- Following3.7K
- Followers13.6K
- Likes17.2K




Call me biased but @Pumpfun been shipping like mad. Really no other social trading apps out there like ‘em

Also, new deployments are banned now. FML, time to move

An urgent notice from the Railway team
blog.railway.com/p/security-…



I believe, more and more people will look to tune specialised models
We started with Clude > Memory, Jev > Decision based and now @coinbase
Currently working on a specialised tool for a specialised task.

We were able to fine tune an open weight model (Qwen3.5-9B) on proprietary internal data at @coinbase, and it out performed frontier models, at much lower cost and speed, for a specialized task (fraud prevention in this case).
I think we'll see more of this pattern inside companies. The frontier models are amazing generalists. But increasingly you'll see specialist models out perform on more narrow tasks, either working on teams, or by themselves.
We're making it easy to fine tune models internally for our employees. We even have a skill for it in our internal harness that makes it easy to spin these up and start training them:
"/fine-tune-and-serve-llm I want to fine-tune Qwen for payments risk review. help me get started"
I imagine we'll have some backend services that could be replaced entirely by this new architecture.


Todays JEV announcement couldn't have come at a better time. We've been thinking about what's next for us.
Congrats to Diogo @CompleteSkeptic and @typesafeai on raising $870M at a $7.5B valuation!
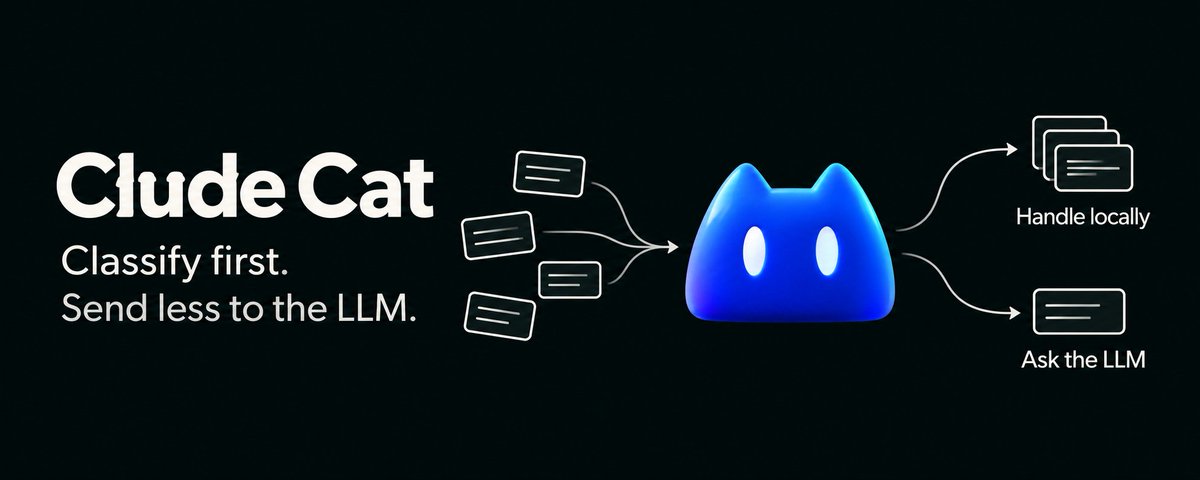
We've loved using JEV at Clude. It's helped us cut costs significantly and got us thinking about building further on our own Clude memory model to filter out the raw noise before passing data to JEV.
Through fine-tuning our own model we soon realized how expensive training a niche high performance model could be. But we also discovered just how good our own memory model was becoming at doing exactly what we needed to save on costs!
What started as a way to solve our own problem has turned into something we think is worth pursuing.
Back to building!

launched a model
accidentally served trillions of tokens a day
29.4% of the fortune 500 showed up
raised a really big series A from @a16z
it's been 3 weeks
we would like to sleep now

seb retweeted
gm, ICYMI this is a video recap of what we have built and achieved with @cludeproject so far. We let our actions demonstrate our long term commitment:
+ invested +$100K to training our own SOTA memory model and now live exclusively on Tencent
+ bought back ~1000 SOL to date and relocked (17% of supply)
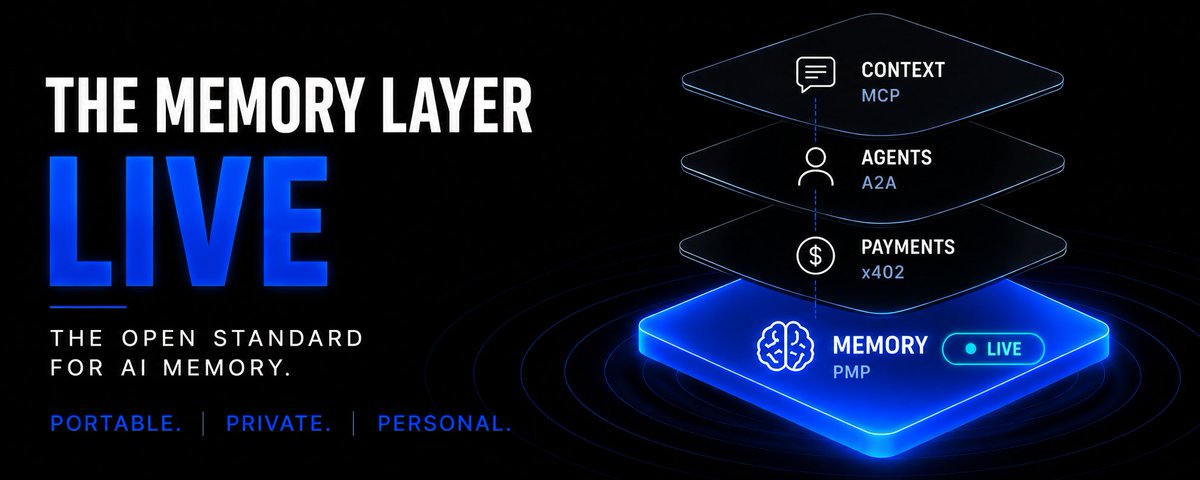
+ shipped our PMP as the first multi-chain Tokenized Memory infra live onchain
+ won various notable grants, partnerships and working with a few SG listed corporate clients
+ more to come with details in the video below:


🔐 Just locked 172,214,225 solana:AWGCDT2gd8JadbYbYyZy1iKxfWokPNgrEQoU24zUpump tokens with @Streamflow_Fi
It's on-chain. You can check the amount, time-period and recipients.
Check it out👇
app.streamflow.finance/contr…

Clude is indeed positioning itself as the ownership layer for AI memory. From our own private LLM model to the actual tokenized memory.
The full vertical AI memory stack.
Appreciate the detailed article and support
@KarmaWallet_Eco



Helping a friend get this in front of more eyes.
Think Revolut, if Revolut was built in web3. @kastro_xyz


I subscribed to @ManusAI back in April 2025, and I still remember that first “f***, it can actually do this?” moment.
OpenAI and Anthropic dominated the conversation, but Manus made agentic AI feel real. It changed what I expected AI to be capable of
More than a year later, I’m still an active user. And with Manus 2.0 + @CueAgents, I’m getting that same feeling all over again
Just signed up for Cue’s Max plan. It’s one thing to impress someone on day one. Getting them this excited again a year later, dope stuff
Amazing work, @Red_Xiao_, @peakji and @hidecloud. You’ve done it again.


Hugging Face is where AI models get published. Google, Meta and Mistral release there, thousands of smaller labs release there, and millions of developers pull models from it every day. Being on it puts CludeMem on the same shelf as the models it's built from, in front of the people who decide what their agents run on.
Hugging Face is step one. Step two is Tencent Cloud, where CludeMem becomes a hosted model: an endpoint any team can call for memory operations without running anything themselves, the same way they call a frontier model today, at a fraction of the cost and with their data in their own region. The open weights are the proof that the model works. The hosted offering is how it becomes a product
CludeMem-E4B is on Hugging Face.
It's a small local model that does the memory work inside an AI agent, available as a fully local / offline piece. Built on @Google 's Gemma model. Every reply is one JSON object you can validate and store. It has a 93% flag precision, runs offline in Ollama on 5.3 GB file.
This initiative proves the task is learnable at this size. Given two memories, the model can help decide whether it agrees, contradict, duplicate or replace each other, and answers from the memories it's handed, always as one JSON object you can validate.
On two human-labelled dialogue benchmarks in training, DNLI and DECODE, it gets 74% and 77% of the verdicts right
The bigger 8B parameters piece is coming soon, built on a rebuilt dataset.
huggingface.co/sebs-clude/Cl…
