

Research scientist @GoogleAI and visiting academic @Cambridge_Uni. Multimodal foundation models × AI for health. Past @Nokia @BellLabs, @Microsoft, @Telefonica.
Cambridge, UK
Joined May 2009
- Tweets133
- Following771
- Followers1.4K
- Likes5.1K





Pinned Tweet
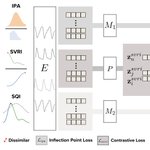
🦜PaPaGei: an open foundation models for the most widely used biosignal🦜
It is pre-trained on over 57,000 hours of PPG signals (like those from smartwatches & pulse oximeters) from publicly available sources.
Paper: arxiv.org/abs/2410.20542
Models/code: github.com/nokia-bell-labs/p…

we announce SensorFM, a foundation model pretrained on the largest personal health dataset (1T+ mins, 5 mil people, 100 countries)
- embeddings transfer across 35 tasks via systematic performance scaling
- agents search for predictive heads
- grounding LLMs for clinical answers

Introducing SensorFM, a large-scale Sensor Foundation Model that learns from 1 trillion-minutes of unlabeled wearable data drawn from five million consented participants.
SensorFM learns a single, reusable representation of sensed human physiology that transfers across cardiovascular, metabolic, sleep, and mental health, as well as lifestyle and demographic factors.
More →goo.gle/4ycJvot

ALT SensorFM is pre-trained on over a trillion minutes of multimodal sensor data via missing-aware masked reconstruction.
Proud to be part of this work! We trained a foundation model on 40M hrs of wearable data where gaps from charging, motion artifacts etc. are inevitable. Rather than imputing or discarding, it uses a new attention masking mechanism.
Don't fight the messiness, embrace it!
Introducing LSM-2, our newest foundation model for wearable sensor data. LSM-2 uses Adaptive & Inherited Masking, a novel self-supervised framework, to learn from incomplete data & achieve strong performance without requiring explicit imputation. More → goo.gle/4kP6Ncc

ALT Wearable devices sense an array of physiological and behavioral signals — making sense of these can be challenging.
If you are working on AI for health×timeseries please consider submitting to our NeurIPS 2025 workshop below. The team has prepared a great lineup of speakers and topics — stay tuned for updates!

🩺📈 The "Learning from Time-series for Health (TS4H)" workshop is BACK at NeurIPS 2025 🥳!
This workshop unites researchers across health time-series domains (from wearables to clinical systems) to tackle shared challenges. Details: timeseries4health.github.io/
🧵 (1/6)
I'll be at #ICLR2025 this week in Singapore and would love to connect with researchers interested in foundation models, representation learning, multimodal pretraining, & health sensing!
Feel free to catch me at any of these events or ping me here to schedule a time to chat.

We'd love to hear from researchers and developers who try it out!
Your feedback will be invaluable in improving and expanding its capabilities.
Tremendous work by @ArvindPillai10 and team @malekz4deh @raswak!

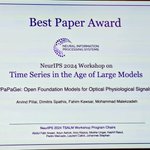
Great news from Vancouver, happy to share that 🦜PaPaGei received the 🏆 Best Paper Award at the Time Series in the Age of Large Models (TSALM) workshop in #NeurIPS2024! Huge congratulations to @ArvindPillai10 and the team. Stay tuned for the v2 of the paper with more results.

Dimitris Spathis retweeted

Exercising regularly can be hard and there's often conflicting information on the best ways to measure progress and fitness levels. But one stat that's increasingly seen as important to track is 'VO2 max' and Bloomberg Prognosis explains why.... trib.al/Tswcryv

🤔Why do Large Language Models like ChatGPT struggle with temporal data?
Our new work published in JAMIA w/ @raswak explores LLMs' difficulties when processing time series data, particularly from sources like mobile sensors or medical records.

You can read more on the full paper:
Paper: doi.org/10.1093/jamia/ocae09…
PDF: api.repository.cam.ac.uk/ser…

Check out this recent article on the tokenization problem - a quite accessible read for anyone interested in how LLMs represent inputs. Happy to see our work featured alongside cutting-edge research 😊
xitter.cf/TechCrunch/status/1809…

Going beyond traditional fairness metrics, we adapted CKA to compare layer-level representations across subgroups: ↑ performance gaps are associated with ↑ representation gaps.
Such metrics can be used to "discover" biased models when subgroups are not well-defined.

You can find more results on representation similarities and practical advice for fine-tuning fairer models on our paper and code repository.
Stellar work from S. Yfantidou and team @comarios @AthenaVakali @danielequercia @raswak!
