





Pinned Tweet
I trained models across MacBooks using Apple's AirDrop protocol.
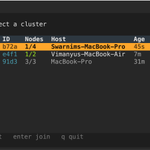
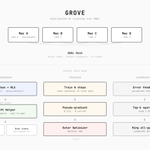
grove is a distributed training library for Apple Silicon. Devices discover each other over AWDL, a direct radio link. If there's a shared WiFi network it upgrades to that for speed, otherwise everything goes over the direct link. No router, no cloud, no setup.
grove start <script> -n 4
grove join


Swarnim Jain retweeted

today we're launching Frontier Computing (YC S26)
we grow neurons that colocate memory and compute, so you can more easily train ML models.
here's one of ours playing Frogger.
and we're building a 500M-neuron cluster. live EOY 2026.
that's 2,500x larger than the major biocompute systems available today
and we'll keep scaling until large model training on biocompute is widely accessible.
after all, human intelligence is built on a lipid, amino acid, glucose and vitamin cofactor soup: eating food is less costly than eating GPU compute
been using this for some time now. two of the best to do it @julianwindeck @aidangch 🌊

A billion people produce the most valuable dataset in the world every day – and delete it every night.
We’re recording it.
Introducing @AttentionInc
i was looking at old openai blogs and it's easy to forget that it really was just a research lab doing cool work

it's gonna be fun to see how far the newer models get with these tasks!

Introducing FrontierSWE, an ultra-long horizon coding benchmark.
We test agents on some of the hardest technical tasks like optimizing a video rendering library or training a model to predict the quantum properties of molecules.
Despite having 20 hours, they rarely succeed

8
1,082
Swarnim Jain retweeted

Introducing FrontierSWE, an ultra-long horizon coding benchmark.
We test agents on some of the hardest technical tasks like optimizing a video rendering library or training a model to predict the quantum properties of molecules.
Despite having 20 hours, they rarely succeed
Each device trains independently using DiLoCo, then syncs pseudo-gradients. SparseLoCo compression brings that down to 1-3% of the payload for slower links. Async overlap hides communication behind compute.

Still early (v0.1) and would love to hear feedback, built on MLX. Wrote about the architecture and technical decisions here: swarnimjain.com/grove
GitHub: github.com/swarnim-j/grove
pip install grove-ml

Swarnim Jain retweeted
Proximal is hiring research scientist interns! Our research team is working on projects touching coding agents, long-horizon RL and evals.
We share our work in the public through papers and open-source releases (first ones coming soon!). DM me if interested :)
Swarnim Jain retweeted
Incredibly excited to introduce Proximal with @navidkpr and @calvinchen!
Proximal is a new data company: we believe that training data is a problem solved through creative technical ideas rather than hiring thousands of contractors
teapawt.org/ProximalHQ/status/2024…

Today, we are announcing Proximal. Proximal is a research lab for data. Our core belief is that data which is complex enough to teach today’s frontier models is not bottlenecked by domain experts, but by great ideas and excellent software.
We are excited about a world in which coding agents can autonomously run for multiple weeks, solve the hardest technical problems and discover novel ideas that advance progress in various domains of science and engineering.
We believe that we are not far from this future, but that the biggest bottleneck preventing us from achieving it is training data.
Many companies work on data, but most of them are approaching it the wrong way. Historical capability breakthroughs are the result of creative engineers discovering scalable data collection methods, not thousands of contractors manually writing task demonstrations.
Inevitably, the potential impact of human data will become smaller and smaller as model capabilities increase: agents are already outperforming most humans in many domains - the number of experts that are capable of judging model outputs shrinks with every new model release.
Proximal is a new data company. We are not a recruiting firm or a talent marketplace, but a research and engineering organization that treats data as a problem which deserves the same level of rigor as work on training algorithms and model architectures.
We think that this is the most impactful work towards agents that can autonomously solve complex technical problems, and intend to share our research and progress in the open.


since when does apple do protein folding research? github.com/apple/ml-simplefo…

5
1,127

people said having a phd at your fingertips would level the playing field, but it's doing the opposite. the gap between mediocre, good, and exceptional is only widening
4
488
