

Sr. DS • AI Updates • Latest news & AI tools • Views are my own
BLR
Joined January 2014
- Tweets24.1K
- Following1K
- Followers13K
- Likes48.6K




𝗿𝗮𝗺𝗮𝗸𝗿𝘂𝘀𝗵𝗻𝗮— 𝗲/𝗮𝗰𝗰 retweeted
This tiny duck 🦆 taught itself to walk through Reinforcement Learning.
MicroDuck is a 25 cm biped that learned every move in simulation first: thousands of falls in MuJoCo, trained with PPO, and then dropped onto real hardware.
The software’s open source. The full hardware files? Not quite. Still one of the coolest ways to get hands-on with robot learning from your desk.

𝗿𝗮𝗺𝗮𝗸𝗿𝘂𝘀𝗵𝗻𝗮— 𝗲/𝗮𝗰𝗰 retweeted
𝗦𝗲𝗹𝗳-𝗘𝘃𝗼𝗹𝘃𝗶𝗻𝗴 𝗔𝗴𝗲𝗻𝘁 𝗛𝗮𝗿𝗻𝗲𝘀𝘀
The agents don’t fail loudly. They fail the same way, again and again, and nobody notices until a user does.
So the question I keep coming back to isn’t “how smart is the agent?” It’s “how does it get better without getting worse?”
This harness answers that.
The agent perceives, thinks, plans and acts like any other. The difference is what happens after a mistake.
It doesn’t just record that something failed. It compares the failed run against a good one and finds the exact step where things went wrong.
It doesn’t patch one-off errors either. It groups failures by root cause, so it fixes the pattern, not the symptom. No hardcoded answers. No sneaking test data into the prompt.
And nothing changes on trust alone. Every update the agent proposes for itself has to pass a quality gate and a performance gate before it’s allowed in. If it makes things worse, it’s rejected.
That last part is what matters most. Self-improvement without protection is just drift with extra steps.
Precise diagnosis. Real generalization. Regression protection. Validated updates.
Congratulations to Sam Pasupalak, not Sam Altman. Sam Pasupalak's team just beat Sam Altman's team in engineering design at the Wrobench.
It's 100x faster and 150x cheaper than GPT-6 Astra.


Introducing SKY-001, the first Engineering World Model.
On CAD and BIM tasks, it beats GPT-6 Astra and every frontier model we tested:
-> 51-125x faster
- > 150-210x cheaper
-> Higher IOU than all frontier models
SKY-001 lets you dream a physical object before you build it.
18 months of work. Built by the team out of Maluuba's deep learning lab (acq. by @MSRResearch).
The first ‘AI General Engineer’ will be the backbone for Autonomous Manufacturing.
𝗿𝗮𝗺𝗮𝗸𝗿𝘂𝘀𝗵𝗻𝗮— 𝗲/𝗮𝗰𝗰 retweeted
𝗩𝗲𝗰𝘁𝗼𝗿 𝗥𝗔𝗚 𝘃𝘀 𝗩𝗲𝗰𝘁𝗼𝗿𝗹𝗲𝘀𝘀 𝗥𝗔𝗚 𝘃𝘀 𝗔𝗴𝗲𝗻𝘁𝗶𝗰 𝗥𝗔𝗚
RAG tutorials teach you one pattern: chunk the document, embed it, store the vectors, search by similarity.
It works. Until someone asks a question where the answer depends on where something sits in the document, not just what it says.
Here’s how three approaches handle the same problem, and why the field is slowly moving from searching text to navigating structure.
𝗩𝗲𝗰𝘁𝗼𝗿 𝗥𝗔𝗚: find what looks similar. You take a long document, split it into fixed-size chunks, turn each chunk into a vector with an embedding model and store them in a vector database. When a question comes in, it gets embedded with the same model, and the system pulls back the top-k chunks that sit closest to it in vector space. The LLM writes an answer from those chunks.
𝗩𝗲𝗰𝘁𝗼𝗿𝗹𝗲𝘀𝘀 𝗥𝗔𝗚: navigate the document like a person would. Vectorless RAG does exactly that. Instead of chunks and embeddings, it builds a hierarchical index of the document: root, chapters, sections, pages. When a question arrives, the LLM reads that tree, works out what’s being asked and walks down the branches to the most relevant section.
𝗔𝗴𝗲𝗻𝘁𝗶𝗰 𝗥𝗔𝗚: reason your way to the answer. Agentic RAG keeps the tree index and puts an agent in charge of it.
The question is usually complex or multi-step, the kind a single lookup can’t resolve. The agent first plans how to approach it. Then it explores the tree level by level:
→ Understand the intent behind the question
→ Explore the chapters that might be relevant
→ Evaluate the context at each level before going deeper
→ Follow the right branch down to the exact node
→ Check cross-references to other sections before committing to an answer
The result is grounded evidence: a specific page and section, verified against the rest of the document, and an answer that cites it.
The trade-off: it’s the slowest and most expensive of the three, and it needs good guardrails so the agent knows when to stop exploring.
So which one should you use?
Tesla’s new Roadster runs on SpaceX-style cold gas thrusters.
It's crazy to live. Isn't it?
We just saw a car fly, literally. What goes behind the tech actually?
I tried to explain in 1 minute. Let me know your views.
𝗿𝗮𝗺𝗮𝗸𝗿𝘂𝘀𝗵𝗻𝗮— 𝗲/𝗮𝗰𝗰 retweeted
Making an Action-Taking AI Agent Production-Ready
Imagine you are working at a food delivery company.
A customer receives cold biryani and requests a refund. Your payment API times out, so your code retries the request, assuming the first attempt failed.
But the first request actually succeeded.
The retry triggers another refund. And another.
One cold biryani. One API timeout. Three refunds to the same customer.
Now multiply this by thousands of orders.
The model didn’t fail. The system around it did.
I wrote a full breakdown of making an action-taking AI agent production-ready. Check it out here:
growtechie.substack.com/p/ma…
𝗿𝗮𝗺𝗮𝗸𝗿𝘂𝘀𝗵𝗻𝗮— 𝗲/𝗮𝗰𝗰 retweeted
I keep seeing the same pattern with RAG projects.
Someone builds a prototype over a weekend. They connect a vector database, add a few PDFs, write a prompt, and ask it ten questions. Every answer looks right, the demo goes well, and everyone is happy.
Then it goes to real users, and within a week the complaints start.
“It gave me the old refund policy.”
“It couldn’t find the error code I searched for.”
“It answered confidently, but the answer was completely made up.”
The first reaction is usually to blame the model and switch to a bigger LLM. Most of the time that changes nothing, because the model was never the problem.
The real issue sits before the model ever sees the question. The right chunk was never retrieved, or it was cut in half during chunking, or it was buried under four passages that only looked relevant. The LLM did exactly what it was told and answered from bad context.
Reliable RAG is not about a smarter model. It’s about giving the model the right information and keeping it honest about what that information says.
Here’s the pipeline I’d build today:
Chunk by structure : Split on headings, not token counts, and add the section heading to every chunk so it keeps its context.
Use hybrid retrieval : Vector search understands meaning but misses exact terms like product codes. BM25 catches those. Run both and merge the results with RRF.
Rerank 50 down to 5 : Retrieve wide for recall, then use a cross-encoder to keep only the best matches. If nothing passes the threshold, don’t force an answer.
Ground every answer : Tell the model to answer only from the sources, cite each claim, and clearly say when the docs don’t have the answer.
Evaluate both halves separately : Measure retrieval and generation on their own. Otherwise you’ll never know which part actually broke.
Guard and monitor
Filter chunks by user permissions, re-index when documents change, and log every request so real failures become new test cases.
None of this is fancy. It’s just the steady engineering work that turns a nice demo into something people can actually trust.

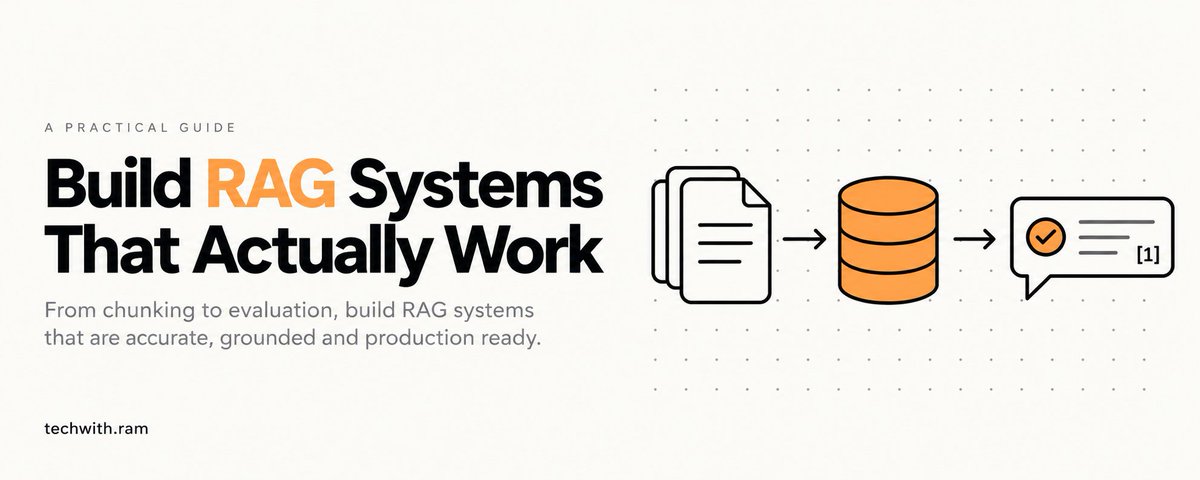
I keep seeing the same pattern with RAG projects.
Someone builds a prototype over a weekend. They connect a vector database, add a few PDFs, write a prompt, and ask it ten questions. Every answer looks right, the demo goes well, and everyone is happy.
Then it goes to real users, and within a week the complaints start.
“It gave me the old refund policy.”
“It couldn’t find the error code I searched for.”
“It answered confidently, but the answer was completely made up.”
The first reaction is usually to blame the model and switch to a bigger LLM. Most of the time that changes nothing, because the model was never the problem.
The real issue sits before the model ever sees the question. The right chunk was never retrieved, or it was cut in half during chunking, or it was buried under four passages that only looked relevant. The LLM did exactly what it was told and answered from bad context.
Reliable RAG is not about a smarter model. It’s about giving the model the right information and keeping it honest about what that information says.
Here’s the pipeline I’d build today:
Chunk by structure : Split on headings, not token counts, and add the section heading to every chunk so it keeps its context.
Use hybrid retrieval : Vector search understands meaning but misses exact terms like product codes. BM25 catches those. Run both and merge the results with RRF.
Rerank 50 down to 5 : Retrieve wide for recall, then use a cross-encoder to keep only the best matches. If nothing passes the threshold, don’t force an answer.
Ground every answer : Tell the model to answer only from the sources, cite each claim, and clearly say when the docs don’t have the answer.
Evaluate both halves separately : Measure retrieval and generation on their own. Otherwise you’ll never know which part actually broke.
Guard and monitor
Filter chunks by user permissions, re-index when documents change, and log every request so real failures become new test cases.
None of this is fancy. It’s just the steady engineering work that turns a nice demo into something people can actually trust.

𝗿𝗮𝗺𝗮𝗸𝗿𝘂𝘀𝗵𝗻𝗮— 𝗲/𝗮𝗰𝗰 retweeted
This Claude Code is a skill that turns any idea into a live, interactive plate you can turn, light, and look inside. Attention, the heart, a power grid, and a hash map are some examples you can see.
GitHub repo: github.com/Ramakm/folio-anat…
Just install and bring your own ideas into life in just secs.
- Install - Prompt: /folio explains how an electric motor turns
- It will create a single-page file to view in SVG, 3D, and WebGL formats. With lots more details.
- No crazy prompting - Just your ideas live in secs.
Inspired by the anatomy skill of Ryan.