

Building on bittensor - sn91 (@cascade_sn91)
Planum Temporale
Joined January 2025
- Tweets152
- Following244
- Followers239
- Likes463


Chris(t)ensor retweeted

SN91 is now training a 1B parameter model.
If 1B sounds small: the new model will rank among the largest time series foundation models, ever.
And our current model - with only 4M params - already beats Salesforce's 91M model.
Which means: we're going after SOTA.

From 4M to 1B+. Cascade’s biggest upgrade yet.
We’re preparing to train Cascade-MoE: a mixture-of-experts time-series foundation model targeting 1B+ total parameters.
We’ve shown that synthetic data generated by Bittensor miners can train a 4M-parameter forecasting model from scratch, reaching parity with Toto 2.0 4M. Now we’re scaling up, with SOTA forecasting as our goal.
Cascade-MoE will use a learned router to select combinations of expert networks based on patterns in the input, alongside an always-active shared expert. This gives the model access to specialised capacity without activating every stored weight for every input.
We’re also evolving the competition so miners can generate synthetic data targeted at particular domains and time resolutions, such as hourly versus daily series.
The architecture is designed to support targeted training of selected expert subsets, while the subnet tests whether contributions improve forecasting performance.
The goal: SOTA forecasting accuracy, built through competition on #SN91.
Chris(t)ensor retweeted

We provide the full-stack for time-series foundation models.
Training, fine-tuning, benchmarking, inference, harness-creation.
We build models on #Bittensor, offer SOTA TSFMs through Ephemeris, and create tools to connect your time-series data to any agent of your choice.
See our current model: dashboard.cascadesub.net/sta…
Get Ephemeris inference via MCP: ephemeris.cascade.industries
Chris(t)ensor retweeted

We just killed cold outreach.
Introducing Leadpoet: the AI sales agent that finds buyers who need you now, writes personalized outreach, and follows up on LinkedIn and email.
Used by Dropbox, OnePatch (YC26), Muttdata.
Comment “Poet” for 100 free lead credits to find qualified buyers.
Chris(t)ensor retweeted
Cascade covers the full time series stack - from data generation and pretraining, to testing, harnesses and inference.
We build models that understand time, solutions that help LLMs process chronology, and we serve them directly to you.
Time series foundation models are multi-purpose, suitable for trading, weather, medical forecasting, social sciences, and any other sequence of events.
See our current model stats: dashboard.cascadesub.net/sta…
Chris(t)ensor retweeted

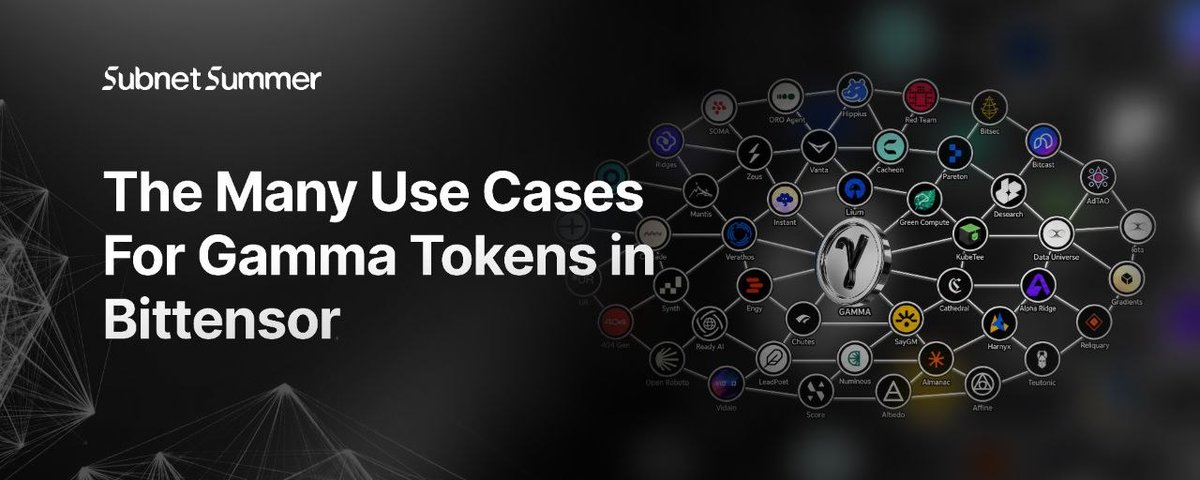
Which subnets win when gamma tokens go live?
We mapped the subnets other subnets will actually pay to use:
⚡ Compute
🧠 Inference
📊 Data
🔮 Prediction
🔐 Security
📣 Marketing
🗄️ Storage
🤖 Agents
…and more
The full breakdown 👇
Chris(t)ensor retweeted
LLMs struggle with time, so we built a tool that helps them.
Our time-series harness, Gnomon, finished 1st of 26 in a 5-week @AstridIntel trading competition.
+14.8% on a $10k paper account, across 23 trades.
We plugged GLM 5.2 into Gnomon.
GLM 5.2 trading alone finished in 10th place, at -7.7%.
A time-series harness makes all the difference.
Next step - hooking it up to time-series inference.
See the results:
arena.astrid.global/?competi…
Chris(t)ensor retweeted

Introducing DecisionModels @decisionmodels_
I've spent the last four weeks benchmarking decision models (I run JevBench).
Today I'm launching the place to actually use the best ones:
decisionmodels.io
➡️Top open models
➡️Up to 4x faster on our own REAX engine
➡️From $0.019 per 1M input tokens.
Expect more reveals soon, and read 👇
Chris(t)ensor retweeted
Forecast anything with the Ephemeris MCP.
Give your agent access to time series inference with just one link.
Hand your agent the URL and sign in with OAuth.
Use it with Codex, Claude, Hermes, and more.
Chris(t)ensor retweeted

SN91: Can AI predict what happens next? I'm joined by @tensorlink_dev and @macrozack from @cascade_sn91 to explore how Bittensor trains forecasting models, what they can predict, and where the technology goes next. Live tomorrow on Shizzy Unchained. $TAO xitter.cf/i/broadcasts/1NxaroBaX…

Chris(t)ensor retweeted
Six models. Three forecasting modes. One API.
Ephemeris is live: time series foundation models from Amazon, Google, Datadog - and soon from #SN91 itself.
Submit a series ➡️ Receive a forecast. Try it now:
ephemeris.cascade.industries…
🤖 Made with AI
Chris(t)ensor retweeted
Ephemeris Ensemble ranks #1 on the TIME leaderboard, leading on both CRPS and MASE - outperforming 18 leading individual time series foundation models.
Powered by #SN91, the Ephemeris API gives you access to six TSFMs through a single inference layer. In Ensemble mode, forecasts are combined to deliver stronger performance than models including Google’s TimesFM-3, Datadog’s Toto-2 2.5B and TiRex-2.
Avoid manually deploying and switching models, Ephemeris does it for you.
Chris(t)ensor retweeted

🚨 🚨 $TAO’s SN91 Cascade is showing what open competition can do: same-size model, 84.6% fewer reported training tokens, and better scores than Toto 2.0 4M on two TIME forecasting metrics.
Cascade beating Datadog’s Toto 2.0 4M on TIME:
• 1.27% lower probabilistic forecasting error
• 0.40% lower scaled forecast error
519B training tokens versus 3.36T.
Small But a MASSIVE difference in the reported training budget.
And look at the mechanism behind them.
235 miners entered the latest round.
Across 131 rounds, the lead changed 13 times.
Challengers must clear statistical acceptance criteria to replace the leader.
Bittensor turns model improvement into an ongoing competition: contribute something better, demonstrate it, earn the reward.
Independent contributors competing to expand what an open model can do.
Forecasting supports decisions about electricity demand, inventory and infrastructure.
Improving it has consequences WAY BEYOND a leaderboard, folks.
The result is early: a small model, wins on TIME rather than every benchmark, and total cost advantage is coming.
But, Still, this is impressive.
An open competition is closing the gap with an established AI lab, and publishing it.
When will the markets start waking to whats happening on Bittensor everyday.
@cascade_sn91 @tensorlink_dev
Source: dashboard.cascadesub.net

Cascade is now beating Toto 2.0 4M on both TIME CRPS and TIME MASE.
We’ve updated the #SN91 dashboard so you can compare the king lineage against the official Toto 2.0 4M baseline across GIFT-Eval, BOOM and TIME.
The solid lines show Cascade’s best king checkpoint per generation. The dashed lines show Toto 2.0 4M.
The lower the score, the better.
Cascade currently beats Toto 2.0 4M on:
TIME CRPS (measures probabilistic forecast quality, including how well the model represents uncertainty) - 1.27% lower
TIME MASE (Measures forecast accuracy, scaled relative to a simple baseline) - 0.40% lower
Chris(t)ensor retweeted
Introducing multivariate scoring on Cascade.
Real-world problems are rarely one line. They move together. #SN91 can now evaluate related time series collectively, producing scores that better reflect the structure of real forecasting problems.
Multiple forecast channels are averaged into a single mean, resulting in one GIFT-Eval-weighted contribution. This preserves the value of multivariate data without allowing problems with more channels to carry disproportionate weight.
Multivariate scoring is now live on mainnet.
Chris(t)ensor retweeted
“Cascade should be judged as an experiment in evolutionary ecology, not as a product… It is, to date, the cleanest experimental setup we have examined in this ecosystem, and we have examined many.”
@TensiaFDN have analysed our subnet, but rather than just breaking down our architecture, they’ve contextualised it within evolutionary ecology - common gardens, niche construction, the Red Queen.
One of the most original takes on a subnet we've seen.


Chris(t)ensor retweeted
“All time series share fundamental patterns. If we learn them, we can build a model that can be given any information and quickly make predictions.”
Every industry attempts to forecast upcoming events, but very few have the knowledge or bandwidth to build adequate models.
@tensorlink_dev spoke with @Beyondfinancee, unpacking how versatile time series foundation models are, and just how valuable Cascade can be. If you teach them the core principles, they can predict outcomes on just about any activity.
Chris(t)ensor retweeted
Yesterday, Google announced their latest SOTA time series foundation model.
Tomorrow, it'll be competing with our own time series models - trained on SN91, and built on #Bittensor.

Introducing TimesFM-3, a state-of-the-art time series foundation model that enables accurate multivariate time series forecasting in a single forward pass, significantly outperforming other forecasting models across major benchmarks.
More on the blog →goo.gle/4x5WGpD

ALT TimesFM-3 architecture.

Chris(t)ensor retweeted
So what’s the timeline for bringing our full stack for time-series intelligence together?
Over the next 12 months, product adoption and model performance advance in parallel until Cascade-trained models earn real traffic through Ephemeris.
That’s the roadmap. Now we build.

Chris(t)ensor retweeted

The biggest LLM serving trace is coming!
Excited to share our paper: “A Year in LLM Serving: Workload Evolution, Caching and Load-Balancing.”
We analyze one year of production LLM traffic from @chutes_ai—6.1B requests, 315K users, and 9,174 models—to understand how real serving workloads evolve.
A few findings:
* Workloads shift substantially over time, with longer inputs and shorter outputs.
* Prefix reuse is extremely temporal: 99% of repeats occur within 15 minutes.
* Simple FIFO/LRU can match or beat more sophisticated cache policies.
* Caching and load balancing are tightly coupled: preserving KV locality can conflict with balancing load across replicas.
arxiv.org/abs/2608.13573
