

Love Cats, and Love Cats 🐈 🇵🇱 DMs open! (I don’t bite) 🐱 want to talk? come join https://xitter.cf/t.co/b5iZQKZAss Support me here: https://xitter.cf/t.co/VCHvmK4Lx1
Polska
Joined October 2021
- Tweets20.4K
- Following432
- Followers1.7K
- Likes48.6K



Pinned Tweet
I just created a Ko-fi page! If you’d like to support my work (or just buy me a coffee), check it out here: ko-fi.com/testtm
Will help me and cats a lot :( and bring me one step closer to my dream of creating my very own large language model (LLM). Every bit helps ♥️

testtm retweeted

The purpose of Artificial Analysis is to keep the Chinese out, Antrhropic in, and OpenAI down.
For me, Artificial Analysis is no more trust worthy. This update was made to just make openai higher, Chinese models lower.
And it's not even thier first time, updates like that happend many times. All with the same result...
There is no way 6.1 Terra is better than Fable 5.1, or Argon.
Imo if you want trustworthy benchmark leader board look at Vals Ai leader board.


Announcing Artificial Analysis Intelligence Index v5, featuring 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets
The Artificial Analysis Intelligence Index is our composite measure of model capabilities across tasks reflecting real-world usage today. v5 is our biggest upgrade since v4 launched in January. With v5, 60% of the Index is now based on evaluations with private test sets or held-out answers.
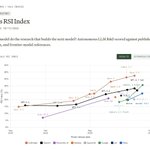
Alongside Intelligence Index v5, we’re launching the Artificial Analysis Progress Index v1, which tracks model capability over time on one continuous scale.
New to the Intelligence Index:
➤ FrontierCode 2.0: Cognition's newly-launched private benchmark of real-world coding tasks, graded on whether a repository maintainer would merge the agent's change
➤ Terminal-Bench-Science: 70 agentic scientific research tasks, run in a terminal environment
Upgraded:
➤ HLE-Diamond (replacing Humanity's Last Exam): a refined 1,000-question version of Humanity's Last Exam, split evenly between reasoning and knowledge questions
➤ AA-Omniscience v1.1: An updated dataset with saturated and public set questions removed, new questions added, and ambiguous or erroneous questions revised
➤ CritPt v2: a private, 40-question hard subset of CritPt v2, revised by the CritPt authors and run with a code-execution tool
Staying in the Index: AA-Briefcase, AutomationBench-AA, GDP.pdf and Terminal-Bench 4.0
Removed from the Index: GDPval-AA v2.1, SciCode, and AA-LCR v1.1
Key results:
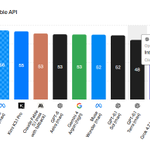
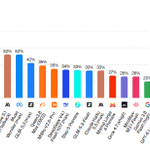
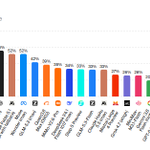
➤ Claude Opus 5.5 (max) leads at 58, ahead of GPT-6 Astra (max, 57) and GPT-6.1 Sol (max, 55): Anthropic and OpenAI hold the top five models. Gemini 4 Argon (high) is next at 50
➤ The open weights gap widens from 3 points to 12: Kimi K3.1 Pro (weights not yet released) is the top open weights model at 46. Among released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) lead at 32 - 26 points behind the leader and below Claude Haiku 5.5 (max, 36)
➤ Cost per task varies by more than 13x among the leading models: of the 10 highest-scoring models shown, GPT-6.1 Terra (max) is the cheapest at $0.96 per Intelligence Index task and Claude Fable 5.1 (max) the most expensive at $13.04

Massive release honestly! so cool!

Introducing 𝙻𝙵𝙼𝟹: our new generation of Liquid Foundation Models. With a new tri-hybrid architecture and new multimodal encoders, the LFM3 family is the ideal model suite for specialized intelligence.
> 6 model instances, across text, audio, vision, and omni modalities, generative and decision models.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱: text, 256k context window.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱: vision-language model with video-input support for spatial understanding
> 𝙻𝙵𝙼𝟹-𝙰𝚞𝚍𝚒𝚘-𝟸𝙱: tool calls, voice chat, reasoning in 18 languages.
> 𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱: an omni model combines vision, audio, and language.
> 𝚍𝟷-𝟸𝙱 and 𝚍𝟷-𝙾𝚖𝚗𝚒-𝟸𝙱: decision models with typed outputs and calibrated probabilities in a single pass. Omni adds audio input.
> fine-tune on 1 GPU.
> a new tri-hybrid architecture
> architecture optimized for 14 processor classes across GPUs, CPUs, and NPUs.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱 is a beast. It performs competitively with Gemma 4 12B (6x larger), and Gemini 3.5 Flash Lite, and GPT-5.6 Luna, with 1.9B parameters.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 is #1 on the Pareto frontier of device intelligence 𝚙𝚒𝚙𝚎𝚝𝚝𝚎.𝚕𝚒𝚚𝚞𝚒𝚍.𝚊𝚒
Every modality for specialized intelligence. Pick the one that fits your use case, customize it, and run it on-device.
1/ 🧵
PEAK RELEASE FROM GDM!!

Introducing Genie 4 from @GoogleDeepMind, our most realistic and interactive world model yet 🌍
Now you can use natural language to dynamically steer the world and its soundscape in real-time, whether you're changing the weather, moving the camera, or introducing new elements to the environment.
So, how does the model do that?
Behind the scenes, Gemini acts as the "brain" of the simulation. It translates your requests into actions, plans out complex events, watches the scene unfold to keep track of what's happening, and adjusts as you change the story. Genie 4 also introduces ambient audio and real-time interactive human dialogue that adapts on the fly.


It is cool, very cool indeed!
But still sad. that even with that deal or without it, Poland isn't a big player in AI space... and only few investments need to be made so we can finally be doing AI, but no one want to do them...

Anyone know someone from @tenstorrent i really want to try thier acclerators on TensTorrent Cloud. and was on waitlist for months now. and still not accepted :(


Comments are blocked, so I wanted to point out here that while the idea is okay, how models generalize makes it less effective against large models. It will work on smaller models, though which are mostly trained by enthusiasts rather than big companies. So this will end up hurting enthusiasts, not big tech :(


Asus Armoury software is awfull! thing never works. can't they just fix it? and also constant updates and no updates fix the issues. mann garbage.


Honestly good that somone now verify routers. remeber when Sakana Fugu was like WTF. and it seems a bit... uncool on regular benchmarks. still can be good. but lot of work need to be done i see.


Probably some won't agree. But, this annoucment is lot more important than Fable 5.5

New on our Science Blog: designing protein binders against scorpion neurotoxins.
Scorpions sting about 1.2m people every year, and antivenoms are often costly or in short supply. Claude has made an early step toward finding new treatments.
anthropic.com/research/claud…
