

Pinned Tweet
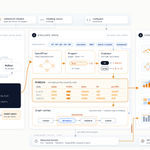
Spent half a year of spare time building HuggingArch — a "compiler" that doesn't run tensors, but computes FLOPs, memory traffic & KV cache for any HuggingFace model.
Agent writes the spec → sympy evaluates → one click gives theoretical perf across GPUs & parallel configs.
No GPU. No weights. No runtime.
web: huggingarch.com
blog: shenhan.cc/blog/huggingarch.…
github: github.com/shenh10/HuggingAr…
Star ⭐ & come build it with me!

Looking for GPU sponsorship for an open-source project 🙏
HuggingArch computes KV cache capacity & theoretical Pareto curves for any HF model — no weights downloaded, no GPU needed. KernelBench plugs into multiple operator/inference-engine backends and archives real profiling data.
What's needed: at most one machine per GPU type. Only communication kernels need multi-GPU data; everything else benchmarks fine on a single card.
What it unlocks: measured data points showing exactly how far each runtime sits from its SOL ceiling — aligning theory with the actual achievable upper bound, for the whole community.
DM open 🙏 🔗 huggingarch.com


Spent half a year of spare time building HuggingArch — a "compiler" that doesn't run tensors, but computes FLOPs, memory traffic & KV cache for any HuggingFace model.
Agent writes the spec → sympy evaluates → one click gives theoretical perf across GPUs & parallel configs.
No GPU. No weights. No runtime.
web: huggingarch.com
blog: shenhan.cc/blog/huggingarch.…
github: github.com/shenh10/HuggingAr…
Star ⭐ & come build it with me!
Han Shen retweeted
Spent half a year of spare time building HuggingArch — a "compiler" that doesn't run tensors, but computes FLOPs, memory traffic & KV cache for any HuggingFace model.
Agent writes the spec → sympy evaluates → one click gives theoretical perf across GPUs & parallel configs.
No GPU. No weights. No runtime.
web: huggingarch.com
blog: shenhan.cc/blog/huggingarch.…
github: github.com/shenh10/HuggingAr…
Star ⭐ & come build it with me!