
Programmer, step dad, friend of dogs and cats.
East Greenwich, RI
Joined December 2011
- Tweets88
- Following32
- Followers75
- Likes179

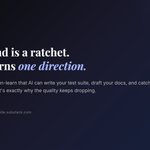




“The models aren’t getting dumber because the research failed. They’re getting dumber because the business is succeeding.“
Why your AI got worse this weekend, and what the 1990s telecom crash tells us about who wins the next decade.
If you use AI tools for work (coding, writing, analysis, anything), you’ve probably noticed something uncomfortable recently: they’re getting worse. Not dramatically. Not broken. Just… sloppier. Less sharp. The tool that mass-converted your entire team last month now needs two or three extra nudges to get the same result.
You’re not imagining it, and this article explains why. No ML background required. Just an appetite for economic history that rhymes. If you remember the dot-com crash, or even if you just know that Google somehow went from scrappy search engine to owning the internet’s backbone, the same structural playbook is running again. Except this time it’s not fiber optic cable. It’s GPU clusters.
Think about where you were in January. Most people weren’t using AI for real work yet. Then something flipped. Opus 4.6, Codex 5.3, coding agents that actually worked. Within weeks, millions of developers rebuilt their entire workflow around these tools. That was last month. We’re barely a month into the era where AI is genuinely load-bearing for professional work, and we’re already watching the quality slide. That’s not a coincidence. That’s the thesis.
And here’s the thing: nobody’s going back. You’re not going to un-learn that your AI can write your test suite, draft your architecture docs, and catch bugs you missed. The demand is a ratchet. It only turns one direction.
This is a story about a triangle, a bubble, and two very patient companies — one that’s done this before, and one that just signed the smartest deal in tech.
The Trilemma
So what’s actually going on? The degradation isn’t random and it isn’t new. Models getting worse over time, same API, same name, worse results, has been measured repeatedly.[1] But nobody’s explained why it keeps happening.
Here’s why. There are three forces in the AI compute market, and at any given moment, only two of them can win. Economists call this kind of structure a trilemma: a triangle of doom where improving any two corners necessarily sacrifices the third:
Demand: users who want to use the models. Growing fast. Extremely sticky. Not going away.
Supply: GPUs, TPUs, power, datacenter capacity. Fixed at any point in time. You can buy more, but there’s a lead time measured in months to years.
Quality: how good the models actually are at the thing you’re asking them to do.
Pick two. That’s how trilemmas work.
Researchers have started formalizing this. The “impossible trinity” of AI inference, where you can’t maximize quality, performance, and cost simultaneously.[2] The models deployed to millions of users will always run closer to the low end of available compute. Better versions exist. They just won’t be served at scale.
Supply is the slow variable. You can’t snap your fingers and add capacity. You raise billions, you sign deals with energy companies, you do financial shenanigans. But the hardware doesn’t arrive tomorrow. At any given moment, supply is what it is.
Demand is the fast variable, and right now it outstrips supply by a factor of ten.[3] Every developer who integrates AI into their workflow is a new unit of permanent demand. Nobody un-converts. The gap only widens.
So the companies have a choice: reject users, or lower quality. Turn people away, or serve everyone worse.
Both Anthropic and OpenAI are heading toward IPO.[4] They are structurally incentivized to never reject users. More users is the number that makes the valuation story work. It’s the golden ring. You don’t go to your Series F investors and say “we’re capping sign-ups to preserve quality.” You don’t tell Wall Street “revenue dipped because we throttled our API to keep outputs good.”
So quality is the release valve. It’s the only knob they can turn. And they’re turning it. The math is brutal: leaked financials suggest OpenAI is spending $1.69 for every dollar it earns.[5] Quality is how they’re trying to close that gap.
The models aren’t getting dumber because the research failed. They’re getting dumber because the business is succeeding.
The Fiber Parallel
We’ve seen this movie before.
Every major technology goes through two phases: an Installation Phase, when infrastructure gets built in a speculative frenzy, and a Deployment Phase, when the technology is broadly adopted. The turning point between the two is almost always a financial crash. Fred Wilson, summarizing economist Carlota Perez’s framework, put it simply: “nothing important happens without crashes.”[6]
In the late 1990s, telecom companies poured over $500 billion into fiber optic cable. The demand was real. The internet was exploding. But the investment got ahead of the economics. By 2002, less than 3% of the fiber was actually being used.[7] Companies went public on the promise of future revenue, raised more, laid more fiber, and when the music stopped, they collapsed. WorldCom. Global Crossing. The whole wave.
But here’s what matters: the fiber was still in the ground. Miles and miles of “dark fiber” — laid, tested, functional, and suddenly available at pennies on the dollar. Google started quietly buying it up in 2005.[8] Already profitable from search, already cash-rich, already patient. They used it to build the infrastructure that powered the next two decades of their dominance. Search. Gmail. YouTube. Cloud.
The demand didn’t disappear when the bubble popped. The demand was real. The investors just got wiped out, and the assets changed hands.
Jeff Bezos put it perfectly: “Financial bubbles destroy everything. Industrial bubbles make the future.”[9] The failed companies disappear, but the infrastructure remains.
Bill Gurley was even more direct: “If the wave is real, then you’re going to have bubble-like behavior.” They come together as a pair. You don’t get one without the other.[10]
Three Predictions
1. The crash is coming.
The capital growth in AI infrastructure companies is forced and inherently unstable. The top five hyperscalers are projected to spend nearly $700 billion on AI infrastructure in 2026 alone, almost doubling 2025.[11] Noah Smith, citing the 1873 railroad collapse, nailed the dynamic: “America financed its railroads faster than they could capture value.”[12] The Sears Catalog, the killer app that justified the railroads, didn’t start until 1888, fifteen years after the crash.
Even Satya Nadella acknowledges “there will be an overbuild.”[13] He frames it as a feature, not a bug: cheap capacity later. Maybe. But when CEOs start intentionally invoking the “overbuilding is fine” framework to justify spending, the line between necessary surplus and sanctioned capital destruction gets dangerously thin.[14]
The gap between valuation and sustainable economics will close violently. Early investors, especially late-stage pre-IPO and first-wave public investors, will be wiped out.
But this doesn’t mean the value disappears. The GPUs don’t evaporate. The datacenters don’t demolish themselves. The demand is real and sticky and growing — remember the ratchet. The compute becomes “dark compute”: available, functional, repriced.
2. Google wins.
Google is the only player positioned to survive the crash and acquire the wreckage.
The pure-play AI companies have a structural problem. As Benedict Evans put it: OpenAI “doesn’t have unique tech,” has no network effects, and must compete “without the cashflows or existing distribution that Google, Apple, or Microsoft can deploy in the same fight.”[15] About six organizations now ship frontier models at near-equivalent capability. The moat isn’t the model. It’s everything else.
Ben Thompson called Google “the Apple of AI,” vertically integrated from custom silicon to models to platform.[16] Their decade-long bet on TPUs is paying off. Even Anthropic is planning to use up to a million of them.[17] And the analysis from KKR is blunt: companies that rent GPUs can’t build sustainable returns. The companies that own the infrastructure capture compounding value.[18]
Google has its own silicon. Its own datacenters. Its own power contracts. It’s already profitable from businesses that don’t depend on AI revenue. When OpenAI and Anthropic are fighting for survival or getting acquired at distressed valuations, Google will be buying dark compute at fire-sale prices.
They did it before with dark fiber. They’ll do it again.
3. Apple wins too.
Added March 2026, on the back of Apple’s latest hardware announcements.
Apple signed the deal with Google. That’s one half of the bet.
In January 2026, Apple chose Google’s Gemini to power Siri, replacing OpenAI in a multi-year deal.[19] The heavy inference, the stuff that needs a datacenter, routes through Google’s infrastructure via Apple’s Private Cloud Compute layer. Apple spends a fraction of what Google spends on AI because they’re betting that cloud models become interchangeable commodities.[20]
But here’s the part most people missed this week. While headlines focused on the $599 MacBook Neo, Apple quietly shipped something more consequential: the M5 Fusion Architecture.[21] The CPUs are identical across the entire M5 Pro/Max lineup. The GPUs scale, from 16 cores to 40. And every single GPU core now has a dedicated Neural Accelerator baked in.
The Limitless podcast called it right: this is Apple’s biggest AI announcement of the week, and it isn’t the MacBook Neo.[22]
Why does this matter? Because the GPU scaling with neural accelerators in every core is a local inference platform. The M5 Max pushes 614 GB/s of memory bandwidth across 128GB of unified memory. That’s enough to run a 70B parameter model on a laptop. Locally. Over your private data. Without a single byte leaving the device.
Think about what Apple has built: a two-tier AI stack. Simple tasks, private data, sensitive queries run locally on M5 hardware and never touch a server. Complex tasks route to Gemini through Private Cloud Compute. Apple controls both paths. And the identical-CPU architecture means developers write once; performance scales with whichever GPU tier the customer bought.
They have 2.4 billion active devices. Google has the cloud compute that survives the crash. And now Apple has the silicon for local inference over private data. Together, they form the complete stack at every layer: the thing you hold, the thing that thinks locally, and the thing that thinks at scale.
Apple doesn’t need to survive the AI infrastructure crash because they were never in it. They need a cloud partner who survives it, and they chose the right one. But the really smart move is that they’re also building the hardware to need the cloud less.
The Uncomfortable Implication
If this thesis is right, then the quality degradation isn’t a temporary dip that gets fixed next quarter. It’s a structural feature of the pre-crash period. As long as these companies are optimizing for user growth over user experience (and they will, because IPO math demands it), quality will continue to erode when demand spikes.
The AI gets better when the economics stabilize. That might not happen until after the crash.
If you made it this far, you might enjoy the rest of what I write here. I’m a CTO, not a journalist. This is a hobby blog about building things with AI and noticing patterns along the way. It’s free, it’ll stay free, and I don’t post unless I have something to say.
Some previous posts that pick up threads from this one:
I Manage a Team of AI Engineers. Here’s What I’ve Learned.: I run four non-human engineers in parallel on real production work. If you’re curious what the demand side of the trilemma actually looks like from the inside, why the ratchet is real and nobody’s going back, this is that story.
My AI Pair Programmer Runs the Entire Dev Workflow: The post that started this. How I went from skeptic to having Claude Code read tickets, write PRs, and run my sprint. If you’re one of the developers who converted last month and you’re wondering whether you’re crazy, you’re not.
Subscribe if any of this resonated. I’d love to have you along for the ride.
Notes
In 2023, Stanford and Berkeley researchers showed that GPT-4’s accuracy on certain tasks dropped from 97.6% to 2.4% over three months — same model, same API. In September 2025, Anthropic published a postmortem admitting infrastructure bugs had degraded quality for up to 30% of Claude Code users. IEEE Spectrum reported that AI coding tools have hit a plateau or are declining in quality. ↩︎
A team at WiNGPT formally defines the “impossible trinity” of AI inference: model quality, inference performance, and economic cost. Epoch AI’s work on training-inference trade-offs reaches the same conclusion: “there is a tradeoff between model capabilities and scale of deployment, since inference is the dominant cost for models deployed at scale.” ↩︎
Andreessen Horowitz, “Navigating the High Cost of AI Compute”. ↩︎
Axios, February 2026: “trillions of dollars in potential value” coming up for judgment in 2026, with OpenAI preparing for a Q4 2026 IPO. Fortune documents the competitive pressure, noting OpenAI’s $500B valuation despite not expecting profits until 2030. ↩︎
Ed Zitron obtained leaked Microsoft financial documents showing OpenAI spent $8.67 billion on inference through Q3 2025 — nearly triple what was reported elsewhere. His separate analysis of unit economics found OpenAI spending $1.69 for every dollar earned, with ~910 million weekly active users and only ~5% paying. ↩︎
Carlota Perez, Technological Revolutions and Financial Capital (Cambridge University Press, 2002). Fred Wilson’s accessible summary on the AVC blog is the best introduction. See also Jerry Neumann’s deeper exposition and Chris Dixon’s application to computing. ↩︎
Doug O’Laughlin, “Lessons from History: The Rise and Fall of the Telecom Bubble”. Only 2.7% of fiber was in use in 2002; capacity had increased 186,000 times over seven years. See also Dan Runkevicius, “Is the AI boom headed for its ‘dark fiber’ moment?” — telecoms poured over $500 billion (mostly debt-financed) into fiber after the 1996 Telecommunications Act. ↩︎
Search Engine Journal, September 2005. See also Justin Kollar’s “Dark Fiber — an Archaeology of the Dot-Com Bubble” for the full story of how hyperscalers exploited the cheap surplus capacity. ↩︎
Jeff Bezos at Italian Tech Week, October 2025. CNBC coverage. He distinguished “industrial bubbles” from “financial bubbles” — in the former, “the failed companies disappear, but the inventions, tools, and infrastructure remain.” ↩︎
Bill Gurley on The Tim Ferriss Show #840, December 2025. Full transcript available. Gurley explicitly invokes Carlota Perez’s framework. ↩︎
CNBC, February 2026. Projected 2026 capex: Amazon ~$200B, Google ~$175-185B, Microsoft ~$145B, Meta ~$115-135B, Oracle ~$50B. Roughly 75% is directly AI-related. Amazon is projected to hit negative free cash flow of nearly $17B. IEEE ComSoc notes that AI-related investment has contributed more to U.S. economic growth than all consumer spending combined in recent quarters. ↩︎
Noah Smith, “The AI bust scenario that no one is talking about”, Noahpinion. His “Railroad Scenario” notes that the number of miles of railroad never stopped increasing even after the 1873 crash — it just slowed briefly and picked back up. Also see his “Will data centers crash the economy?”, which finds AI infrastructure spending as a percentage of GDP has already exceeded telecom/internet spending from the dot-com boom. ↩︎
Tom’s Hardware, November 2025. Nadella frames it positively: “I am thrilled that I’m going to be leasing a lot of capacity in ‘27, ‘28… the only thing that’s going to happen with all the compute build is the prices are going to come down.” ↩︎
Paul Kedrosky, “Why AI Capex Isn’t a Bubble: A Perez-ian Perspective”. His key warning: once CEOs begin explicitly invoking Perez’s model, capital destruction becomes “sanctified in advance.” See also Byrne Hobart & Tobias Huber, Boom: Bubbles and the End of Stagnation (Stripe Press, 2025), which argues bubbles function as coordination mechanisms — but that the mechanism only works when the overshoot is inadvertent. ↩︎
Benedict Evans, “How will OpenAI compete?”, February 2026. Evans argues there are no “fundamental moat,” “barriers to entry,” or “winner takes all effect” protecting AI companies. Foundation models have become “commodities.” ↩︎
Ben Thompson, “AI Integration and Modularization”, Stratechery, May 2024. Thompson argues that Gemini’s advantages “almost certainly required joint innovation between Google’s infrastructure team and its model-building team.” Summary freely available. ↩︎
CNBC, November 2025. Analyst Stacy Rasgon (Bernstein): “Of the ASIC players, Google’s the only one that’s really deployed this stuff in huge volumes.” ↩︎
KKR, “Beyond the Bubble: Why AI Infrastructure Will Compound Long after the Hype”. Their conclusion: physical infrastructure built during boom periods “will likely form the backbone of a new economy,” but business models that rely on renting GPUs or power won’t achieve sustainable differentiated returns. ↩︎
Fortune, January 2026. Analyst Hamza Mudassir (Cambridge) argues Apple chose Google partly because Google “controls its entire ecosystem, including proprietary cloud infrastructure and TPU chips.” CNBC reports Apple could be paying Google around $1 billion annually for AI access. ↩︎
Fortune, February 2026. London Business School analysis: Apple spends $12.7B annually on AI vs. Google’s $90B, betting models become “interchangeable commodities” while 2.4 billion active devices remain “the most valuable distribution channel in technology.” ↩︎
Apple’s M5 Fusion Architecture, announced March 2026. The M5 Pro and M5 Max share identical 18-core CPUs; GPUs scale from 16 cores (Pro) to 40 cores (Max), with a Neural Accelerator in every GPU core. The M5 Max delivers 614 GB/s memory bandwidth across 128GB unified memory. Apple Newsroom. Om Malik calls it the most consequential chip architecture shift since M1. Apple’s MLX team demonstrated 70B parameter model inference running locally on M5 Max hardware. See also Vernon Chan’s technical comparison of the M5 Pro vs. M5 Max. ↩︎
Limitless podcast, Episode 134: “Apple’s Biggest AI Announcement This Week (Not MacBook Neo)”. The hosts argue that the M5 Fusion Architecture, not the $599 MacBook Neo, is Apple’s real AI play — a local inference platform that changes what’s possible without a datacenter. ↩︎

Claude Code spends mass tokens polling for CI, logs, webhooks. Sleep. Check. Repeat.
I built a plugin that replaces all of it with real event-driven listeners.
7 sources built in. Drop in your own.
github.com/mividtim/claude-c…
What event sources would you build?
We use Reservoir extensively at Fabrica. They're a fantastic partner for keeping an NFT order book, with a fantastic and comprehensive index and API, and great customer support. Highly recommended!

Reservoir has raised a $14M Series A round led by @usv.
We’re here to build the world’s best developer tools for token trading on every chain.

Tony takes out a $200k loan against his real LA property in ten seconds.

Kudos to @ClosingBrace and @fedepo for the sick front-end design on this one! So proud to work with rockstars on an amazing product.

Instant Loans are now live on Fabrica, powered by @metastreetxyz!
This collaboration allows Fabrica property owners to borrow instantly against their property directly from our website using MetaStreet’s efficient onchain capital markets! 🌐
Tim Garthwaite retweeted

Real World Non-Fungible Assets are playing a role in growing the decentralized lending market.
These assets have a longer price history and tend to be less volatile, allowing lenders to deploy long-term loan strategies.
We continue to innovate hand in hand with @fabricaland.
Tim Garthwaite retweeted
🌍 What if buying land was as easy as ordering shoes online?
Big update: We’ve added direct bank transfers with @CoinflowLabs.

Tim Garthwaite retweeted
Copy from us: The Fabrica Trust is now open source.
Developed based on a variety of inputs and theory, and honed over five years of practice and experience, our Trust has been used in the transfer of millions of dollars worth of real estate.
Take it, use it, mess with it, improve it. ↓

