

India
Joined July 2014
- Tweets220
- Following225
- Followers153
- Likes293




Pinned Tweet
For a year I've been writing a book and not telling anyone. Today it goes live.
📚 Quantization and Fast Inference with Manning Publications Co.
🎉 50% off site-wide through May 19.
---
LINKS
✨ MEAP: hubs.la/Q04ff8Jh0

1
3
157
Vivek Kalyanarangan retweeted

More and more people and companies are convinced that open-source models and custom SLMs are the way to go for serious projects.
@ManningBooks is offering a free eBook, Local AI and Small Language Models, with four chapters on how to choose, adapt, run and build with them. 🧵


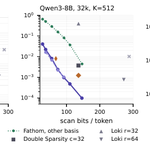
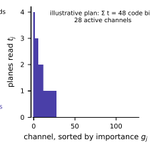
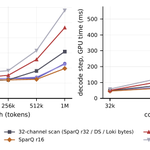
Your agent's KV cache moved to host RAM because it stopped fitting on the GPU.
At 1M tokens the index scan that ranks the keys moves 5.1 GB per decode step.
The winner rows everyone optimises move 200 MB.
We were tuning the wrong 4%. (1/9)

1
57
That is not an A100 quirk. Counting INT32 lanes against bandwidth, an A100 gives ~5 integer ops per byte and an H100 about the same.
If your index is resident, this buys you nothing. If it is offloaded, bytes are time.
Know which one you are. (8/9)
1
8
Paper: arxiv.org/abs/2609.17652
Code and results on rented A100s: github.com/vivekkalyanaranga…
Every table and figure in the paper regenerates from those JSONs with two scripts. (9/9)

6
Qwen3.8-27B ranges from 54.7GB at BF16 down to 9.01GB at 2-bit, a 6.07x compression. The 4-bit UD-Q4_K_XL variant at 17.9GB fits a single 24GB GPU. I walk through this single GPU tradeoff in Chapter 12 of Quantization and Fast Inference - manning.com/books/quantizati…

59
Vivek Kalyanarangan retweeted
HALF OFF our new MEAP, only on May 8th!
Today, you can SAVE on Quantization and Fast Inference by Vivek Kalyanarangan @vivk1988 and other related titles: hubs.la/Q04fZGxQ0
From quantization fundamentals to runtime packaging, the book provides a comprehensive overview of the quantization pipeline.

I rewrote Python's validators library in Rust - 29x faster, drop-in replacement - just a one-line change required
47x on IPv4, 35x on URL, 28x on email
48 validators, 370 tests
PyPI: pypi.org/project/rapidvalida…
GitHub: github.com/vivekkalyanaranga…
#rustlang #python #pyo3
Exploring the Latest Advancements in AI Research: A Deep Dive into Five Groundbreaking Papers link.medium.com/ml4sGU7AINb
🚀 Exciting AI Breakthroughs: A Deep Dive into 5 Groundbreaking Papers! 🚀

1
706
Vivek Kalyanarangan retweeted

#FAB has introduced a powerful new security tool – Voice Biometrics. It uses your unique voice to serve as a simpler, safer authentication method for banking over the phone. To register your voiceprint, call 600 525500 or visit https://teapawt.org/t.co/Iic6nHdeHE for more info.
