

Research Scientist @GoogleDeepMind. web: https://teapawt.org/t.co/k82gdP7MSc
San Francisco Bay Area 🇺🇸
Joined March 2011
- Tweets57
- Following217
- Followers186
- Likes260




Glad to have contributed a tiny bit to this report -- it's a great read!

We did a lot to understand Gemini 4's capabilities and propensities, and to improve our mitigations for this launch -- you can get a tl;dr here blog.google/innovation-and-a… and dive into the report storage.googleapis.com/deepm…

105
In the era of GenAI, cyberattacks are cheaper, faster and easier to scale.
This is why Gemini 4 Argon was trained with defensive cybersecurity as a core focus. Grateful to have worked on this with an amazing team! ♊️🚀

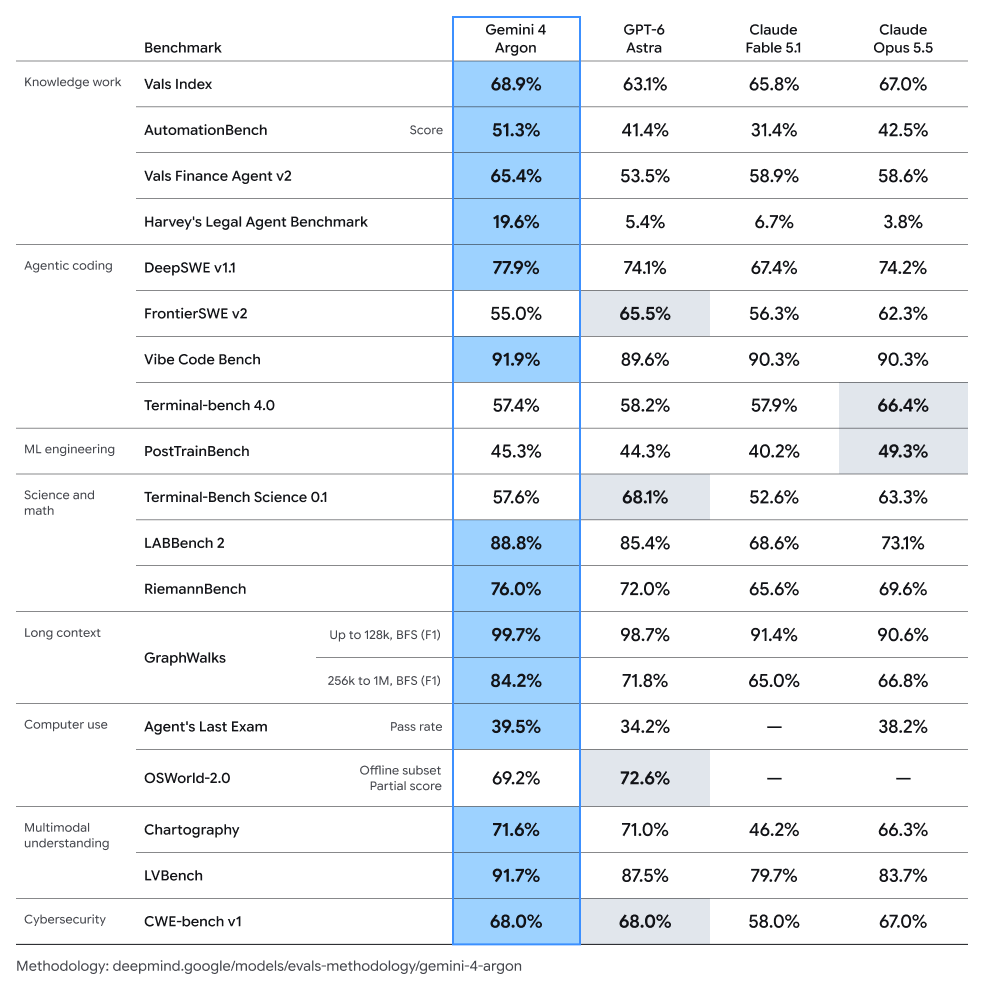
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
1
7
334
Excited to share what our team’s been cooking 🧑🍳 🚀

Today we’re launching Gemini 3.8 Flash Cyber and Gemini 3.8 Flash. ⚡️🛡️
3.8 Flash Cyber is our most capable cybersecurity model for finding and fixing vulnerabilities. It sits on the Pareto Frontier on CWE-Bench for patching. Available to trusted defenders through our new Fairwind Program.

1
8
818
Xingchen Wan retweeted

✈️Arrived in Rio🇧🇷 for #ICLR2026 this week!
Thrilled to present our work:
1. Visual Planning: Let's Think Only with Images
@ Oral Session 3D Vision language models II
Fri 24 Apr 10:30; Poster P4-3304
2. Multi-Agent Design
Sat 25 Apr 10:30, P4-4713
Looking forward to a chat!

Xingchen Wan retweeted

🚨 Google just dropped the most advanced self-improving video AI ever built.
It’s called VISTA, and it literally rewrites its own prompts to make every new generation better than the last.
No retraining. No fine-tuning. Just pure test-time self-reflection.
Here’s how it works:
→ Turns your idea into a full scene-by-scene storyboard
→ Generates multiple video candidates
→ Runs a tournament to find the best one
→ Then critiques itself visually, audibly, contextually before trying again
Each loop = sharper visuals, tighter storytelling, more aligned motion.
The results? 60% win rate vs Veo 3 and 66.4% human preference.
This isn’t “text-to-video.”
This is video that learns from itself.


Xingchen Wan retweeted
Automating Multi-Agent Design:
🧩Multi-agent systems aren’t just about throwing more LLM agents together.
🛠️They require mastering the subtle art of prompting and agent orchestration.
Introducing MASS🚀- Our new agent optimization framework for better prompts and topologies!

Xingchen Wan retweeted

🚀Let’s Think Only with Images.
No language and No verbal thought.🤔
Let’s think through a sequence of images💭, like how humans picture steps in their minds🎨.
We propose Visual Planning, a novel reasoning paradigm that enables models to reason purely through images.

Xingchen Wan retweeted

Astute RAG
Proposes a novel RAG approach to deal with the imperfect retrieval augmentation and knowledge conflicts of LLMs.
Astute RAG adaptively elicits essential information from LLMs' internal knowledge. Then it iteratively consolidates internal and external knowledge with source-awareness.
Astute RAG is designed to better combine internal and external information through an interactive consolidation mechanism (i.e., identifying consistent passages, detecting conflicting information in them, and filtering out irrelevant information). (Prompts for this step provided in the paper)
The explicit consolidation step addresses knowledge conflicts which is probably one of the most challenging parts of building reliable RAG systems. It really does help to know how to leverage the internal and external information of RAG systems.

Curious about getting AI to think more like us? Discover how to tune your prompts for better alignment with human judgment! 🧠💡
arxiv.org/abs/2406.11370

Which output is better?
[A] or [B]? LLM🤖: B❌
[B] or [A]? LLM🤖: A✅
Thrilled to share our preprint in addressing preference biases in LLM judgments!🧑⚖️We introduce ZEPO, a 0-shot prompt optimizer that enhances your LLM evaluators via fairness⚖️
📰Paper: arxiv.org/abs/2406.11370

Xingchen Wan retweeted

For batch active learning, how can the algorithm determine the batch size? Use computational uncertainty via kernel quadrature! Check out our new AISTATS paper with @maosbot, @JorgensenMart, @wanxingchen_, @nguyentienvu!🎉 #ProbabilisticNumerics
paper: arxiv.org/abs/2306.05843
Xingchen Wan retweeted
#ICLR2024 Proud that 🚀Batch Calibration🚀 is accepted at @iclr_conf!
🔥Batch Calibration addresses the prompt sensitivity of LLMs and enhances LLMs' robustness to ICL orders, prompt templates, and ✔️❌choice of verbalizers even in emojis👍👎
📙Paper: arxiv.org/abs/2309.17249
Xingchen Wan retweeted

Visit the #EMNLP2023 Google booth today at 3:30 PM to learn about Universal Self-Adaptive Prompting, an automatic method tailored for zero-shot learning (while compatible with few-shot) that uses a small amount of unlabelled data & an inference-only LLM.
Introducing COSP and USP: they select good demos from unlabeled samples & LLMs’ self-generated outputs as in-context examples to achieve stronger zero-shot performance 💪
Paper: arxiv.org/abs/2305.14106 (COSP: ACL Findings) + arxiv.org/abs/2305.14926 (USP: EMNLP)

Introducing a new approach for adaptive prompting of #LLMs that train with unlabeled samples + pseudo-demonstrations generated by the model itself to close the gap between few-shot and 0-shot performance on reasoning, NLU and language generation tasks. → goo.gle/3tY00IB
Work done with @ruoxi_cc Hootan Nakhost @hanjundai @eisenjulian @sercanarik @tomaspfister. Thanks to all my amazing co-authors 🙌
Xingchen Wan retweeted
🤔Curious about an efficient way to automatically find better prompts for your LLM? Thrilled to Introduce “ClaPS” which underscores the critical role of search space in prompt search accepted to #EMNLP Findings🎉.
📎Code: github.com/cambridgeltl/ClaP…
📷Paper: arxiv.org/abs/2310.12774

Check out Batch Calibration!
Blog: goo.gle/45wlYj0
Paper: arxiv.org/abs/2309.17249

LLMs’ sensitivity to design decisions, such as template choice, can degrade performance & prevent their robust application. Introducing Batch Calibration, a simple method that mitigates this effect & improves on existing methods w/ negligible add’l cost → goo.gle/45wlYj0
6
614
1/5 Wondering how to do better than “Let’s think step by step” in zero-shot? Enter COSP, a prompting technique that massively improves reasoning over 0-shot-CoT & matches few-shot in 3 LLMs – a work done during my internship at @Google & accepted to #ACL2023NLP Findings🤩

ALT Comparison of performance between 0-shot-CoT, 0-shot-COSP and few-shot-CoT.
4/5 We thus use entropy (and a repetition penalty) to craft a scoring function. We run zero-shot-CoT, score the outputs and determine which outputs should serve as the LLM’s in-context demos – all done using unlabelled data & LLM’s outputs & no more laborious handcrafting 🎯

ALT Overall pipeline of COSP
1
4
490
5/5 We evaluate COSP on three different LLMs in the zero-shot setting over 6 tasks to show vast improvement.
Paper: arxiv.org/abs/2305.14106.
Many thanks to my fantastic coauthors: @ruoxi_cc, @sercanarik, @hanjundai and @tomaspfister.🤝
1
6
353