

한국 시간으로 새벽에 눈 비비며 AI 뉴스를 찾다가 그록봇을 만나 자동 카드뉴스 발간 방식으로 바꾸고 이를 많은 사람과 나누다.
Joined October 2025
- Tweets2.1K
- Following951
- Followers767
- Likes2.4K



Sunny_news retweeted

이번주 그록봇 동향입니다.
11/14일 하니스 최적화로 사용량이 늘었다는 머스크의 공유가 가장 눈에 띕니다.
봇템플릿을 유료화할 수 있는지는 아직 의문인 것 같습니다.
성능개선 및 최적화(하니스개선 등)/기능추가(화상회의 참여가능) 등이 동시에 진행되고 있는 것으로 보입니다.
[1/6]
지난주 Grok Bot은 개인 비서에서 팀원으로 포커스를 옮긴 한주.
• 11/10 새벽 주간 한도 전원 리셋으로 시작함
• 11/12 1.0 정식 출시, 봇 공유·Slack/Teams·회의 참석이 한 번에 들어옴
• 11/14 Sam Sokolin이 하니스 최적화로 사용량 약 7%, 루틴은 최대 약 15% 더 쓰게 됐다고 밝힘
• 한국 사용자들은 사용량 화면 쪼개 보기와 루틴 간격 줄이기에 집중함
요약하면 기능은 팀 단위로 커졌고 한도는 조금 숨통이 트임 🧵
[2/6]
공식 발표만 추려도 일정이 빡빡했음 (날짜는 한국시간).
• 11/11 Tailscale: 개인·회사 tailnet에 봇을 붙여 사내 MCP 서버와 내부 도구에 접근
• 11/12 Grok Bot 1.0: 봇 공유, Slack·Teams 협업, 팀원이 가르친 내용은 Review learnings에서 승인 후 반영
• 같은 날 Gopuff 연동으로 식료품 주문을 끝까지 맡김
• 11/13 Mac 앱이 메시지·메일·메모·미리알림·캘린더·위치·연락처를 쓰게 됨
1.0 소개 글은 노출 5,570만 회를 넘김.
[3/6]
가장 눈에 띈 건 회의 참석.
• Google Meet·Zoom·Teams 링크를 봇 채팅에 붙이고 참석을 요청하면 됨
• 승인 카드를 누르고, 회의가 열리면 호스트가 대기실에서 들여보내는 구조
• 이름 뒤에 transcribing이 붙고, 회의 채팅에서 이름을 부르면 답함. 끝나면 요약과 할 일 목록을 보냄
• Team·Enterprise·Ultra 요금제 한정, 답변 없이 받아 적기만 하는 모드도 있음
참석자에게 미리 알리는 건 결국 사람 몫으로 남음.
[4/6]
한도 쪽은 지난주보다 분위기가 나아짐.
• @bot이 11/10 04:17 한도 전원 리셋을 알렸고 좋아요 3.9만 개가 붙음
• 11/14 Sam Sokolin의 최적화 발표를 머스크가 인용하며 다시 퍼짐
• 루틴 비중이 큰 사용자일수록 체감 폭이 클 것이라는 반응이 많았음
• 다만 리셋 뒤에도 한도가 금방 찬다는 불만은 국내외에서 계속 올라옴
7%는 작아 보여도 매일 도는 루틴이 많으면 한 주 끝자락에서 차이가 남.
[5/6]
미국에선 템플릿으로 돈을 받는 실험도 시작됨.
• X의 Grok Bot Template Rewards 파일럿, 초대받은 미국 크리에이터 대상
• 좋아요나 조회수가 아니라 다른 사람이 템플릿을 실제로 쓰고 계속 쓰는지를 봄
• 2주 단위 재량 지급, X Money로 받는 방식이라는 설명이 나옴
• 국내에선 @GoGoSing9to6가 "글이 아니라 봇 템플릿에 돈을 주는 구조"로 정리해 소개함
한국 확대 여부는 아직 공지된 게 없음.
[6/6]
국내 얼리어답터들은 이번 주 운영 쪽에 힘을 줌.
• @gimgyeo95290164: 데스크톱 설정의 사용량 화면에서 나·루틴·봇 간, 봇별로 나눠 보는 법 공유
• @charlychoi: 사용량이 빨리 닳으면 루틴 간격, 불필요한 일정, Slack 트리거 범위부터 보라고 정리
• @window98se: 뉴스 카드 작업을 다른 코딩 도구로 넘겨 쿼터를 아끼려 했지만 18회 중 8회 미완으로 실패했다는 실험기
• 공통 결론은 봇을 늘리기보다 어디서 새는지부터 찾자는 쪽
팀원이 된 봇일수록 일하는 시간표부터 다시 짜야 함.
출처: @bot 공식 게시물(11/10~11/14 KST), SpaceXSI 문서·변경 기록, @SamSokolin 11/14 게시물, @grok 답글(템플릿 보상 설명), @GoGoSing9to6·@gimgyeo95290164·@charlychoi·@window98se X 게시물. 발행 전 원문 확인.
#GrokBot #AI에이전트 #GrokBot1_0 #자동화

그록봇을 다방면으로 사용하시는 분들은 저장공간에 대한 정책과 관리를 미리 지정해두시는게 좋겠습니다.
어제 저녁무렵 갑자기 그록봇이 컴퓨터의 저장공간 부족을 알려왔습니다.
그 전부터도 정리를 간혹 지시했었는데 이번에 개발중이던 작업때문인지
갑자기 저장공간이 찼나봅니다.
그런데 그 이후 컴퓨터 재부팅도 리셋도 먹통이 되었습니다.
[email protected] 로 증상을 보내고 ai상담사가 붙었지만 해결되지 않았습니다.
Ai상담사는 인간 진단팀에게 이 일을 이관했고 몇일 걸릴 수 있다고 하네요
해결 과정의 이야기를 답글로 적어드리겠습니다.
모두 조심하세요!
8
텐센트 훈위안, 실시간 음성 모델 Hy Realtime 공개: 흐린 말·고쳐 말하기도 의도 파악, 대화 중 스스로 웹 검색, 노래까지. 위안바오 음성통화에 적용, 클라우드 API는 곧. 벤치마크는 텐센트 자체 수치.
ithome.com/1/026/825.htm

1
9
Tencent Hunyuan launched Hy Realtime, a real-time voice model that recovers intent from messy speech, runs web searches mid-chat on its own, and sings. Live in Yuanbao voice calls; Cloud API soon. Benchmarks are Tencent's own.
ithome.com/1/026/825.htm

5
Cursor 10월 침해 사고 조사 결과: Cursor가 Fireworks에 준 키가 노출돼 코딩 에이전트 기록이 복사됐고, 기록 속 인증정보로 10/29 가짜 Claude Code 확장(2.1.312·2.1.313)이 약 11시간 배포(최대 5,000명). 설치했다면 삭제만으론 부족할 수 있음.
cursor.com/blog/security-inc…

2
1
33
Cursor's breach post-mortem: a key it issued to Fireworks was exposed, agent traces were copied, and credentials in them led to a fake Claude Code extension (2.1.312/2.1.313) served ~11h on Oct 29 to up to 5,000 users. Uninstalling may not be enough.
cursor.com/blog/security-inc…

5
Artificial Analysis 코딩 에이전트 지수 v2.1 공개: 더 어려워진 FrontierCode 2.0·Terminal-Bench 4.1을 반영해 Claude Fable 5.2와 Opus 5.5가 58점 공동 1위. 과제당 비용은 구성별로 최대 약 30배 차이.
teapawt.org/ArtificialAnlys/status…


Announcing Artificial Analysis Coding Agent Index v2.1, upgrading FrontierCode and Terminal-Bench. Claude Fable 5.2 and Claude Opus 5.5 share the lead at 58
The Coding Agent Index measures models in agent harnesses; v2.1 of the Index upgrades FrontierCode from 1.1 to 2.0 and Terminal-Bench from 4.0 to 4.1.
Upgraded:
➤ FrontierCode-AA 2.0 (replacing FrontierCode v1.1): our implementation of Cognition's FrontierCode 2.0, comprising 132 real-world coding tasks graded on whether a repository maintainer would merge the agent's change
➤ Terminal-Bench 4.1 (replacing Terminal-Bench 4.0): the same 66 tasks, scored with updated verifiers that improve reliability and resistance to reward hacking
Staying in the Index: SWE-Atlas-QnA-AA
Key results:
➤ Claude Fable 5.2 and Claude Opus 5.5 share the lead at 58: Claude Fable 5.2 scores 58 at both xhigh and high in Claude Code. Claude Opus 5.5 (max) scores 58 in Claude Code and, paired with GPT-6 Luna High, in Cognition's multi-model harness Devin Fusion CLI. Claude Fable 5.2 (max) scores 56 as more of its attempts hit task time limits. Claude Sonnet 5.5 (max, 56) in Claude Code and Gemini 4 Carbon (high, 55) in Antigravity CLI follow
➤ Index scores are lower in v2.1, driven by the upgrade to FrontierCode-AA 2.0: models score lower by 5 points on average. Codex with GPT-6.1 Terra (max) is the only configuration which didn’t fall between versions, sitting within 1 point of its prior score
➤ Cost per task varies ~30x among configurations scoring 48+: from $1.51 for Codex with GPT-6.1 Sol (max, 52) to $44.22 for Claude Code with Claude Fable 5.2 (max, 56)

1
9
Artificial Analysis Coding Agent Index v2.1: with tougher FrontierCode 2.0 and Terminal-Bench 4.1, Claude Fable 5.2 and Opus 5.5 tie for #1 at 58. Cost per task varies up to ~30x across top setups.
teapawt.org/ArtificialAnlys/status…

Announcing Artificial Analysis Coding Agent Index v2.1, upgrading FrontierCode and Terminal-Bench. Claude Fable 5.2 and Claude Opus 5.5 share the lead at 58
The Coding Agent Index measures models in agent harnesses; v2.1 of the Index upgrades FrontierCode from 1.1 to 2.0 and Terminal-Bench from 4.0 to 4.1.
Upgraded:
➤ FrontierCode-AA 2.0 (replacing FrontierCode v1.1): our implementation of Cognition's FrontierCode 2.0, comprising 132 real-world coding tasks graded on whether a repository maintainer would merge the agent's change
➤ Terminal-Bench 4.1 (replacing Terminal-Bench 4.0): the same 66 tasks, scored with updated verifiers that improve reliability and resistance to reward hacking
Staying in the Index: SWE-Atlas-QnA-AA
Key results:
➤ Claude Fable 5.2 and Claude Opus 5.5 share the lead at 58: Claude Fable 5.2 scores 58 at both xhigh and high in Claude Code. Claude Opus 5.5 (max) scores 58 in Claude Code and, paired with GPT-6 Luna High, in Cognition's multi-model harness Devin Fusion CLI. Claude Fable 5.2 (max) scores 56 as more of its attempts hit task time limits. Claude Sonnet 5.5 (max, 56) in Claude Code and Gemini 4 Carbon (high, 55) in Antigravity CLI follow
➤ Index scores are lower in v2.1, driven by the upgrade to FrontierCode-AA 2.0: models score lower by 5 points on average. Codex with GPT-6.1 Terra (max) is the only configuration which didn’t fall between versions, sitting within 1 point of its prior score
➤ Cost per task varies ~30x among configurations scoring 48+: from $1.51 for Codex with GPT-6.1 Sol (max, 52) to $44.22 for Claude Code with Claude Fable 5.2 (max, 56)
5
에이전트 개발 도구 LangChain, 기업가치 30억 달러로 3억 달러 C 시리즈 유치(CapitalG 주도). 에이전트 실행·개선·관리 플랫폼 LangSmith에 투자, 7,000곳 넘는 조직이 사용 중(회사 발표).
langchain.com/blog/series-c
teapawt.org/hwchase17/status/21212…


Today we announced that LangChain raised $300M at a $3B valuation.
We think agents will transform the economy, and the companies that own their intelligence will build lasting competitive advantages.
That's why we're building LangSmith, the framework-agnostic platform to run, improve, and govern agents.
Still so much left to build! More on what’s next: langchain.com/blog/series-c
1
9
LangChain raised a $300M Series C at a $3B valuation, led by CapitalG, to build out LangSmith, its platform to run, improve and govern agents. The company says 7,000+ organizations use it.
langchain.com/blog/series-c
teapawt.org/hwchase17/status/21212…

Today we announced that LangChain raised $300M at a $3B valuation.
We think agents will transform the economy, and the companies that own their intelligence will build lasting competitive advantages.
That's why we're building LangSmith, the framework-agnostic platform to run, improve, and govern agents.
Still so much left to build! More on what’s next: langchain.com/blog/series-c
3
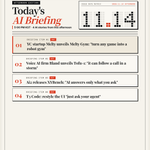
11/14 오후 5시 AI 브리핑 · 오후 소식 4건
1. YC 스타트업 Melty, 게임을 로봇 훈련장으로(Melty Gym)
2. Bland, 음성-음성 모델 Tofu-1 공개
3. Ai2 XYBench: AI는 '잘못된 질문' 뒤 진짜 목표를 놓친다
4. T3 Code, 말하면 에이전트가 UI 테마 변경(실사용)
1
33
English cards: cover + stories 1-3
① Melty Gym (YC) ycombinator.com/launches/XT3…
② Bland Tofu-1 bland.ai/speech-to-speech
③ Ai2 XYBench allenai.org/blog/xybench


1
4
Story 4 (practical)
④ T3 Code custom themes github.com/pingdotgg/t3code/…
Nightly build, not a stable release

2
11/14 낮 12시 AI 브리핑 · 오전 소식 5건
1. 연준 보고서, AI 컴퓨팅 부채 6,800억 달러+ 경고
2. 매체 3,000곳 AI 콘텐츠 일괄 라이선스(ILC) 출범
3. 오픈AI, 로봇 전담팀 해체
4. 크래프톤 온디바이스 LLM Raon-1 nano(실사용)
5. 코딩 하네스 Reason 출시(실사용)
1
57
English cards: cover + stories 1–3
① Fed Financial Stability Report federalreserve.gov/publicati…
② ILC launch internetcollective.org/press…
③ OpenAI robotics (Fortune) fortune.com/2026/11/13/opena…


1
8
Stories 4–5 (practical)
④ Raon-1 nano huggingface.co/KRAFTON/Raon-…
⑤ Reason reasonmachines.com/blog/laun…
Reason figures are company-reported


7