
bay area's startup/tech baker, prev founding @abundant_labs, @fdotinc, product @NimbleRx, on leave from school
Joined August 2023
- Tweets561
- Following509
- Followers492
- Likes1.9K





Pinned Tweet
Everyone is trying to build the next unicorn startup
Well, I’m trying to build the biggest tech baking empire the Bay Area has ever seen! Welcome to my journey of baking for the hottest unicorn startups in SF
Thanks @vercel for letting me bake for the team. Tag any startups down below if you want me to bake for them!


Daniel Wang retweeted

Human researchers decide everything from compute and data spend to what experiments to run. To replace them, models need this judgement.
We’re introducing FrontierML, a benchmark testing how well agents use money to scale model performance on 21 challenging, end-to-end ML tasks.

Daniel Wang retweeted

Introducing interfaze-1-lite, the first general open-weight model for deterministic work
OCR, speech-to-text, extraction, classification and more
It returns confidence scores and metadata like bounding boxes on every run
huggingface.co/interfaze-ai/…
Readers added context they thought people might want to know
Interfaze appears to have copied the Chandra OCR 2 model, renamed it, and changed the license, without disclosing that the model is not orginal. See x.com/VikParuchuri/s…


Daniel Wang retweeted

just shipped an app for you to measure which models are capable of taking your job (for free)
you can test real knowledge work tasks across over +1500 different apps (slack, google docs, gmail, etc)
compare performance across
> time
> tokens
> tool calls
comment below which models you want me to add!
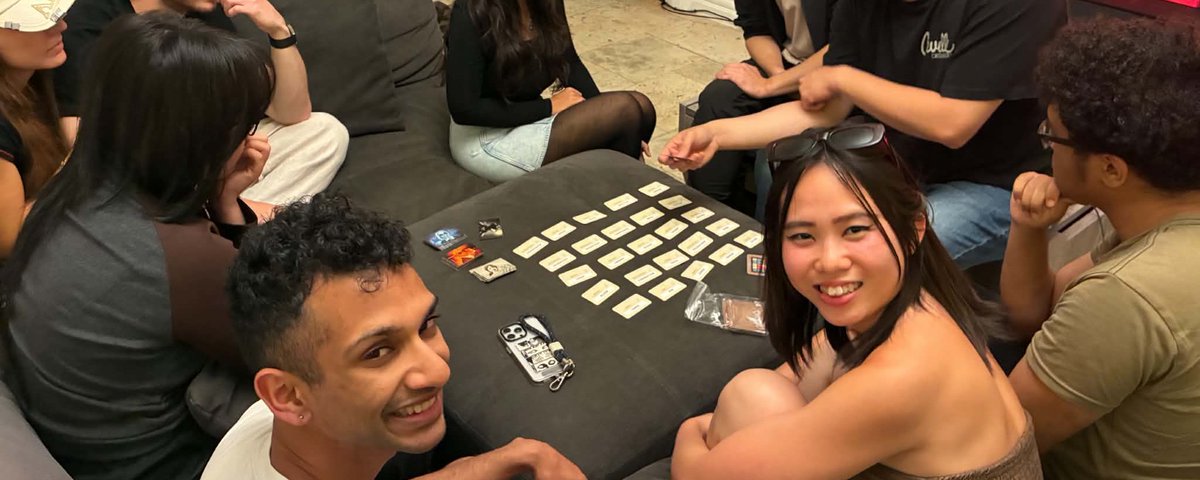
What type of cake would a model bake for its own celebration?
Gemma just hit 1 billion downloads, so I got to bake big something for the occasion 🎂
Shout out to @vadiamit @osanseviero and the rest of the @GoogleDeepMind team for the inviting me back again and here’s to the next billion 🚀
Props to all the mobile CapCut editors I just spent the last three hours moving overlays around cause there ain’t no batch editing
1
2
398
Daniel Wang retweeted

Today we’re announcing r-1, our new document parsing model. It’s more accurate than our most powerful agentic OCR models, faster, and up to 6x cheaper.
At @reductoai, we spent two years building specialized models for complex visual layouts, tables spanning multiple pages, and key formatting like strikethroughs. We then used everything we learned to build r-1, the first in a new generation of models designed to handle the hardest documents without multiplying cost.
This early preview delivers a 20% lower error rate than our most accurate legacy agentic models and will keep improving with new checkpoints over the next few weeks.
Accuracy is only the beginning. r-1 preview is available at 1¢ per page all-in, with additional volume discounts as you scale. In the near term we’re also going to release r-1 mini, and an auto mode that intelligently selects the right approach for each page.
If you’re currently using another parser, we’re offering up to $5,000 in credits to evaluate and migrate. You can claim the migration offer and learn more about r-1 using the links in the comments.
Happy parsing!

Daniel Wang retweeted
We’re introducing intrinsic discovery, a new learning method that allows models to explore and learn from open-ended environments without human supervision.
Using intrinsic discovery, we trained a world model that surpasses GPT-5.6 Sol at simulating terminal environments.
Daniel Wang retweeted
Big labs don’t have a monopoly on AI research.
More than 20 YC startups have published research recently at top conferences like NeurIPS, ICLR, and ICML.
empirical.health/blog/yc-sta…

Daniel Wang retweeted

Why have SWE benchmarks converged on contrived tasks that are hard for hard’s sake?
New essay on how we got here, and why we need to rethink benchmarks from the ground up.


