

Building engineering intelligence @ https://xitter.cf/t.co/yBzVXLL5ly
Joined January 2024
- Tweets907
- Following9
- Followers5.1K
- Likes3.9K






Pinned Tweet
We’re hiring an SDR at Entelligence AI.
You’ll sell to VPs of Engineering, CTOs and platform leaders at companies running coding agents at scale.
Looking for someone with 1-3 years of SDR experience, or a technical background moving into sales, who understands code review, token spend and model routing.
You’ll work directly with the founding team and CEO.
Apply link below 👇

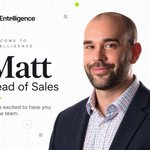
Super excited to have you join the team @MattsSchtick!
Matt joins us with over 20 years of experience leading enterprise sales teams across Zendesk, SullyAI, Prezi and AnswerIQ.
He's picked up the entire platform in days, has lead both PLG and sales led motions at scale and brings all his experience working at early stage and growth stage companies.
We're super excited to see you lead our growth and sales org!
🤖 Made with AI

Entelligence AI retweeted

Engineering leaders are all running into the same process and road blocks with optimizing their engineering agents -
1. Get cost visibility and basic engineer level caps
2. Build an ad hoc system to try to trace it to ROI
3. Face challenges before getting to a unified learning loop
Presented our approach to these challenges at the Silicon Valley AI hub! Thanks to @shilpinayak


Entelligence AI retweeted
want to help make AgentPlay support more coding agents?
we've opened up issues for Windsurf, Amp, Roo Code, Cline, Aider and Gemini CLI
if you use any of these, we'd love your contributions 👇


want to help make AgentPlay support more coding agents?
we've opened up issues for Windsurf, Amp, Roo Code, Cline, Aider and Gemini CLI
if you use any of these, we'd love your contributions 👇
Entelligence AI retweeted

Entelligence AI open-source agentplay: See and replay your coding agent sessions as a map and a timeline
→ Replay what it read, what it edited, what failed, and what it shipped
→ Local, open source, works across Claude Code, Codex, Cursor, Copilot, OpenCode, and Kiro
→ One command [𝗎𝗏𝗑 𝖺𝗀𝖾𝗇𝗍𝗉𝗅𝖺𝗒] to find the agent sessions already on your machine, build a redacted replay of each one, and open a local viewer
More info: aideveloper44.com/product/ag…
@EntelligenceAI | #opensource #codingagent
Entelligence AI retweeted
coding agents do a LOT behind the scenes
AgentPlay lets you explore and replay the entire session as an interactive map
every tool call, error, file change and subagent, all in one place
AgentPlay is open source. try it out 👇
coding agents do a LOT behind the scenes
AgentPlay lets you explore and replay the entire session as an interactive map
every tool call, error, file change and subagent, all in one place
AgentPlay is open source. try it out 👇
try AgentPlay with your own coding agent sessions 👇
github.com/Entelligence-AI/a…
Entelligence AI retweeted
What's the craziest session you've run?
Seeing some crazy things so far -
- 112 PRs created from 1 session
- 33x compaction in a session
- 44 subagents in a session
github.com/Entelligence-AI/a…

Entelligence AI retweeted
If an eng burns $1k on a session across 119 hrs but creates 25 PRs from it... 😭
Doing some interesting analysis into how much more or less efficient super long sessions with a lot of PRs are compared to shorter 1 PR sessions


Entelligence AI retweeted
Friday evening experimentation 🫡
Huge shoutout to @sumitmishra2026 for the rigor behind our self-improving coding agent harness
20+ experiments a day. Every historical PR comment replayed as an eval case
Nearly 40% of real review comments prevented, up from 13%. 80%+ next!

Entelligence AI retweeted

continual learning. RSI.
Good times ahead!!

Introducing AgentPlay 🚀
The future of coding is self improving coding agent harnesses that help agents avoid making the same mistakes over and over.
Turn your existing Claude Code, Codex, Cursor and Copilot sessions into interactive maps and replayable timelines.
See what your agent explored, where it failed, what it retried and how it reached the final change
Free, local and open source.
GitHub: github.com/Entelligence-AI/a…
Entelligence AI retweeted
ELC day 1 ✅
Just engineering ROI and cost visibility is no longer enough
Engineering organizations want engineering agents that continuously optimize, learn from historical errors and build organizational context


Entelligence AI retweeted
Every platform out there claims to provide data and visibility into your AI spend.
What about actually using all that data to directly optimize your agents?
Come by our booth tmrw at ELC and check out how we do it at @EntelligenceAI !

Entelligence AI retweeted
Finally rolling out the full Agent Session Explorer OSS next week 👀
Visualize every coding agent trace
Identify root cause errors
Feed it back to your coding agents to improve with every agent trace
Entelligence AI retweeted
Killer conference at SheTO last week. Packed with top women tech execs sharing their top of mind concerns with growing and’s scaling their companies and teams
Smaller conferences targeted on your ICP are often the best to double and triple your funnel


Entelligence AI retweeted
Lots to learn from this approach - aggregating insights across multiple coding agent harnesses to continuous improvement loops is definitely the next step
Few interesting insights -
- Harness rankings don't transfer between models. Codex was the 2nd-best harness for GLM-5.2 and the 9th-best for Gemma 4
- GLM-5.2 scores 23% on SWE-bench Pro in one harness and 52% in another
Optimizing across harnesses is the only solution

We turned Claude Code, Codex, Hermes, Pi, @opencode and other coding harnesses into RL environments. No changes to the harnesses, no changes to the training code. Any open model, any task set, fully open source my friends!
Same model, same weights: 62% under Mini-SWE-Agent, 33% under Claude Code. But training inside a real harness normally means reimplementing it as an environment, so most models get trained in a scaffold nobody actually ships.
The fix is a proxy, not a rewrite. The harness thinks it's talking to a model API. It's actually talking to a capture proxy that speaks the 4 formats coding agents use (OpenAI Chat Completions, OpenAI Responses, Anthropic Messages, Gemini), forwards to @vllm_project, records the exact token IDs and logprobs vLLM sampled, and hands TRL sequences it can train on. The harness becomes the environment. 10 harnesses run through it today, none modified.
And because you control the reward, you can shape behavior the harness never asked for. We added a small bonus for solving a task in fewer tool calls: on tasks it already solved, the model now uses 31% fewer calls, in every harness, and about half under Codex.
Tested on LFM2.5-2.6B from @liquidai:
→ Train in one harness: better mostly in that harness (OpenCode 34% → 58%).
→ Train in 4 at once: better in all 4 (42% → 54%).
→ SFT on 3,189 rollouts from Qwen3.8-27B instead: plateaus at 47.5%, below both RL runs.
Everything is open and reproducible: the capture proxy in OpenEnv, the trainer in TRL, the tasks, the SFT data, the training code and all 7 trained models. Bigger models and bigger runs next.
Full guide: huggingface.co/spaces/FineEn…
