

A high-throughput and memory-efficient inference and serving engine for LLMs. Join https://xitter.cf/t.co/lxJ0SfX5pJ to discuss together with the community!
Joined March 2024
- Tweets1.4K
- Following36
- Followers52.8K
- Likes686





vLLM 🤝 TPU
🚀 Native PyTorch serving on TPUs is here! Built with @Google and @inferact, vLLM-TorchTPU brings familiar PyTorch tools to TPU inference, with prefix caching, speculative decoding, and disaggregated serving.
🛠️ Excited to keep building with the community!

Native PyTorch on TPUs is here—and TorchTPU is officially open source.
Train and serve models using the tools you already know: @vllm_project, @sgl_project, @_llm_d_, TorchTitan, @huggingface, and @raydistributed.
Learn more from #PyTorchConf2026 → goo.gle/4hWxEVH

vLLM retweeted
Day-0 support for @Recursive_SI's Flint is here in vLLM! 🚀
40B parameters, just 2.5B active per token. Thanks to the small size, our custom NVFP4 kernels push it to 500 TPS on a single GB200, even at 100K context without speculative decoding.
Both NVFP4 and BF16 are ready to run today! vllm.ai/blog/2026-10-21-flin…


Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine.
• Best-in-class fast local coding
• Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark
• Built from scratch in under 4 months
Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
Day-0 support for @Recursive_SI's Flint is here in vLLM! 🚀
40B parameters, just 2.5B active per token. Thanks to the small size, our custom NVFP4 kernels push it to 500 TPS on a single GB200, even at 100K context without speculative decoding.
Both NVFP4 and BF16 are ready to run today! vllm.ai/blog/2026-10-21-flin…
Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine.
• Best-in-class fast local coding
• Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark
• Built from scratch in under 4 months
Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
We collaborated with @Recursive_SI to make Flint fast from day one. With custom kernels and aggressive fusion, we cut kernel launches from 22 to just 7 per layer.

The architecture, optimizations, and everything you need to get started:
vllm.ai/blog/2026-10-21-flin…

Quantization is easy. Fast quantization kernels for every format × every GPU × every workload are not.
Today we're open-sourcing Humming with Ant Group: one kernel library for all of it — up to 5x kernel speedups, +14–43% E2E MoE throughput.
Blog + benchmarks: vllm.ai/blog/2026-10-21-humm…

1M tokens of context. 4B parameters. Apache 2.0. Controllable thinking.
Spark-X2.6-4B is live, and vLLM serves it day 0. Congrats to the @SparkLLM team! 📷

Spark-X2.6-4B is here! Stronger coding, agents & long-context skills through improved post-training. Thinking: none / low / high.
@huggingface @ModelScope2022 @ollama @vllm_project @sgl_project
huggingface.co/XHToken/Spark…


Realtime open video generation keeps getting faster. FastH3-Omni is out with weights + training code, and vLLM-Omni serves it day 0 — including on consumer RTX GPUs. Congrats to the @haoailab team! 📷

As promised, FastVideo open-sources @MiniMax_AI FastH3 Omni, training code included! 🚀
- Real-time gen @ 12x faster on NVIDIA Blackwell
- NVFP4/FP8 for Spark + RTX!
- ComfyUI day-0
Collab with @NVIDIAAI , Nuva Lab @nuvalab and Reactor @reactorworld
Open source must win! ♥️
🚨🚨🚨 vLLM is all you need to reproduce DeepSeek’s performance.
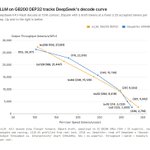
With Wide-EP and EPLB, vLLM can match DeepInfer’s decode performance within 6% and generate $39/gpu/hr in revenue at DeepSeek’s off-peak pricing, at 200 P90 TPS on the AgentX workload.
Specifically:
• Under DeepSeek’s decode configuration (DeepSeek-V4.1-Flash, 131K context, nextn=3), vLLM on GB200 achieves throughput within 6% of DeepInfer’s published results across batch sizes 8–256.
• On AgentX, vLLM pushes the Pareto frontier further on GB300, reaching up to 1M tokens/s/GPU and generating $38.96/gpu/hr in revenue at 196 P90 TPS, based on DeepSeek’s off-peak API pricing.
• Also, vLLM extended low-latency kernel support for DeepSeek-V4.1-Flash, achieving up to 826 TPS per user on AgentX.


Thanks @deepseek_ai for releasing DeepInfer. Together with the community, we'll keep pushing the frontier of performance and cost. You can find detailed vLLM numbers and recipes for reproduction: inferencex.semianalysis.com/…
vLLM retweeted
Grateful to @deepseek_ai for releasing DeepInfer, initially built primarily on @vllm_project, under Apache 2.0 and crediting the open-source community!
We've worked hard on DeepSeek V4.1 Flash inference efficiency and will keep improving with ideas from DeepInfer! Stay tuned 🙌


🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/DeepI…
1/4

Grateful to @deepseek_ai for releasing DeepInfer, initially built primarily on @vllm_project, under Apache 2.0 and crediting the open-source community!
We've worked hard on DeepSeek V4.1 Flash inference efficiency and will keep improving with ideas from DeepInfer! Stay tuned 🙌
🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/DeepI…
1/4
⚡️ Solid work from the Physis-AI Infra team. Together with Physis-AI, we’re introducing PhysisServe.
PhysisServe advances autoregressive denoising serving via fine-grained stage pipelining, time-sharing and multi-stream joint scheduling, optimizing both single-stream output latency and multi-stream system efficiency in one inference system.
PhysisServe’s core techniques are coming to vLLM-Omni, and our teams are working closely together to make it happen.
Congrats on a strong debut. Excited for what we’ll build together! 👏

👋 Hello, X. We’re Physis.
AI’s next frontier is the physical world.
We’re building a general-purpose world foundation model—one that can accumulate and reuse experience across scenarios to understand, predict, and act.
🎯 Our goal is general physical intelligence, with applications across embodied AI, industrial simulation, and scientific prediction.
This brings us to a foundational question:
🤔How can we build a foundation for physical intelligence that accumulates and reuses experience across scenarios—and understands, predicts, and influences the real world at the speed and accuracy each task requires?
Over the coming months, we’ll share our thinking, models, and systems as we work toward this goal.
Today, we begin with infrastructure.
✨ Together with vLLM, we’re introducing PhysisServe.
Born at UC Berkeley’s Sky Computing Lab, vLLM now powers inference on an estimated 500,000 GPUs worldwide at any given time. Together, we’re advancing efficient, scalable serving for the next frontier: physical AI.
Three core designs make this possible:
• Stage-wise pipelining across denoising steps and Transformer blocks.
• Time-sharing and batching to improve GPU utilization.
• Virtual ranks and joint scheduling to share resources across streams.
📊 To explore how world action models (WAMs) and action-conditioned world models (ACWMs) can sustain higher output rates as they scale, we benchmark PhysisServe on five backbones, including MiniMax H3 33B.
On 200 GPUs, this 33B backbone delivers a chunk every 4.083 ms—about 245 chunks/s.* The figure below shows how additional compute enables higher sustained output rates across model sizes.
*DiT denoising only; excludes VAE decoding. Output interval is not end-to-end response latency.
👉 Read our first blog post on infra: physis-ai.com/blog/physisser…
👉 Explore the code:
github.com/Physis-AI/PhysisS…

The vLLM community is coming to #PyTorchCon, Oct 20–21 in San Jose! 🎉
Explore talks on attention, KV transfer, prefix caching, the vLLM roadmap & more.
📅 Build your schedule:
events.linuxfoundation.org/p…
We can't wait to see you there! 🙌

The vLLM ecosystem keeps growing 📷
d3-turbo: SOTA multimodal decision model for intelligent routing — #1 on the Jev Decision Index, 15x faster than d3 flash with StateOnce.
Great work @XunzhuoLiu and the vllm-sr team 📷

Introducing d3-turbo: our newest state-of-the-art multimodal foundation decision model⚡
#1 on both Jev Decision Index boards. It points(box), follows and sees images in your questions. StateOnce brings 15x faster than d3 flash
🤗 huggingface.co/vllm-sr/d3-tu…
#vLLM #Jev #Decision