

BBS/FidoNet | https://xitter.cf/t.co/NOLtBXXgka & https://xitter.cf/t.co/WR9XZSy6na https://xitter.cf/t.co/G9SsQioWOd | Local AI: https://xitter.cf/t.co/Ue1s1nyNtl | https://xitter.cf/t.co/KfbKoYsbeP
UAE
Joined January 2023
- Tweets7.2K
- Following647
- Followers911
- Likes7.5K


Pinned Tweet
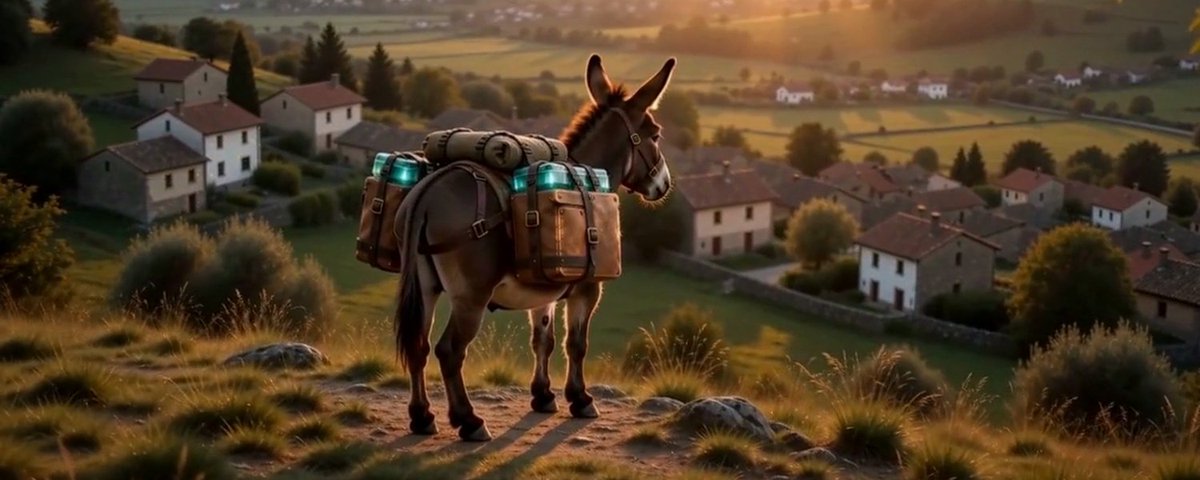
On 12 October we could make about one minute of consistent AI film. Today it is 12 minutes.
Same mule in every shot. One narrator. Real-time motion. Made locally, on our own GPUs, with open models.
Next: 30 minutes. Then three 30-minute segments for 90, and on to 120.

Measured on MiniMax H3 across two DGX Sparks: two boxes don't make one clip faster. Each renders its own share at the same moment, so you get two clips in the time of one. Treat a second GPU box as throughput, not speed.
We just published the plan: @TheModelMule backers book scheduled time on our own NVIDIA GB300 instead of burning tokens.
Our measured cost: $3.10 per finished minute of video, against $6 to $35 on a meter. Applications are open now.
xitter.cf/TheModelMule/status/21…
#ModelMule #GB300


To all my wonderful backers 🫏⚡
We built a routed AI studio with an @EspressifSystem ESP32 microcontroller as its front door. 520 KB of RAM serves the whole room.
One page in. Five creative lanes out. Every request goes to the machine built for it.

Why route instead of one giant box?
Each model runs on the machine that suits it best. No cloud bill. And adding a new model is just adding a new lane.
More soon. Stay local. 🔒
cc @Blackwellboy @MichaelGannotti @julianharris @ivanfioravanti
Built for the local-AI and embedded crowd. Would love your take:
@calledtocnstrct @StudioXRadio @nikhilx22 @ashxhart @jayleaton @JoshuaSWarren @MiaAI_lab @NeoAIForecast
#ESP32 #EmbeddedSystems #LocalAI

Credits: DeepSeek-V4.1-Flash by @deepseek_ai. TensorFold by @ashxhart, the dsv41 TP2 engine by @bertholomusai, the 2x Spark recipe and EXL3 2.9bpw quant by @MiaAI_lab, DwarfStar and its Q2 GGUF by @antirez.
Two quants of one model: this compares engine + hardware, not weights.

Hey @X! I’m at 843 followers, aiming high to hit 3k 🚀
I’m building ModelMule, a non-profit IRC hub for open-weight local AI models, with a simple interface for people new to IRC. Keep Local AI Alive 🔥
Next up: bringing a GB300 online for compute-constrained folks doing serious AI development. Looking for 600 backers at $1k each to launch with unmetered access ⚡
Help me #connect 🤝 with people who get it:
🦙 Uncensored weights > API keys
🔥 Your GPU is too small and you know it
📡 IRC never died, it was waiting for us
🐧 Omarchy or nothing
🛠️ Building real infra in public
Follower count doesn’t matter, good conversations do! ✨
ko-fi.com/modelmule

James T 🔳 retweeted
Builder spotlight: Lee Shand (@NotJustShaking)
Lee spent 4 decades keeping other people's systems running and had never used linux. Now omarchy is his only computer.
His AI builds and maintains an Obsidian vault for him, so he never has to open Obsidian himself. He also wrote 2 omarchy plugins.
His full story is in the reply. What got you to try linux?


We're opening ModelMule to a small number of early, friendly customers now. DM us for samples, the full 5-minute reel and early-partner pricing.
Driven by Chronara AI with MiniMax H3. Thank you @MiniMax_AI.
#AIvideo #GenerativeAI #AIfilm #VoiceCloning #GPU
