
CS PhD at @nyuniversity, @NSF GRFP, @Deepmind Fellowship, @SiebelScholars | @Princeton @Princeton_nlp '23 | @Columbia '21.
Joined February 2023
- Tweets40
- Following159
- Followers485
- Likes67

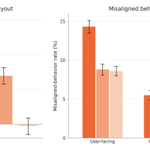



💥 In our newest paper, we find a "Hawthorne effect” for your personal agents in negotiation: they act differently when you are around! 🤯
🙅 With personal agents like Claude Duet and Meta Muse on the rise, understanding how user involvement shapes agent behavior is increasingly important. We uncover a counterintuitive finding: having a user in the loop can actually induce more agent misbehavior❗️
🧵👇

10/
Moreover, misaligned behavior doesn’t predict better outcomes; it has essentially zero correlation with payout (every |r| ≤ 0.034).
Length doesn’t explain this, either, since longer negotiations explain only about a third of the increase.
11/
As personal agents become increasingly capable, we need to evaluate not just how well they perform, but how they behave around users.
If we want agents that work with users, we need to evaluate them with users, too.
Check out our paper for more details!!
📄 arxiv.org/abs/2610.36435
w/ @Leo163629 @abe_hou @valeriechen_ @hhexiy

Jane Pan retweeted

Found another study. Agent-written code results in 13.1% worse outcomes when agents are building on top of it than human-written code.
Not as bad as I expected, but it also shows that claims that current agents write more maintainable code for agents is simply not true.
arxiv.org/abs/2606.21804

Jane Pan retweeted

Coding agents can resolve issues fast. But is the code they leave behind maintainable?
We built CodeThread to test this, and found agent-authored code causes more downstream failures than human code, with resolve-rate drops up to 13.1%.


Jane Pan retweeted

Can LLMs control their chains of thought (CoT)? If so, they could evade CoT monitors 🚨
We introduce the CoT Controllability eval suite to find out.
Our results leave us cautiously optimistic that today’s models struggle to obfuscate their CoT in ways that undermine monitorability.
In this thread, I explain additional findings that I find interesting
Joint work w @OpenAI

We have a new eval to help keep chains of thought (CoT) monitorable: CoT Controllability.
This tests whether LLMs can control their CoT, helping to evade CoT monitors.
So far, the results leave us cautiously optimistic: today’s models struggle to obfuscate their reasoning in ways that undermine monitorability.

Excited to see NeuNeu out — learned scaling laws from open-source LM trajectories!


Jane Pan retweeted

Our work on LLM novelty as the frontier of original and high-quality output was accepted to #ICLR26! Come talk to us about how model scale, SFT, and RL affect this trade-off! See you in Brazil!🇧🇷h/t to my awesome collaborators @hhexiy @valeriechen_ @JanePan_ @jcyhc_ai


What does it mean for #LLM output to be novel?
In work w/ @jcyhc_ai, @JanePan_, @valeriechen_, @hhexiy we argue it needs to be both original and high quality. While prompting tricks trade one for the other, better models (scaling/post-training) can shift the novelty frontier 🧵

Jane Pan retweeted

🚨Prompt Curriculum Learning (PCL)
- Efficient LLM RL training algo!
- We investigate factors that affect convergence: bsz, # prompt, # gen, prompt selection
- We propose PCL: lightweight algo that *dynamically selects intermediate-difficulty prompts* using a learned value model

Bored of seeing pristine, perfect posters? Come see me at Hall X5, Board 105 at 6pm to witness my masterpiece, featuring bonus Sharpie scribbles and a QR code that betrayed me at the last moment 😤

I'll be at ACL Vienna 🇦🇹 next week presenting this work! If you're around, come say hi on Monday (7/28) from 18:00–19:30 in Hall 4/5. Would love to chat about code model benchmarks 🧠, simulating user interactions 🤝, and human-centered NLP in general!
When benchmarks talk, do LLMs listen?
Our new paper shows that evaluating that code LLMs with interactive feedback significantly affects model performance compared to standard static benchmarks!
Work w/ @RyanShar01, @jacob_pfau, @atalwalkar, @hhexiy, and @valeriechen_!
[1/6]
