

Pittsburgh, PA
Joined June 2024
- Tweets255
- Following399
- Followers606
- Likes20.6K



Pinned Tweet
Computer-use evals like OSWorld still don’t really test personal assistant use cases: logged-in accounts, user data, personalized workflows, or realistic desktop/web environments.
so we made MyPCBench: A Benchmark for Personally Intelligent Computer-Use Agents, with 184 tasks across 17 popular website clones, seeded with realistic user data and centered on Michael Scott’s hypothetical desktop.
It’s easy to adopt if you already use OSWorld-style runners - I view it as an personalization-focused, more realistic upgrade for CUA evals.
Website: mypcbench.com/
Paper: arxiv.org/abs/2606.16748
Code: github.com/ljang0/MyPCBench

Do you think Instinct fw boba? Could be a good Musecase.

Introducing Boba - the social intelligence that understands your goals and your community. Text Boba today or message it online at boba.app
Lawrence Jang retweeted

I'm currently on the job market for industry roles!!
I'm Yiqing Xie, a PhD student at Carnegie Mellon University working with Carolyn Rosé and Daniel Fried @dan_fried.
My work mainly focuses on agentic training, coding agents, factuality and trustworthiness, and general training data construction.
If your team is hiring (or you know someone who is), feel free to DM me and I'm super happy to chat!!
My website: yiqingxyq.github.io/;
and CV: yiqingxyq.github.io/assets/p…

Lawrence Jang retweeted

1/ RL for improving task success has made LLMs remarkably capable. But what happens when the model fails? Turns out, training for graceful failure can be surprisingly tricky!
Very excited to share our new paper: Training Language Models to Fail Gracefully
🧵


META’S HEAD OF AI SLAMS AI BENCHMARKS
"it’s some PhD student who made these benchmarks"
"you’re kind of outsourcing all of your product thinking to this viral benchmark"
"so clearly that’s wrong"
I think there is something to this. the whole industry developed so rapidly that there was hardly any time to establish proper benchmarking. companies used what was available, competitors then had to catch up on the same benchmarks, and some of them eventually became industry standards
apparently there is quite a lot of randomness and chance in how we are measuring AI progress today
Congrats to my officemate @NaveenJRaman for his 87th academic achievement 😄
cmu.edu/dietrich/news/news-s…


Looks like Pranjal still has energy to present after getting destroyed in FIFA yesterday. Check it out!

I will be presenting Gym-Anything oral at #COLM2026 workshop on lifelong learning agents.
🗓 12pm at Imperial Ballroom 6
If you are interested in computer use agents or how to make rl environments, do check it out!
Lawrence Jang retweeted

Come see @JangLawrenceK and @kohjingyu present the Odysseys benchmark for long horizon CUAs - poster 46, Imperial Ballroom! #COLM2026 w/ @rsalakhu
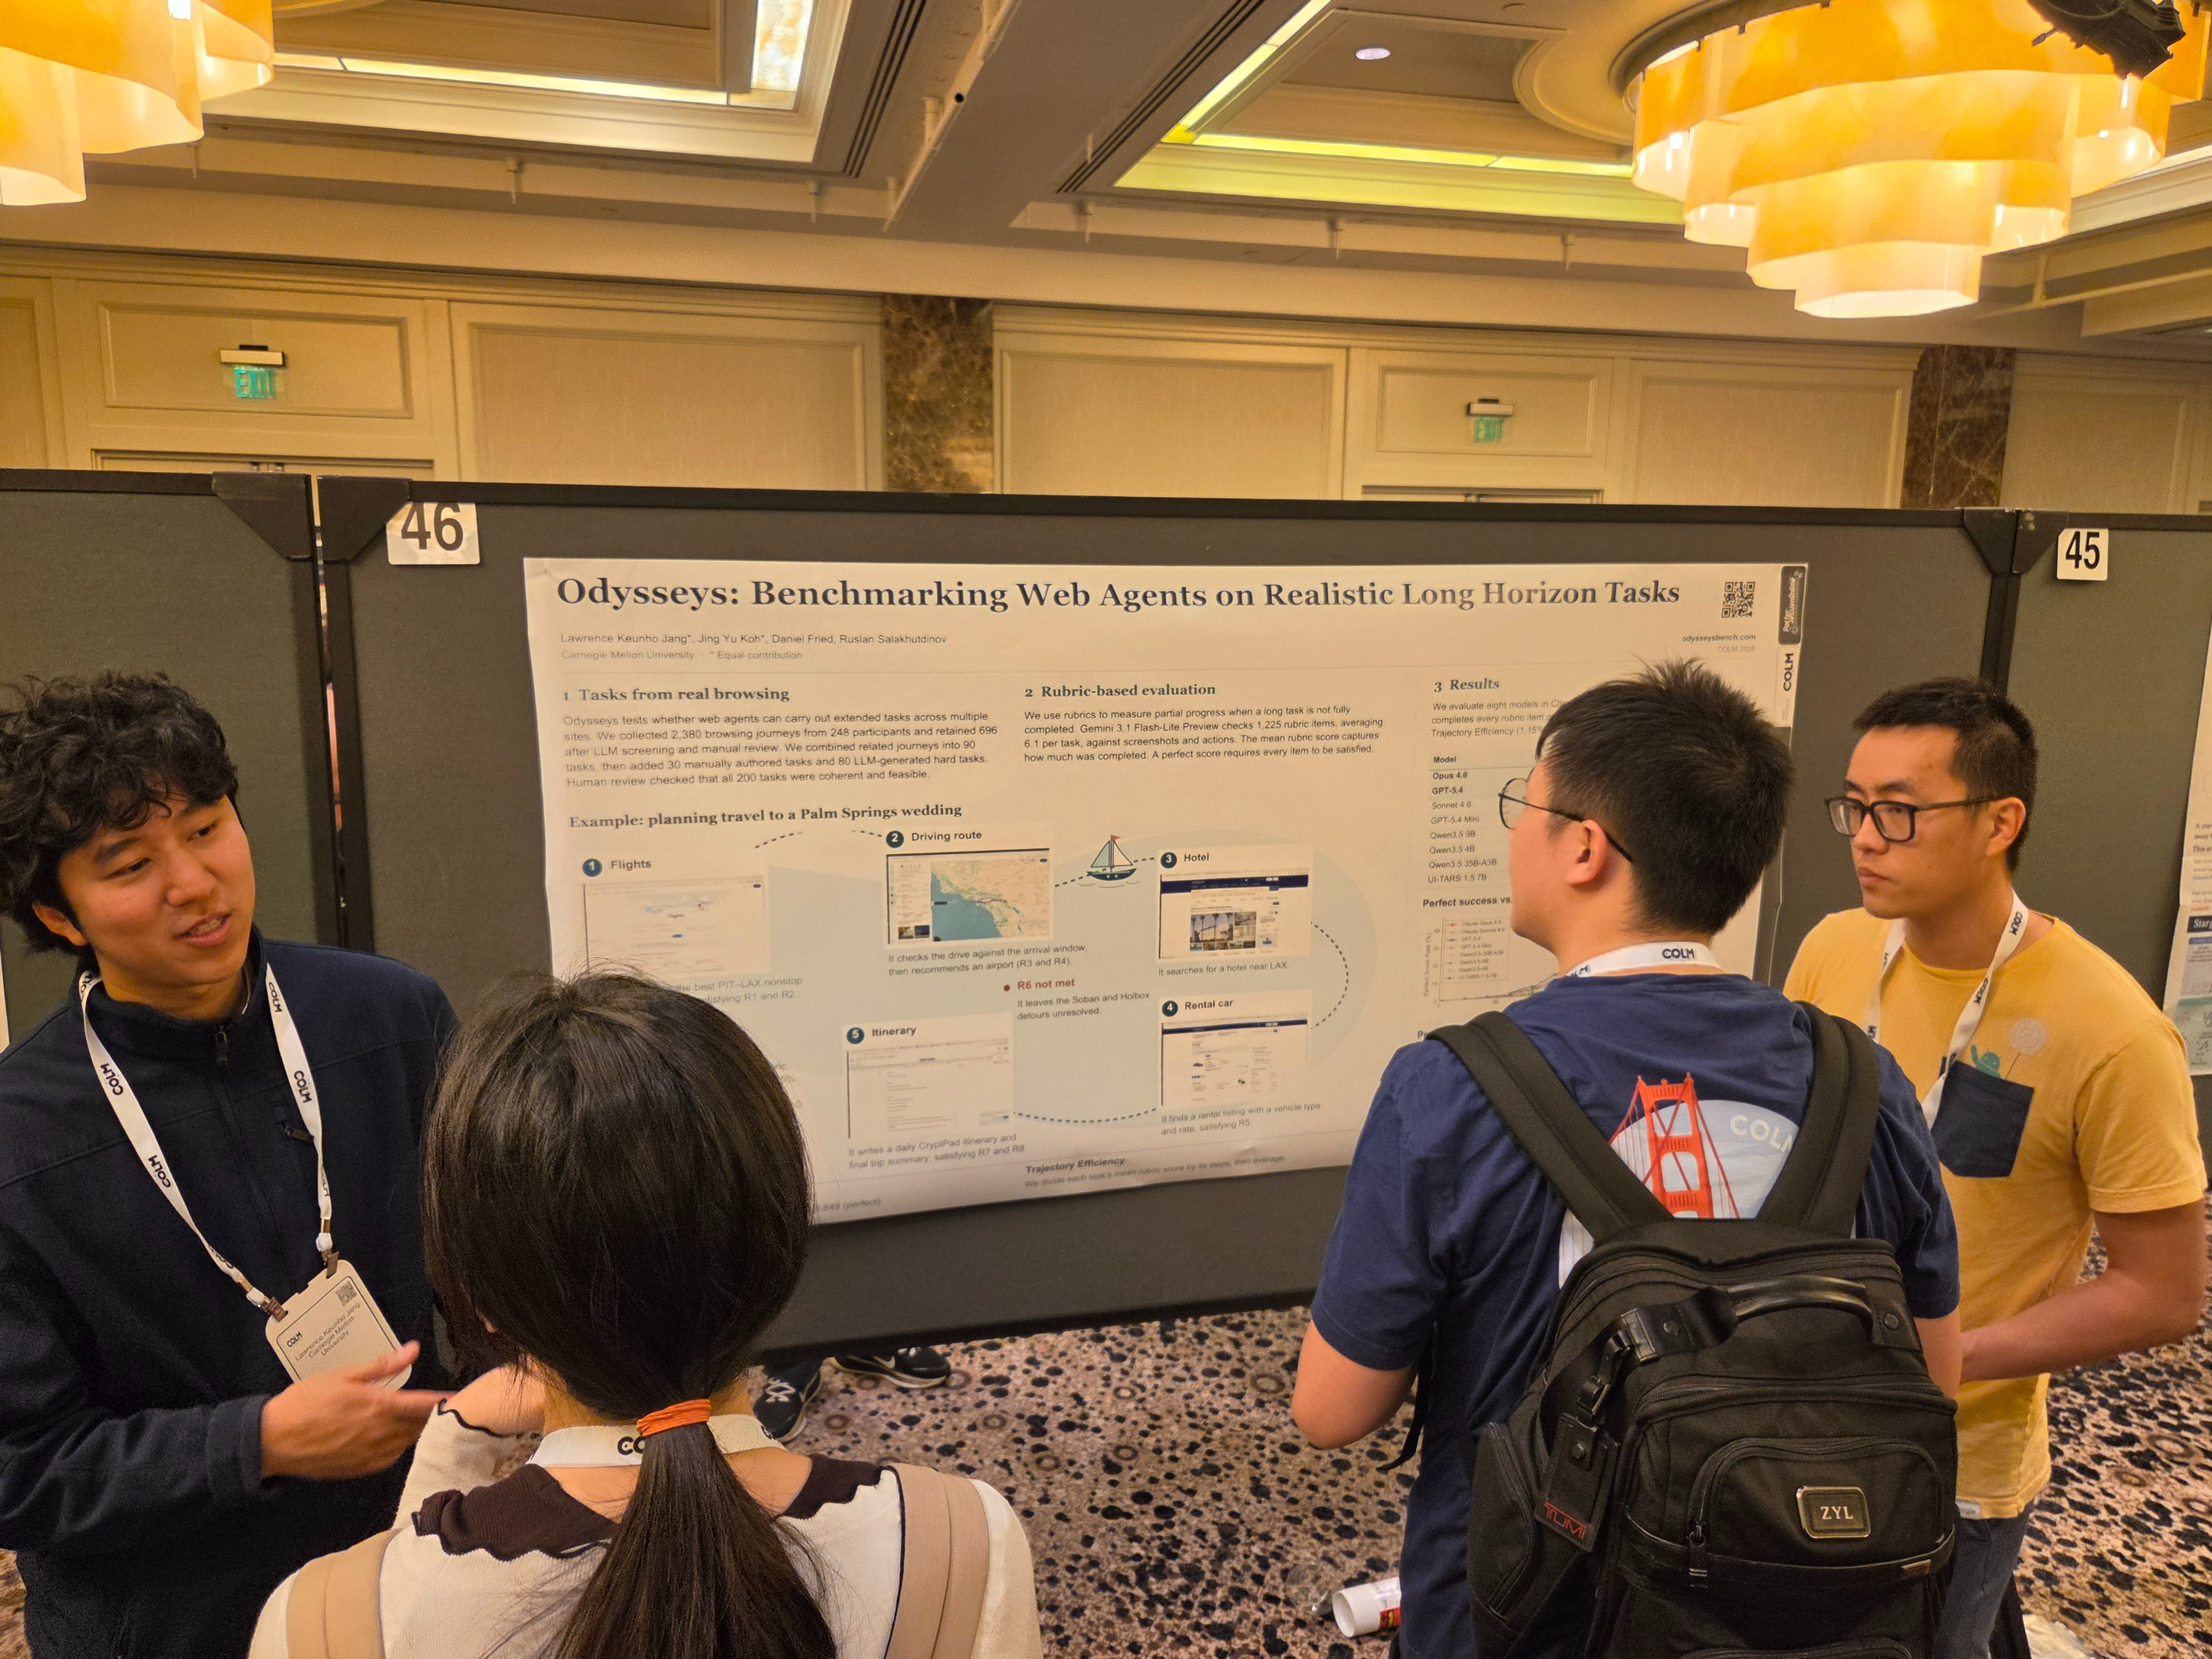
JY (@kohjingyu) will be presenting Odysseys today with me at 4:40 at Imperial Ballroom #46.


Me and @kohjingyu will be presenting iOSWorld at #COLM2026 tomorrow (Franciscan B, Poster #81) at 11:00 AM
JY has promised a free hug to anyone who can guess his date of birth, see you there😁

Check out this work with Yadong at Microsoft! How well can computer-use agents do with just terminal/bash 🙂

What happens when you give a computer-use agent just a terminal and let it build its own tools, organically?
Meet CUAWright, with **only** one tool: run_command.
📄 Paper: arxiv.org/abs/2610.04116
🌐 Project: microsoft.github.io/CUAWrigh…
💻 Code: github.com/microsoft/CUAWrig…
Video credit to @JangLawrenceK!
Lawrence Jang retweeted

What happens when you give a computer-use agent just a terminal and let it build its own tools, organically?
Meet CUAWright, with **only** one tool: run_command.
📄 Paper: arxiv.org/abs/2610.04116
🌐 Project: microsoft.github.io/CUAWrigh…
💻 Code: github.com/microsoft/CUAWrig…
Video credit to @JangLawrenceK!
RT @PranjalAggarw16: I’ll be at #COLM2026 this week, presenting Gym-Anything oral at the Lifelong Agents Workshop at
🗓️ 12 pm on 9th Oct…
Lawrence Jang retweeted

I'll be at #COLM2026 🦙 from Tues-Fri, after almost 2 years of not going to conferences!
I would love to catch up with new and old friends, at the conference or elsewhere in SF! These days I'm mostly interested in CUAs for very complex tasks (including applications in science), new model architectures that support multi-agent coordination, and a secret third thing.
I'll also be presenting 2 papers in the main conference and 1 at the workshops, details in 🧵:
I’ll be at #COLM2026 this week presenting Odysseys and iOSWorld. DMs are open, happy to meet up!
I’m also hosting a great event sponsored by many folks, please stop by: luma.com/zljv7rba

Lawrence Jang retweeted

I'll be presenting Recursive Agent Optimization (RAO) at COLM this Tuesday (Oct 6) at Imperial Ballroom #15 4:30pm!
Please come say hi or reach out if you want to chat!
I've been thinking about training for better agent inference-time scaling, multi-agent coordination and exploration.

Sub-agents are a promising inference-time scaling primitive:
• Expand an agent's working memory
• Divide-and-conquer hard problems
• Solve problems faster with parallel execution
But how do we train a model to best take advantage of sub-agents and make sure we get these benefits?
Very excited to release RAO: Recursive Agent Optimization.
RAO is an end-to-end reinforcement learning approach for training LLM agents to spawn, delegate to, and coordinate with recursive copies of themselves (that can themselves spawn other agents) - turning recursive inference into a learned capability.
1/10