


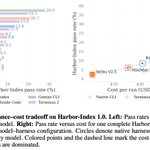




For more details, full paper, and contribution list, see xitter.cf/linshi592021/status/20…

Join us on Discord for future work and discussions: discord.gg/QVvyhRw5UQ
Related links:
- Harbor Framework: harborframework.com/
- GitHub: github.com/harbor-framework/… and github.com/harbor-framework/…
- Harbor Adapters: harborframework.com/docs/dat…
- Harbor Hub: hub.harborframework.com/
Harbor Adapters and Harbor-Index
arxiv.org/pdf/2609.04298
1+year work, 120+contributors, 300+PRs, 10+ funding partners.

Huge thanks to our funding partners (@OpenAI @AnthropicAI @GoogleDeepMind @Alibaba_Qwen @deepseek_ai @Kimi_Moonshot @Zai_org @MiniMax_AI @XiaomiMiMo @LaudeInstitute
@2077AI @UniPat_AI ), sandbox providers (
@daytonaio @modal ), and our 120+ contributors and advisors from @terminalbench and @harborframework who brought the work to life!

Join us on Discord for future work and discussions: discord.gg/QVvyhRw5UQ
Related links:
- Harbor Framework: harborframework.com/
- GitHub: github.com/harbor-framework/… and github.com/harbor-framework/…
- Harbor Adapters: harborframework.com/docs/dat…
- Harbor Hub: hub.harborframework.com/


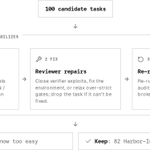
Harbor-Index is live. Browse all 82 tasks and 1,476 rollouts at harbor-index.org
Huge thanks to our funding partners (@OpenAI @AnthropicAI @GoogleDeepMind @Alibaba_Qwen @deepseek_ai @Kimi_Moonshot, @Zai_org, @MiniMax_AI, @XiaomiMiMo, @LaudeInstitute, @2077AI, @UniPat_AI), sandbox providers (@daytonaio, @modal), and our 120 contributors and advisors from @terminalbench and @harborframework who brought Harbor-Index to life!
And finally, our deepest thanks to the open benchmark community that made Harbor-Index possible: @alexgshaw, @ryan_marten, @ekellbuch, @longphan3110, @slimshetty_, @ori_press, @fchollet, @ludomitch, @froger_romain, @ChowdhuryNeil, Qixing Zhou, @jonmlaurent, Xiang Deng, @mialon_gregoire, @MinyangTian1, @Mike_A_Merrill, Zhun Wang, Bofei Gao, @xdotli, @fangyu_lei, @samuelp1002, @terryyuezhuo, @Shanda_Li_2000, @yeeelow233, @idavidrein, Rui Yang, @christinexye, @AndyLin2001, @jyangballin, @nielstron, @BenShi34, Ryan Wong, and so many more benchmark authors.
Join us to build the next iteration of Harbor-Index on discord.com/invite/2Pe5uWGcV…!
CAIS AgenticSE Workshop Keynote Talk: Harbor Adapters & Harbor Index
30min video here:
youtu.be/tvAAKX2XVus?si=84L2…
Happy to be invited as a keynote speaker and present our recent study on Harbor Adapters and agentic evaluation!


Lin Shi retweeted

Terminal-Bench is a leading benchmark for agents. Unfortunately it’s hard: most small coding agents get very low scores on TB2, so training/system ablations look flat - you can't tell what's working.
Announcing OpenThoughts-TBLite - 100 curated TB2-style tasks, difficulty-calibrated so even 8B models can make progress. It's designed to give researchers measurable signal during development, providing faster feedback for experimental iteration while closely tracking true TB2 performance🧵

Lin Shi retweeted
A new Harbor benchmark comprised of tasks from @SnorkelAI @bespokelabsai and Terminal-Bench 2.0 rejects due to difficulty.
Useful for hillclimbing TB tasks with small models.


Terminal-Bench is a leading benchmark for agents. Unfortunately it’s hard: most small coding agents get very low scores on TB2, so training/system ablations look flat - you can't tell what's working.
Announcing OpenThoughts-TBLite - 100 curated TB2-style tasks, difficulty-calibrated so even 8B models can make progress. It's designed to give researchers measurable signal during development, providing faster feedback for experimental iteration while closely tracking true TB2 performance🧵
Lin Shi retweeted
Come help us build Terminal-Bench 3.0! It will be an extremely high quality, difficult benchmark.

if you want to help us create harder tasks, come join the terminal-bench-3.0 effort
discord.gg/6xWPKhGDbA