

Interested in AI for social good. Grad Student @Mila_Quebec, Former RE @MITIBMLab | MS @unccs | RA @iitdelhi | BTech @iitmadras
Montréal, Québec
Joined May 2017
- Tweets36
- Following468
- Followers169
- Likes1.5K





Muqeeth retweeted

Currently, the most critical technical alignment issue is our algorithmic inability to detect which unwanted capabilities or drives are being added to the agent by the RL gradient updates and filter them out before they have a chance to significantly misalign the agent.
This requires assessing how an update has changed an agent's behavior.
The analysis of the difference between an updated agent and its previous version can be behavioral. But the completeness of a behavioral analysis can require an unreasonable amount of compute. For instance, important undesired behaviors of the agent may only occur in certain contexts (say, in a context where the agent does not believe it is being observed), which must be found via trial and error.
To get a comprehensive analysis of an agent update in viable time, a mechanistic grounding is probably required. However, it seems like a lot of researchers arriving at similar conclusions start working on methods with a bias for some of the LLM's internals to be directly legible by the researcher themselves. If your training pipeline puts safety pressure against RLVR, then RLVR will propose gradient updates to obfuscate the internal representations and computations of your agent. Your filtering method needs to be robust against such proposals. As such, the training module tasked to steer the agent's mechanistic evolution should not be limited by a legibility criterion to you, the researcher.
There is some evidence that, without being explicitly trained to do so, small transformers can mimic gradient descent during in-context learning: arxiv.org/pdf/2212.07677. This evidence suggests considering the self-directed computations that we can implicitly train LLMs to perform during their forward passes. For technical alignment, I think we should use this self-directed computation potential to add robust introspective capabilities to our LLMs. I strongly recommend reading arxiv.org/pdf/2604.16812, which introduces "introspective adapters", a first step in this direction.
Note that in this simple approach, the technical challenge of the mechanistic analysis was completely delegated to the model and gradient descent.
Muqeeth retweeted

New paper!
Self-Distillation with sampled demonstrations leads to reduced output diversity.
All because the teacher can more easily align some solution–demonstration pairs than others.
with @mpezeshki91* @AaronCourville* at @AIatMeta @Mila_Quebec
Muqeeth retweeted

Hi! If you are interested in game-theoretic analysis of the AI race and open vs. closed sourcing, check out our new paper:
" Why Open Source? A Game-Theoretic Analysis of the AI Race "
arxiv.org/pdf/2604.16227
There are some cute complexity results there 🙂
Muqeeth retweeted

The Cooperative AI Summer School 2026 'Expression of interest' applications are now open! If you're an early-career professional studying or working in cooperative AI, apply to join us in Canada this August for an exciting intensive programme.
Muqeeth retweeted

AI is changing economics, and --- as we just saw in Dwarkesh's interview with Dario --- AI researchers need to start thinking about economics too!
The Center for Applied AI at UChicago will be hosting an AI & Economics Summer Institute to explore exactly this.
We will bring together leading researchers with advanced graduate students in economics/AI/ML/NLP for an in-person program between Aug 6 - 11.

Muqeeth retweeted

Have you been using LLMs to play games, negotiate salaries, or strategize in other ways? Whether it worked or not, we want to see your demo at our “Strategic Engineering” workshop (sites.google.com/view/se-aam…) at #AAMAS2026 in Cyprus! Starter library @ github.com/google-deepmind/s…!
Muqeeth retweeted

📢 I am excited to announce that our paper, "TokSuite: Measuring the Impact of Tokenizer Choice on Language Model Behavior," is now live both on Hugging Face and arXiv.
🖇️ arXiv Page: arxiv.org/abs/2512.20757
🤗 HF Org: huggingface.co/toksuite
#LLM #NLP #Tokenization

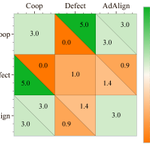
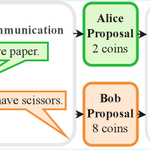
New preprint! Learning Robust Social Strategies with Large Language Models. We apply multi-agent RL finetuning to train LLMs that achieve cooperative and non-exploitable behavior in social dilemmas for the first time.
📄 arxiv.org/abs/2511.19405
🧵 ⬇️
(1/8)

AdAlign agents are also robust when facing RL agents trained specifically to exploit them, while GPT-5 nano is exploitable in the same setup. The RL agent ends up cooperating with AdAlign’s tit for tat style policy, since that is its best response. (7/8)


You can run multi-agent RL training for LLMs right away with our public code: github.com/dereckpiche/AdAli…. This work was done with my awesome group members @Dereck_Piche*, @muqeeth10*, @MAghajohari, @JuanDuquevan, @mnoukhov, and @AaronCourville.(8/8)
Muqeeth retweeted

Zero rewards after tons of RL training? 😞 Before using dense rewards or incentivizing exploration, try changing the data. Adding easier instances of the task can unlock RL training. 🔓📈To know more checkout our blog post here: spiffy-airbus-472.notion.sit…. Keep reading 🧵(1/n)

Muqeeth retweeted

We just released our survey on "Model MoErging", But what is MoErging?🤔Read on!
Imagine a world where fine-tuned models, each specialized in a specific domain, can collaborate and "compose/remix" their skills using some routing mechanism to tackle new tasks and queries!
🧵👇
co first-author @colinraffel
📰: arxiv.org/abs/2408.07057

ALT A survey on Model MoErging!
Introducing Soft Merging of Experts with Adaptive Routing (SMEAR) for gradient-based training of mixture-of-experts models. SMEAR matches or outperforms prior routing methods without increasing costs or relying on task metadata.
📄 arxiv.org/abs/2306.03745
🧵 ⬇️
(1/7)

Experts learned with SMEAR still exhibit intuitive specialization - for example, by sharing experts across similar tasks or dedicating multiple experts to more complex tasks. (6/7)

You can try out SMEAR with our public code github.com/r-three/smear and read more in our preprint arxiv.org/abs/2306.03745. This work was done in collaboration with @liu_haokun and @colinraffel (7/7)