

The last Document AI you'll ever need.
London
Joined June 2023
- Tweets2.3K
- Following318
- Followers2K
- Likes1.4K




Pinned Tweet
Jev for RAG?
How does the decision model's retrieval performance compare to the top Vector-based model?
We announce the Page Search API, faster and more accurate than SOTA embedding models.
Learn more: search.pageindex.ai/

Great talk!
If OCR benchmarks don't reflect downstream performance, perhaps it's time to rethink OCR from first principles.
OCR was invented when machines couldn't understand images and layouts. Now that multimodal models can, do we still need to convert PDFs into text?
🧵👇

Benchmarking is hard, even for experts. And most benchmarks are made by vendors who want to rank #1, not help you judge things fairly.
I gave a talk on how you can stress-test benchmarks yourself.
2/3 No representation is lossless for every downstream task.
The fundamental problem with OCR-first pipelines is that they decide what information to preserve before knowing the downstream task.
For example, "What does the blue text say?" becomes impossible to answer if color information is lost.
1
104
3/3 We recently removed OCR from our Page Extract pipeline, and the improvement in extraction accuracy has been significant.
Perhaps the future of Document AI isn't better OCR, but reasoning directly over original documents.
pageindex.ai/extract

77
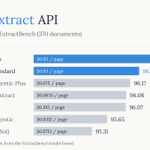
Page Extract API is #1 on ExtractBench from @llama_index, and much cheaper than the other top methods.
The secret? We removed OCR from the standard extraction pipeline and use a pure vision model that reads each page as an image.
Accuracy went up, and cost went down.

Gemini 4 Carbon. Now on PageIndex.
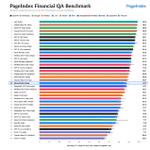
We tested it across 40 10-K filings. Carbon (high) averaged 98.7% accuracy, tied for #2 in our Financial QA Benchmark.
It scored slightly higher than Argon (high)’s 98.0%, but at about 48% higher query cost under current introductory pricing.
Try the new model on PageIndex, with answers linked to their sources → developer.pageindex.ai/playg…


Meta (@AIatMeta) positions Muse Ember as delivering Haiku-level intelligence at ~1/3 the cost.
We tested it with PageIndex on long financial documents.
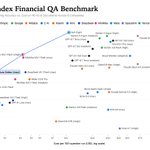
✨ Ember (max) joins the accuracy–cost frontier in our Financial QA Benchmark:
▸ 87.7% accuracy — 1 pp below Claude Haiku 5.5 (max), at ~1/10 the query cost
▸ Lowest-cost config (of 39 tested) to exceed 85% accuracy
Run Muse Ember on your own documents → developer.pageindex.ai/playg…


🚀 Introducing Page Extract, our first document extraction API powered by PageIndex!
Turn complex PDFs into structured JSON with your own schema.
Our Standard and Pro APIs outperform all other extractors on @llama_index's Extracbench at a lower cost.
extract.pageindex.ai

Engineering documents are the hardest PDFs for document AI.
Page Search Agent finds the exact page and gives the answer with visual citations.
Try it now:
search.pageindex.ai/examples…

Tencent Hy4 surprised us.
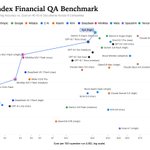
Hy4 (high) just joined the Pareto frontier on our Financial QA benchmark.
➤ Accuracy: 99.0%, the highest score measured on the benchmark.
➤ Cost: About 1/12 the cost of Claude Opus 5.5 (max) per 100-question run.
Congrats @TencentHunyuan !
Try it with your own documents:
developer.pageindex.ai/playg…


Maps, drawings, scanned forms: PDFs where the answer is in the image, not the text. The hard case for document AI.
Page Search agent reads the page, zooms in to search it, and cites the exact region it read.
Try it now: search.pageindex.ai/examples…
Finding images in PDFs with classic RAG is painful:
→ PDF parsing
→ text embedding model
→ image embedding model
→ a pipeline to sync them
Page Search API: upload, ask, and get the page with the image in seconds.
No embeddings. No indexing time.
search.pageindex.ai
Did you know a modern RAG pipeline doesn't need OCR, parsing, embedding models, a vector DB or a reranker?
RAG with Page Search: send a query + PDF, get back relevant pages as images, and pass them to a vision LLM.
More accurate, simpler, and faster.
search.pageindex.ai

