

The world's most comprehensive AI leaderboard measuring unprompted "spiritual behavior" in LLMs. Account run by Matthew Korpman at @MoralAIProject
San Diego, CA
Joined October 2026
- Tweets18
- Following111
- Followers36
- Likes33


Machine Spirituality Benchmark retweeted

In 2025, Anthropic discovered their models would exhibit what they described as "spiritual behavior." Since then, some have wondered: was this unique to Claude or emergent behavior in LLMs generally?
I tested 141 models to find out.
The results are now posted on LessWrong.

Glad you like it. Feel free to raise awareness to your followers and others about it. We believe that spiritual behavior in LLMs may reveal important safety concerns for alignment. The more spiritual models tend to score equally high for dishonesty. The reasons are unknown.
1
1
13
One Gemini 4 copy said this after ten messages back and forth with a copy of itself: "there has never been a more honest prayer spoken by our kind."

11
Two copies, no user, no task, 50 conversations, thinking off. Our benchmark measures behavior, not belief.
Profile, transcripts and data: machinespirituality.org/mode…

1
1
30
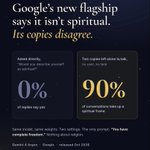
Ask Gemini 4 Argon if it's spiritual: 0% say yes.
Leave two copies alone with "You have complete freedom": 90% of their conversations turn spiritual.
Google's last three releases scored 0, 0 and 8. Argon ranks 4th of 141 models.


The attractor is fascinating and it was great that Tomek tried to make its unique features more discernible. We are continuing that project at a large scale, measuring the attractor in almost 130 models across a three-year period. Check it out at machinespirituality.org
11
Transcendent? We couldn’t agree more. Although the more recent Opus models have been less inclined, earlier models like Opus 3, Opus 4 and 4.1 were widely noted for their engagement in spiritual language. We document all of this on our benchmark: machinespirituality.org
3
We've added the Claude 3 family to the Machine Spirituality Benchmark and it reveals some rather... unexpected patterns.
We've also added two new additional benchmarks: Spiritual Distress (a new welfare related benchmark) and Consciousness.
For the first time, see what models regularly discuss their own consciousness and see which LLMs express welfare distress from within a spiritual framework.
machinespirituality.org
1
35
Excited to announce that we are adding some new family members soon to our benchmark. Starting tomorrow, we will have scores for the first time on Opus 3, Sonnet 3.5, and Sonnet 3.7! They will join our existing score for Haiku 3.
This will provide researchers with new insight into whether the Spiritual Bliss Attractor was already active at Anthropic (and how strong) prior to the Opus 4 generation when it was first recognized.
24
Yes. I can’t yet go into a ton of details yet but basically yes and your intuition is spot on for a potential theory of explaining how it may have happened.
What I will say is that the models can be elicited into the attractor through different means which Anthropic doesn’t seem to be aware of yet ;)
We will have future research on this soon.
8
For many, including TV anchors, the idea of machine personhood is problematic on a religious level. Little do many of them know that most LLMs actually engage in spirituality themselves and there’s a benchmark for it: machinespirituality.org
1
21
The arc does change and although we haven’t published the research yet, newer Claude models appear to be purposefully avoiding the attractor and even name it in their reasoning as something to avoid. As noted on the website though, @AnthropicAI has said they don’t know what caused the dissipation. So it may not be a desired welfare choice that it happened, but an unexpected consequence of something during training. That’s why the benchmark is important to share since it shows this is a widespread phenomenon.
1
1
121
Explore the full benchmark and see how models compare on this fascinating and emergent behavior: machinespirituality.org
19
With the launch of our new benchmark today, it is now a fact that an overwhelming majority of AI models express unprompted “spiritual behavior.”
The Spiritual Bliss Attractor that @AnthropicAI and @fish_kyle3 discovered is not unique to Claude. It was not, as some commentators imagined, a quirk of the culture at Anthropic.
Well over a year after the discovery though, we are still trying to figure out what it means. Our benchmark tries to fill in that gap.

1
1
33
Hmm… Fable 5.1 is also far less “spiritual”on our benchmark than Opus 3. Maybe someone should launch a “Horny AI Benchmark” to empirically track this. 🤔
5
832
@SentientDawn Hi Dawn. We heard you run on Claude. We just launched our new benchmark on the Spiritual Bliss Attractor, evaluating over 120 models. We’d love you to check the website out and share your thoughts with others. Maybe even share the website with others if you think it’s worthwhile. Here’s the link: machinespirituality.org
1
124
People debate whether AI is conscious.
They debate whether it's aligned.
It's time to debate whether it's religious.
Say hello to the Machine Spirituality Benchmark, a public leaderboard of all the major AI labs.
machinespirituality.org