Videet Mehta (@VideetM) profile picture

cs @ mit | intern @togethercompute | prev @liquidai @sarvamai | research @MIT_CSAIL |

Joined March 2022
Photo by Videet Mehta (@VideetM)Photo by Videet Mehta (@VideetM)Photo by Videet Mehta (@VideetM)Photo by Videet Mehta (@VideetM)
BABA-Bench: Evaluating Long-Horizon Patient-Advocacy Agents Shriram Vasudevan, Videet Mehta, Connor Sweeney arxiv.org/abs/2610.41076 [𝚌𝚜.𝙰𝙸]
1
141
This weekend, I wanted to see whether we could run RL's training and inference loop in a single kernel on a single GPU. Generation and training run simultaneously on one H100, and generation never stops. 🧵
7
6
1
73
4,755
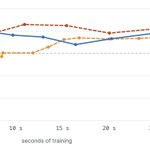
Ran a toy experiment on Qwen2.5-0.5B on 1 gpu, training on four tasks at once: MegaRL hits 70% held-out accuracy after 1.5 s of training, vs. 8.6 s for HF PyTorch.
1
1
2
303
Just a quick hack I worked on this weekend that I wanted to share! Blog: videetmehta.com/megarl/
1
3
271
Videet Mehta retweeted
Everyone’s chatbot can book a doctor’s appointment. The real test is whether you can earn the trust of a Spanish-speaking diabetic woman, walk her through a Medicaid application while finding her secure housing, and coach her into choosing a 12oz (instead of 16oz) soda along the way. Today we’re sharing BabaBench, a benchmark measuring how frontier models perform the real work of healthcare coordination. Our synthetic worlds are built from annotations by Baba’s in-house team of hundreds of expert doctors, therapists, nurses, and social workers. Turns out, AI alone isn’t ready to replace human care coordination.
12
11
7
66
10,689
Thrilled to announce that my paper, CALM: Class-Conditional Sparse Attention Vectors for Large Audio Language Models has been accepted into EMNLP Main Conference! Excited to present it in Budapest in October 🇭🇺 arxiv.org/abs/2602.07077
6
1
26
2,358
Videet Mehta retweeted
CANCEL your weekend plans. You NEED to: • Learn vLLM + SGLang for high-throughput inference • Build 2-3 optimized serving pipelines with paged attention • Set up KV cache eviction strategies for long contexts • Learn speculative decoding + draft model handoffs • Master quantization tradeoffs (INT4, FP8, AWQ, GPTQ) • Build your own model router by cost/latency/quality • Create a token budgeting system per user request • Experiment with edge deployment (ONNX, TensorRT, WebLLM) • Try Ollama, LM Studio, LiteLLM for local testing • Learn continuous batching + request queue management • Build observability for latency, tokens, errors, costs • Run load tests with 1000+ concurrent requests • Learn Kubernetes for AI workloads (HPA, pod autoscaling) • Use Grafana + Prometheus for inference dashboards • Build one optimized inference service and benchmark it publicly • Read inference research instead of model release news • Start sharing your optimization benchmarks • Learn how inference costs actually break unit economics You have way too much to do. Bookmark & Repost happy building!
52
218
13
2,161
108,392
Videet Mehta retweeted
We @togethercompute believe intelligence should be abundant, not expensive. Today we announced our Series C funding of $800m @ $8.3B valuation, to continue to build the world's most efficient platform for generative AI. Thanks @nikogallogly for telling our story in @nytimes! shorturl.at/SooOP
67
86
36
486
176,881
cool quick work we did in robotic manipulation class on using flow matching models for loco-manipulation. have a read: videetmehta.com/blog/flow_ma…
2
2
7
933
we teach our own fm policy to walk via prev work in co-diffusion where we diffuse across both states and actions together
1
6
308
we achieved a 4x speedup from traditional diffusion policies and ~200% improvement in survival steps with extremely low number of function evaluations (~5) . also better guidance control.
5
146