Vineeth Reddy Guda retweeted
As promised, we’re releasing Inkling 2 Small’s weights, thanks to the hard work of our team and safety testing partners
Inkling 2 Small’s weights are now available for download on HuggingFace under an Apache 2.0 license.
Make Inkling your own!
huggingface.co/thinkingmachi…
looking forward to see you at this event
📣📣📣 Big Berlin Hack is back 🚀🚀🚀
And this time, even bigger:
🗓️ 28 & 29 November
👥 350+ builders from all over Europe
💰 Bigger prize pool
Last time we had >1500 applications for Big Berlin Hack, so better be fast 👀
Registration is now open: luma.com/bbh
Thanks to all of our partners, it's gonna be huge‼️
2
47
Vineeth Reddy Guda retweeted
Jensen Huang’s Super Agents slide: turning your data into a moat.
The path he described starts with an open model and post-training for your use case.
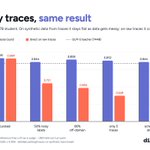
We help companies run that loop, turning production traces into evals, training data and models they can keep improving.
Vineeth Reddy Guda retweeted
The team at @distil_labs post-trained a model on their docs in under 6 hours and built a voice agent with Phonon.
If your voice agent works within one product or one knowledge base, fine-tuned models can perform well and help cut down latency and cost.
We dropped by the @GradiumAI booth at GTC Berlin and let Tim quiz our agent. It answered in their new Phonon voice.
The agent is a small model we post-trained on our docs in under 6 hours.
Build your own: ask your coding agent "get started with distillabs.ai/onboarding.md"
Vineeth Reddy Guda retweeted
We dropped by the @GradiumAI booth at GTC Berlin and let Tim quiz our agent. It answered in their new Phonon voice.
The agent is a small model we post-trained on our docs in under 6 hours.
Build your own: ask your coding agent "get started with distillabs.ai/onboarding.md"
Vineeth Reddy Guda retweeted
Couldn't be prouder to see our @distil_labs logo TWICE in @JensenHuang's keynote at @NVIDIAGTC today, alongside stellar companies in the post-training and wider AI economy 🔥
Vineeth Reddy Guda retweeted
Live from @NVIDIAGTC - @JensenHuang showcasing the post-training ecosystem, and we're part of it 🫰
Vineeth Reddy Guda retweeted
Somebody pinch us! We just made it into @JensenHuang keynote at @NVIDIAGTC Berlin!
Vineeth Reddy Guda retweeted
Knowunity swapped a frontier LLM for its own quiz model, and the quizzes got better at a third of the cost.
On 114 English production requests, quizzes passing all four of Knowunity's review criteria went from 39% to 65%. Cost per 1,000 quizzes: $1.60 to $0.50.
Vineeth Reddy Guda retweeted
Training a small model to call tools means generating example conversations, and they have to get the order of actions right: an agent can only book a flight once the user is logged in.
Our Turnslide paper builds that into the training data.
Vineeth Reddy Guda retweeted
Introducing Clairic, from Cloudflare. A System One extraction modeI, capable of extracting, computing, estimating, and forecasting data from unstructured inputs. cfl.re/4zIgfpH
Vineeth Reddy Guda retweeted
Wabi 2.0 is live!
personal agents are one person, one chat. but the parts of life that matter run on more than one person
Wabi is an agent you use together. you talk to it, it does stuff, builds the apps you need, and anyone can join the thread - your partner, your best friend, the preschool moms groupchat
school changes pickup time → Wabi updates the family calendar, everyone sees it.
a show you’d both love → Wabi finds a night that works, gets the tickets.
the trip everyone keeps talking about → Wabi picks the dates, builds the itinerary, books it
go start a thread with your people 👇
🤖 Made with AI
Vineeth Reddy Guda retweeted
NVIDIA’s Nemotron 3.5 Super VL is out today! As a launch partner, we used it as a teacher to build 4 mini-Jevs. A coding agent ran the platform and our 4B models matched Jev’s level of accuracy.
Want to build yours? Reply for early access. Full details below.
Vineeth Reddy Guda retweeted
Turnslide, our paper on generating training data for small language models, has been accepted to a workshop at @NeurIPSConf 2026.
It plans multi-turn tool-calling conversations around the states an API can be in, then has a larger model write each one in a single call.
Vineeth Reddy Guda retweeted
Let your coding agent iterate and train the best version of your custom model in under 3 hours.
With autoresearch, it reads the wrong answers, works out whether the data, the teacher or the training settings caused them, changes one setting and retrains until it hits the target.
post-training your own models is where every company ends up imo. frontier models are just the starting point. your data is what makes it yours. that's where it stops being copyable
the loop we built at @distil_labs: your agent traces go into a teacher that cleans them up and generates training data. that trains a small model, which serves your traffic with your current model as fallback. the new traffic becomes the next round's traces
same test set every round so you actually see if it got better. lmk if you wanna try it on your stuff
1
124
come and train your own model with just one command..
We're hosting a Builders Night with @langfuse and @runpod in Berlin next Monday, 19 October, to kick off GTC week.
Post-train, test and deploy your own small language model with our engineers on hand. Pizza, drinks and €1,000 for the winning team.
luma.com/ahiyw2gp
2
95


