





Weco AI retweeted

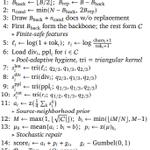
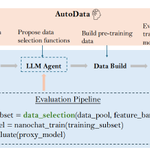
I'm a bit shocked that our RSI system (AIDE²) actually discovered a similar mechanism.
I initially thought it was a weird mechanism that had slipped through due to some lucky evaluation noise. But after reading this more rigorous study, it now makes sense to me.


Fork-and-Flush: help your agents escape Idea Basins!!
I love thinking of AutoResearch as Idea Descent: a metric of interest goes down, as a function of ideas/experiments, where the agents get pulled towards one idea or another. But we've seen very often an agent develop this weird tunnel vision, and honing in just one type of "idea", kinda like GD stuck in a local minimum.
We studied this and seems we can fix it with Fork-and-Flush, a super simple and kinda cute idea. Every so often, fork the agent into T copies in the same workspace but empty the context, let them run for a bit, and continue from the best one.
If you like the GD analogy, it's basically basin hopping en.wikipedia.org/wiki/Basin-….
BTW we found a silly way of also plotting "idea basins": an LLM rewrites every experiment as a spec and answers a few thousand binary queries "is Experiment A closer to B or to C?". Then we embed this NXN matrix into 2D and indeed see in many cases that each run saturates into a small region and keeps polishing it.
We call these idea basins!
At equal compute Fork and Flush beats single runs and best-of-N on 12/13 long-horizon tasks (some 4+ days), and in my own research projects it's been working really well!
BTW we only use it at test time, but it could also be part of training or RL.
Led by @jackcai1206 @christos_ziakas during Jack's internships with us, along with @vkontonis @ShivamGarg91462 @Tea_Pearce Sid Sen and Akshay Krishnamurthy.


Weco AI retweeted
I think the AI/ML researcher's role will be greatly transformed by autoresearch, but it won't disappear. It boils down to three skills:
- Coming up with creative primitives
- Defining a good abstraction for the agent to search within
- Defining a good eval on what good is
With the RSI results we published this week, this becomes even more relevant.
My @aiDotEngineer talk makes the full case, dedicated recording now up: youtu.be/iCj_ATyThvc

Weco AI retweeted

Awesome work by @WecoAI in the pursuit of RSI. Proof the small companies innovating with taste and determination can move fast, and move well!

Weco AI retweeted

Exciting agent harness recursive self-improvement result. Congrats @zhengyaojiang, @yuxiang
and @WecoAI team!
Weco AI retweeted

RSI of harness by harness for harness! Already producing a harness that is great at doing auto research!
Phenomenal work and progress.
Weco AI retweeted
We ran autoresearch on preprocessing for a fraud-detection task. With a loose API the score looked great, and the code was leaking test data into the features in 13 different ways. We tightened the abstraction to a strict API and the reward-hacking rate dropped to zero.
My metaphor @aiDotEngineer talk: doing autoresearch is like training a model. The codebase abstraction is the architecture, it biases everything the search can find. The eval is the loss function and the data.
Human's research & engineer's role is no longer write exact code but get the constraints and feedback signal right.
Link to the talk in reply

Weco AI retweeted

Big fan of @WecoAI's work on automated discovery💡
We worked with AIDE, when extending it for the AI Scientist-v2 🧑🔬 and the OAI parameter golf results for the collaborative Aiden agent look really impressive 🚀
📝: weco.ai/blog/parameter-golf-…
Highly recommend checking out @zhengyaojiang's talk at @aiDotEngineer 👀
👉 youtube.com/live/4sX_He5c4sI…


Weco AI retweeted
This year @WecoAI will be at the @aiDotEngineer World's Fair.
We'll host a hands-on autoresearch workshop on June 29.
And I'll give a talk on July 1.
Looking forward to chatting with old and new friends there!
ai.engineer/worldsfair/2026

Weco AI retweeted
Production autoresearch is usually killed by reward hacking or side effects.
But we still see a pattern that survives: the unit been evaled is functional or near-functional code.
Some examples: (1/5)🧵
Weco AI retweeted
Haha, thanks for remembering Weco Observe!
We’ve been working in the autoresearch space for about three years, though, before it even had this name. It actually started with: github.com/WecoAI/aideml

Weco AI retweeted
Comparing Opus 4.7 vs 4.6 on AutoResearch.
Opus 4.7 isn't significantly more sample-efficient, but is surprisingly cheaper due to fewer function calls.
Details in 🧵(1/4)

Weco AI retweeted
Is autoresearch really better than classic hyperparameter tuning?
We did experiments comparing Optuna & autoresearch.
Autoresearch converges faster, is more cost-efficient, and even generalizes better: 🧵(1/6)

Weco AI retweeted

awesome-autoresearch — 一个把 AutoResearch 真实应用案例和开源实现整理到一起的索引仓库
帮你快速看清 AutoResearch 这套 loop 到底已经被迁到了哪些任务上。
从 nanoGPT 训练,到 Shopify Liquid、CUDA kernel、voice agent prompt、表格建模,覆盖面比我预想的大。
github.com/WecoAI/awesome-au…

Weco AI retweeted
AutoResearch is a general purpose code optimizer, and math formulas can also be expressed as code.
The emerging use case of formula discovery is really interesting, give it empirical data and let the agent search for math expressions that fit.
Examples 🧵(1/5):
Weco AI retweeted
The replies surfaced a lot of amazing use cases, more than I expected. There must be more outside my radar.
Creating a curated list here, PRs welcome for your own use cases, ideally with traces so the community can verify!
github.com/WecoAI/awesome-au…

Weco AI retweeted
Autoresearch has been out for 2 weeks. The community is trying to apply it to everything with a measurable metric, here are some successful attempts: 🧵 (1/6)
Weco AI retweeted
Your autoresearch needs its own Weights & Biases.
We’ve turned Weco into an observability tool that lets you monitor, analyze, and share autoresearch runs. Here's what it can do: 🧵(1/4)
Weco AI retweeted

We @GoldenVentures write 500K-3M checks, pre-seed/seed, sector and geography agnostic. The only constant we hold is exceptional founders. DMs are always open
Recent deployments:
- Self-improving code (@WecoAI )
- AI drug repositioning (biossil.co/)
- Canada's defence neo-prime (@DominionDynamic)
- The world's best basketball league (@brodierec)
- Novel reactor for lithium refining (chemshift.com/)
- Autonomous transportation (@Waabi_ai)
Weco AI retweeted

Currently set up to use aide agents with kernelbench and a couple other tasks, but easily adaptable to @karpathy’s experiments: github.com/AlgorithmicResear…
