

Building agentic and tiled stuff @UofIllinois | prev @togethercompute @ZJU_China
San Francisco, CA
Joined November 2023
- Tweets112
- Following1.1K
- Followers666
- Likes313


Very insightful post from @simran_s_arora @dylan__lim @reyna_abhyankar at @togethercompute that investigated the tradeoffs between Torch Compile and Megakernels which leads to the magical Together Compile! Always investigate in both sides!

Checkout the video in @dylan__lim's post to see the hidden bubbles: Look Ma, Some Bubbles
Building on a long and wonderful tradition in Hazy lab of always investigating both sides (tb to S4 no attention vs FlashAttention)

Weili Xu retweeted

Last Year We Built Megakernels. This Year We Deleted Them.
One year ago, we helped introduce some of the first AI megakernels to the world. Since then, we’ve enjoyed seeing their wide adoption from friends and researchers. However, while whole model megakernels are a helpful abstraction, we’ve found that they overcomplicate and are not always an ideal optimization target.
Below, we discuss our journey to understand and push past these limitations. We start with a deep dive into two contrasting paradigms of ML optimization – Torch Compile and Megakernels

Two weeks ago we announced Together Compiler: agents that tune inference to your model, chip, and traffic, for up to 2.6x more throughput.
Today, we’re sharing the journey behind it: the experiments that challenged our assumptions of megakernels, the surprising strengths of Torch Compile, and the lessons that shaped our development of a next-generation system for inference optimization.
Shout out to @dylan__lim @reyna_abhyankar @simran_s_arora and the team!
Read more: together.ai/blog/road-to-tog…

Speedup your agent by 14x with Evolving Infra! teapawt.org/Mlsys_HaoKang/status/2…

We breathed life into LLM system.
Introducing Evolving Infra⚙️: an inference framework that adapts diverse and dynamic agent workload purely online and retires fixed PD disaggregation.
vs. NVIDIA Dynamo on up to 256 GB300 GPUs:
➡️ Up to 4.1× lower latency
➡️ Up to 14× lower P95 TTFT
➡️Up to 2.36× more revenue
on real agent traces(Computer Use, Coding and math agents) and opensource models.
🌐 Website: inference-rsi.com
📄 Tech report: alphaxiv.org/en/abs/2611.123…
💻 Code: github.com/mit-han-lab/Evolv…
Which agent(e.g. Pi/Openhands) do you want us to accelerate next? Tell us below 👇

2
18
985
Weili Xu retweeted

We breathed life into LLM system.
Introducing Evolving Infra⚙️: an inference framework that adapts diverse and dynamic agent workload purely online and retires fixed PD disaggregation.
vs. NVIDIA Dynamo on up to 256 GB300 GPUs:
➡️ Up to 4.1× lower latency
➡️ Up to 14× lower P95 TTFT
➡️Up to 2.36× more revenue
on real agent traces(Computer Use, Coding and math agents) and opensource models.
🌐 Website: inference-rsi.com
📄 Tech report: alphaxiv.org/en/abs/2611.123…
💻 Code: github.com/mit-han-lab/Evolv…
Which agent(e.g. Pi/Openhands) do you want us to accelerate next? Tell us below 👇

Weili Xu retweeted

🤔 Is score centering (SC) all we need for stable async RL?
People often stack truncated importance sampling (TIS) or KL penalties on top of SC. In a fun side project, we tested how much they help.
We found that SC alone often matched on-policy. But when it fell short, adding more corrections doesn't necessarily help. 🧵

Weili Xu retweeted

FlashState is out ⚡️
Wild to see so much love for this! It started with a long car ride to SFO with @_weilix, chatting about ideas that grew out of Weili’s summer at @togethercompute, and here we are.
So much fun co-leading this with Weili!
Next up at @togethercompute : taking it from research to distributed production serving, and bringing it to more diverse models, agentic workloads, and newer hardware.
Long road ahead, stay tuned! 🚀

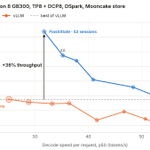
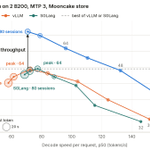
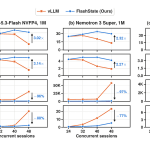
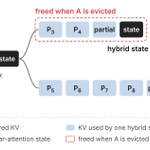
Introducing FlashState ⚡: an inference system that flexibly manages the prefix cache of hybrid LLMs, designed for agentic workloads.
On GLM 5.3 Flash, FlashState more than doubles vLLM's throughput and provider profit, while cutting latency by 3.7× and user cost by 2.5×.
Tagging folks who might be interested in FlashState! Who are also my heroes and much of the reason why i started looking into linear attention and efficient architectures since my second year of undergrad two years ago! @SonglinYang4 @simran_s_arora @tri_dao @_albertgu @realDanFu @Mlsys_HaoKang @wenhaocha1 @Xinyu2ML
8
1,413
Weili Xu retweeted

Is claude code usage nerfed for max 20x this week? Feeling like it depletes much faster...
We open source everything, and we can't wait for you to give FlashState a try! 👋
💻 Code: github.com/FutureMLS-lab/Fla…
📄 Paper: alphaxiv.org/abs/2611.flashs…
🌐 Project Page: flashstate.ai

It's been a lot of fun and learning to work it out, with @connorliml, @tianyi___zhang, @JueWANG26088228, @ZhongzhuZhou, and @Chenfeng_X!
#AgenticAI #MLsys #vLLM #LLMinference #DeltaNet #mamba #attention #gpu #inference #infra #nvidia #KVCache #AIinfra #SGLang #kimi #glm #qwen #LLM
3
23
3,008


Weili Xu retweeted

Introducing the Together Compiler: continual compilation for AI inference! I’m super proud to finally share this work from our research team! ✨
Today’s inference is “Polymorphic” or shape-shifting, it doesn’t sit still. On OpenRouter, 80% of traffic goes to models released in the last three months and the top ten most popular open models each use a different architecture. Our customers constantly change their usage behaviors. Together Compiler leverages agents to continually optimize our deployments immediately as these changes occur.
Together Compiler research highlights include:
1. 252x better throughput: TKCC lets agents try 252x more optimization experiments per hour compared to prior agent inference optimization systems.
2. State-of-the-art TPS across InferenceX workloads we tried: TKCC outperforms the best InferenceX engine across all tested settings in just 24 hours & 2 nodes per compile. Including 1111 TPS on MiniMax M3.1 B200 and 1205 TPS on DeepSeek v4.1 Flash GB300 at batch size 1. NVIDIA, AMD, Trainium2.
3. Continuous recompilation: TKCC currently serves many trillions of production tokens per day and adapts to traffic shifts within just a few hours of recompilation.
4. Bitter lessons: TKCC’s design builds on 2+ years of building frameworks to accelerate AI Inference, starting from ThunderKittens and Megakernels. Compilers have always used abstractions and IRs, but we show that agentic compilers now reach higher performance ceilings without abstractions.
From an incredible team @reyna_abhyankar @dylan__lim @realDanFu @togethercompute!!