

Research @illuintech | @CentraleLyon @UniOfSurrey
Paris
Joined September 2024
- Tweets124
- Following158
- Followers65
- Likes435





Pinned Tweet
🏛️ LLM agents in a new environment repeat the same mistakes.
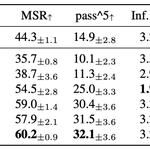
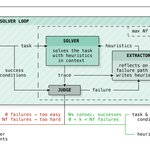
Meet DAEDALUS: agent memory bootstrapped from tasks the agent writes itself, with no training tasks or human-written guidelines. It makes 7 agents from various model families succeed more often, in fewer turns
🧵⬇️

Cool blog post by Zhuchenyang Liu on pure-vision retrieval pipelines, including a test of a decision model as a reranker.
🔗 huggingface.co/blog/Ryenhail…
⬇️

Internally, we've seen good results with other setups, such as scoring relevance page by page instead of one forward pass over 16 pages.
I'd love other inputs on the best way to use them at inference.
Also, something nice around decision models is coming soon @MaceQuent1 👷
1
17
Antoine E. retweeted

Embeddings vs. Grep: Rethinking the Dense Advantage in Code Search
Ant Group finds that dense retrieval's lead over BM25 in code search shrinks under fairer evaluation.
📝 arxiv.org/abs/2611.20455
👨🏽💻 github.com/hq-bench/repo-pre…

Antoine E. retweeted

Hey everyone! I am super excited to share our new research report! 🎉
Scaling Reranked Retrieval 🚀
Thread with more details! 🧵 (1/17)


Antoine E. retweeted
I love the idea of finding an optimal representation for a given environment! EnvOpt seems orthogonal with DAEDALUS (finds procedural heuristics, no training task needed), so combining both looks like a promising research direction.

Introducing our latest research: Environment Optimization (EnvOpt).
An agent's cost and performance depend on
1. The model 2. The harness and 3. The environment structure. There is a lot of work on optimizing 1 and 2, but here we study how the environment presents information to the agent, and how that affects performance and cost.
For example, a company's Slack workspace, documents, databases and code repos can be given to an agent in different ways: Slack can sit behind a remote server, accessible via MCP or exported in plain text files that can be read and searched with grep. This choice alone can significantly affect how much work the agent needs to perform to solve a task.
Environment optimization is only meaningful in what we call stationary environments: These are environments with large collections of artifacts that remain the same across many tasks. We propose optimizing stationary environments as a third axis for improving LLM agents, alongside model training and harness optimization. This optimization can be amortized over multiple tasks and can be combined with harness and model optimization techniques.
Across five benchmarks covering workspace tasks, data engineering and software engineering, ENVOPT reduces the cost of the target agent on unseen test sets by an average of 48%, with higher or similar pass rates. On AutomationBench, ENVOPT outperforms
Meta-Harness by 9.67% with only 15% of its cost.
We also show that ENVOPT constitutes an optimization direction orthogonal to harness optimization and parameter tuning in two ways:
(1) the environments optimized for the target agents can transfer to other agents, even with different
harnesses and models (2) we combined ENVOPT with Meta-Harness, showing similar cost reductions and 16% improvement in pass rate, outperforming either Meta-Harness or ENVOPT alone.
Read more in our blog: bespokelabs.ai/blog/envopt
paper: arxiv.org/abs/2611.07372.pdf


Antoine E. retweeted

Introducing Ardia, the open-source Arc
I've been working on this for a few months now. It's feature-complete, already used by a bunch of former Arc users, and extremely performant.
github.com/mantrakp04/ardia


We've decided to sunset Arc on December 22, 2026.
That's not an easy sentence to write. We spent years building Arc and celebrating each and every release along the way: we have so much pride and love for what we made alongside the Arc community.
Our priority is to deliver best-in-class security for our members. Keeping a browser secure takes constant, dedicated work that is only increasing in the age of AI. Dia was built from the ground up to meet today’s security standards, so that's where our engineering and security teams will focus moving forward.
We've worked to make switching to @diabrowser as easy as possible for Arc members. Here's how:
· Your passwords, bookmarks, extensions and history come over to Dia seamlessly.
· Spaces, Folders, and Tab Groups are in Dia and import over with your data intact.
· Dia now surpasses Arc benchmarks in stability, speed, and security.
· The browser features you use in Arc are free in Dia, and the AI is optional.
Thank you for using Arc, for pushing us to make it better, and for building alongside us. The team that made Arc is the same team behind Dia, and some of our most ambitious work is just ahead. We'd love for you to be there with us when it lands.
Antoine E. retweeted
Token pooling could already achieve insane compression for late-interaction multimodal retrieval (ColPali, NeoMME). Now imagine how far we could push this with @tomaarsen's pooling-aware training!


My two attempts today, very very tricky
fauxlio.app #2 · 2026-10-27 · 🇫🇷
❌❌✅❌✅ · 2/5
jouer sur : fauxlio.app/fr/daily
fauxlio.app #2 · 2026-10-27 · 🇬🇧
❌❌✅✅✅ · 3/5
play at: fauxlio.app/en/daily

🧩 Can you tell a real book from AI writing?
We built a fun little game called fauxlio.app
Two excerpts: one's a classic, one's AI, and your goal is to pick the real one. 5 new rounds a day, EN/FR, free, no sign-up.
Tell @VictorTXing and me what you think! 🫶
1
4
164
Antoine E. retweeted

There's been a lot of debate lately about whether you can tell AI-written literature from human writing
@antoine_edy and I made a daily game to find out how good you are at it
Try it out at fauxlio.app

🧩 Can you tell a real book from AI writing?
We built a fun little game called fauxlio.app
Two excerpts: one's a classic, one's AI, and your goal is to pick the real one. 5 new rounds a day, EN/FR, free, no sign-up.
Tell @VictorTXing and me what you think! 🫶
🧩 Can you tell a real book from AI writing?
We built a fun little game called fauxlio.app
Two excerpts: one's a classic, one's AI, and your goal is to pick the real one. 5 new rounds a day, EN/FR, free, no sign-up.
Tell @VictorTXing and me what you think! 🫶

Antoine E. retweeted

Sylvia Serfati sur la révolution de l'IA en mathématiques
"La plupart des résultats d'OpenAI mériteraient la médaille Fields".
"Les preuves sont d'une complexité incroyable et aussi parfois d'une beauté impressionnante. C'est-à-dire que nous n'avons pas le monopole de la beauté."

Passionnante réflexion des mathématiciens @Amaury_Hayat et Sylvia Serfati sur l'avenir de leur profession à l'ère de l'IA : la résolution de problèmes ne sera plus notre rôle, et poser les bonnes questions, sans doute que même l'IA le fera mieux que nous à terme...
Antoine E. retweeted

Should you waste tokens having your coding agent use grep, or hand the search to a tiny local model?
We release ColGrep-Agent-2B! A code-search agent that runs locally, searches with ColGrep, reads files, & returns locations + code to your main agent
-> 34% fewer API tokens

Antoine E. retweeted

1/n Our paper REPA-G is accepted at #NeurIPS2026! 🎉 I'll present it at the NeurIPS Paris site 🇫🇷.
We introduce test-time conditioning of REPA-style diffusion models with visual features, with no extra training.
Antoine E. retweeted

🚀 LightOnOCR-3 is out! 🦉
This time we go beyond OCR: text transcription, document layout, image descriptions and chart extraction, all in one model.
We release 3 sizes: 0.8B, 1B and 4B, all under Apache 2.0!

Antoine E. retweeted

Nouvelle vidéo ! L’IA va-t-elle tuer les maths ? Entretien avec Hugo Duminil-Copin
Médaillé Fields 2022, Hugo nous raconte l’irruption de l’IA dans les maths, et pourquoi il a décidé personnellement de s’en passer dans son processus créatif de recherche
youtu.be/HJFk7D5Vufc

Antoine E. retweeted

And if you want to have a more enjoyable reading time (or if you just like scrolling through fun animations), check out our beautiful blogpost made by the artist of the team @antoine_edy! 🧑🎨 You'll also learn about the meaning behind the name 🏛️🫣 (8/n)
illuin-tech.github.io/daedal…
