

Research in NLP @illuintech, CS MSc @epfl
Paris
Joined September 2024
- Tweets49
- Following104
- Followers54
- Likes152




Max Conti retweeted

🏛️ LLM agents in a new environment repeat the same mistakes.
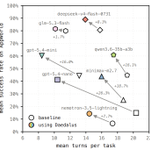
Meet DAEDALUS: agent memory bootstrapped from tasks the agent writes itself, with no training tasks or human-written guidelines. It makes 7 agents from various model families succeed more often, in fewer turns
🧵⬇️

Our latest work at @illuintech is out! 🕺
DAEDALUS is a training-free pipeline that generates priors on any new environment, that an agent can use in-context at test time.
No tasks/verifier/human-written guidelines required!
Details and fav take-aways in the thread below 👇 (1/n)

This post would not be complete without an enormous thanks to the amazing team that made this project possible but most importantly really fun @antoine_edy, @victortxing, @marcantallard, @Nawfal_BENH and Gautier! 🫶 And for the unconditional support @MaceQuent1 🤝 (9/9)
1
3
69
Max Conti retweeted

Love the blog's title, nice wink at our work with @mlpc123 ! More importantly, I love the content ! Contextual embeddings is a super high potential direction with lots to do! Still waiting on 1M context window parallel embeddings though @antoine_chaffin @bo_wangbo 😘

We built a new way to train contextual embedding models, which encode each chunk of a document with the whole document in view.
pplx-embed-v2-context-9b-preview sets a new state of the art on ConTEB and @turbopuffer's new, privately held context-bench.
perplexity.ai/hub/blog/conte…

Max Conti retweeted

I will be in Seoul with @marcantallard this week for ICML to present ModernVBERT 🇰🇷
Our poster session on Wednesday from 10:30PM in Hall A (#4104). Come chat with us!


Max Conti retweeted

if you write some really good code these days everyone thinks you did it with Claude Code. if you lose a lot of weight everyone thinks you did it with Ozempic. at least you can still be really good at dancing. they don't make ozempic or Claude Code for being good at dancing
Max Conti retweeted

okay maybe it's a good time? We have a small colbert model trained at pplx, it is a continue-training of pplx-embed-0.6b, so native multilingual, just made it open and added a section how to use MaxSim kernel:
huggingface.co/perplexity-ai…


Releasing my first kernel on @huggingface:
MaxSim
Late-interaction retrieval (ColBERT / PyLate) bottlenecks on materializing the full similarity matrix. This kernel avoids it by using tiled scoring with simdgroup_matrix (Metal) and WMMA.
Result is 3–5× speedup compared to naive PyTorch.
Try it out 👇

Exciting publication alert!! Congrats to the whole team for the nice ideas and thorough execution 🎯
Hyped to take the time to deep-dive into every part :)

🚨 Do LLMs need to store everything they read in memory?
To reduce KV cache size and improve decoding speeds, we propose Self-Pruned KV attention, a mechanism where the model learns to decide which KVs to write in the persistent KV cache, discarding all the rest! @AIatMeta🧵

2
114
Max Conti retweeted

We're releasing LateOn and DenseOn today. Two open retrieval models, 149M parameters each.
LateOn (ColBERT, multi-vector): 57.22 NDCG@10 on BEIR.
DenseOn (dense, single-vector): 56.20.
Both beat models up to 4× larger
We're open-sourcing the weights under Apache 2.0 🧵👇

Max Conti retweeted

The new generation of open state-of-the-art single and multi-vector retrieval models is here
It's time, DenseOn with the LateOn 🎶
@LightOnIO releases models that leap past existing ones, and everything you need to do the same!

Max Conti retweeted
Update on the Late-Interaction Workshop @ ECIR2026: it was amazing! 🇳🇱
So cool to meet late-interactors IRL for the first time, I enjoyed every bit of that day 🤗 And congrats & huge thanks to the organizers again.
Link to our work + poster below ⬇️


Looking forward to meeting fellow late interactors! 🤓🇳🇱

@mlpc123, @MaceQuent1 and I will be at the Late Interaction Workshop at #ECIR2026 on Thursday 🤗 See you in Delft 🇳🇱
1
73