

Founder @Onehousehq — Data Infra for Agents. Creator of @apachehudi, built the first #DataLakehouse @Uber. Databases, Dist. Systems. LinkedIn, Confluent.
Joined April 2009
- Tweets1.4K
- Following235
- Followers1.9K
- Likes833





Vinoth Chandar retweeted

Google Cloud Dataproc 3.0.2 now supports Apache Hudi 1.2.
This brings native VECTOR, BLOB, and VARIANT types to managed Spark clusters on GCP.

Vinoth Chandar retweeted

"Async compaction" is easy to claim. Building one that doesn't stall ingestion is much harder.
Every mature database figured this out decades ago.
✅ Foreground writes establish correctness.
⚙️ Background maintenance restores efficiency.
The two shouldn't block each other.
As lakehouses evolve from batch-oriented systems to continuously mutating platforms powering CDC, streaming, and AI, that architectural separation matters more every year.
My latest blog explores why background maintenance isn't just another feature—it's an architectural primitive.
👇🔗 hudi.apache.org/blog/2026/07…
#ApacheHudi #Lakehouse #DataEngineering #StorageSystems #DistributedSystems #OpenSource


Vinoth Chandar retweeted
Indexes are first-class in Hudi from day one.
Lakehouse formats that skip indexes pay 10-100× more read amplification on updates — they join every incoming record against the entire dataset to figure out what to rewrite.
The multi-modal indexing subsystem ↓

Vinoth Chandar retweeted
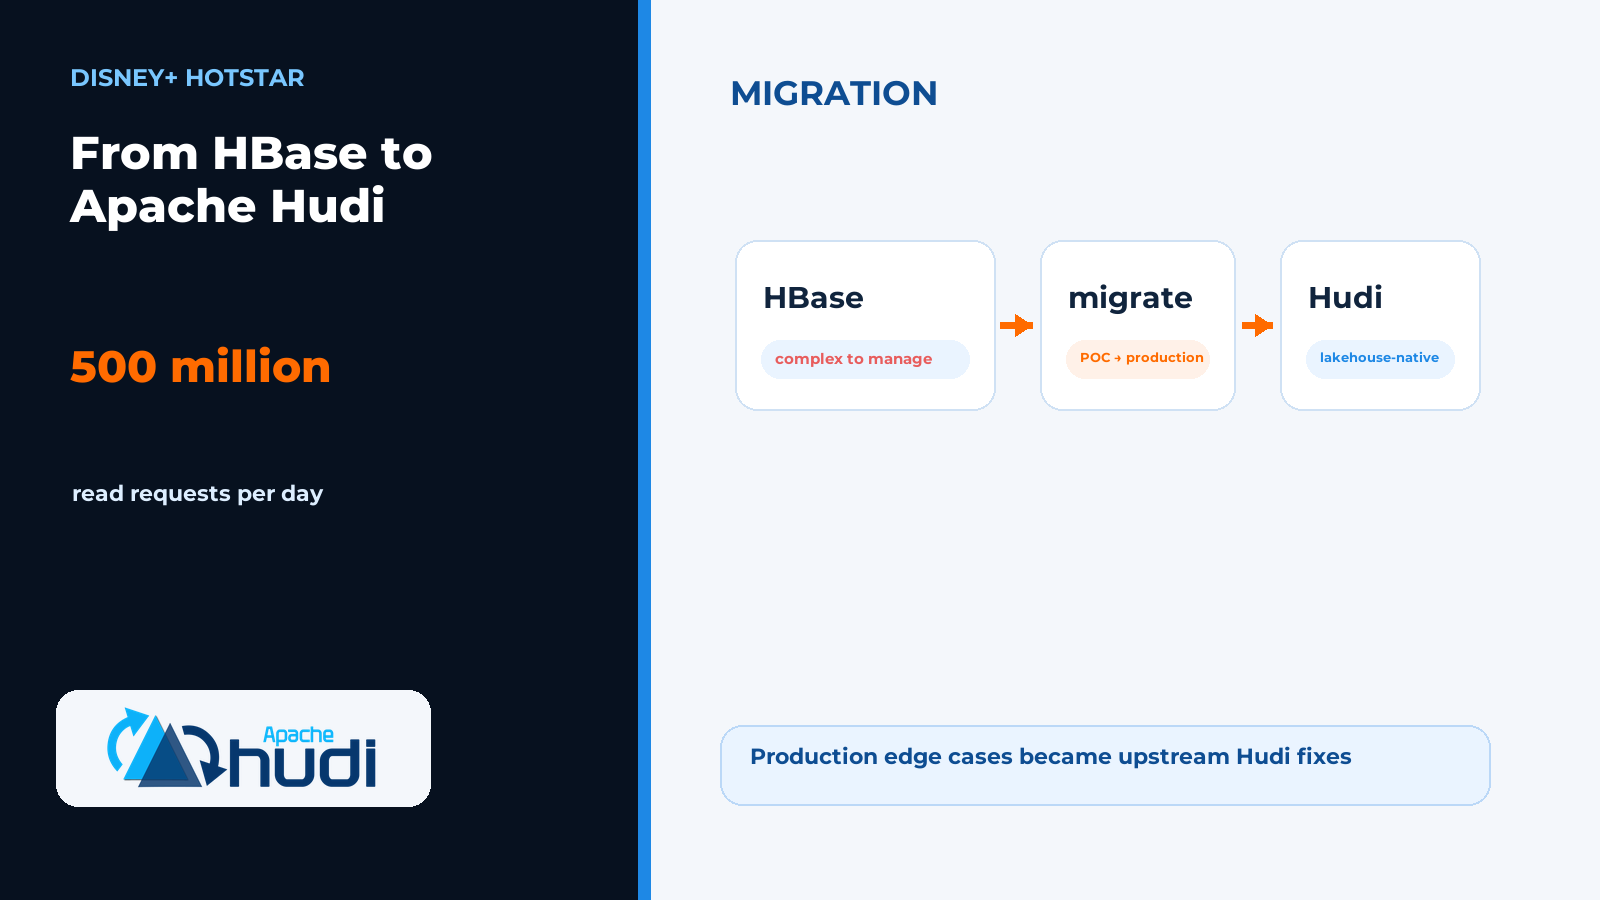
Disney+ Hotstar served 500 million read requests per day on a data lake powered by Apache Hudi.
The original platform was Apache HBase ↓
Vinoth Chandar retweeted
Walmart ran Apache Hudi across 600,000+ Spark cores. They picked it via weighted scorecard against Iceberg and Delta.
Two real workloads tested ↓

Vinoth Chandar retweeted
The Hudi file group is the primitive that makes Lance fragments, RFC-80 column families, and wide AI tables all click into place.
One record key → one file group. Indexed, versioned, concurrency-controlled.
Two AI workloads land on it ↓

Vinoth Chandar retweeted
JD.com built a 125+ petabyte retail data lake on Apache Hudi.
Record-level mutations on commerce data at planetary scale ↓

Vinoth Chandar retweeted
Why inline pays off:
• One read fetches metadata + bytes
• 10K thumbnails = 10K rows, not 10K S3 objects
• File sizing service consolidates into right-sized base files
• read_blob(content) to materialize bytes
Vinoth Chandar retweeted
GE Aviation: 30+ source systems in production, several hundred Apache Hudi tables, 14+ months in production, 10,000+ tables in the dev pipeline.
Modernizing 150+ source systems across the aviation ecosystem ↓

Vinoth Chandar retweeted
Picture your lakehouse bogged down by updates at 10TB scale 📊?
Core issue: Finding records without scanning full table.
Hudi's file groups route same-key records to one group with base/log files 🔑.
Updates are bound to that group 🚀—skip full searches.
Wins:
• Bounded write locality
• Limited scans for merge reads/compaction
At scale, this stabilizes ingestion vs. messy maintenance or sluggish MERGE INTO 🛠️.

Vinoth Chandar retweeted
Building indexes on a 100 TB Hudi table without blocking writes.
The naive approach: stop writes, build the index, resume. Hours of downtime.
Hudi async indexing: bootstrap index, then converge , high concurrency ↓

Vinoth Chandar retweeted
Compaction isn't just housekeeping 🧹—it's deferred write work in Merge-on-Read systems 📝.
Append changes to logs for fast ingestion 🚀, then compaction folds deltas into optimized base files 🔄.
Real question: When to pay back that deferred cost? ⏳
It affects:
- Ingest latency ⏱️
- Read performance 📈
- Storage efficiency 💾
- Background resource usage ⚙️
Hudi makes this tradeoff explicit, treating compaction as a first-class table service.

Vinoth Chandar retweeted

Data engineers: hours tuning Spark jobs, yet Hudi, Iceberg, or Parquet reads still take minutes? We've all been there.
Most pipelines bottleneck pre-join. Details below 👇
Vinoth Chandar retweeted
Hudi's merge spill storage draws from BitCask 💡
BitCaskDiskMap appends values to a single log file. In-memory ConcurrentHashMap tracks key metadata: offset, size, timestamp—keeping memory low for quick offset reads 📊
ThreadLocal BufferedRandomAccessFile handles enable lock-free concurrent reads 🔄
CRC checksums on writes, validated on reads, catch disk corruption early ✅
ThreadLocal compression caching reduces allocations in heavy spills ⚙️
Go-to backend for ExternalSpillableMap: handles MOR merge spills with fast appends and random access 🚀

Vinoth Chandar retweeted

Excited to moderate the "Open by Design" panel at #OpenXData2026! 🚀
We’re bringing together leaders from across the @apachehudi , @ApacheIceberg , @prestodb , and @ApacheFlink ecosystems to talk about why community is the true foundation of open data.

Vinoth Chandar retweeted
Ruiyang Wang works on pretraining infrastructure at Anthropic. If he says PDFs belong in your threat model, that should get your attention. 🛡️⚠️
At #OpenXData, Ruiyang is laying out a rasterize-first architecture for safe PDF processing at scale: sandbox the file, render it to images, then OCR. He previously spent years on Ray at Anyscale and now builds large-scale data pipelines at Anthropic. That is a strong setup for a talk about handling hostile documents without losing sight of quality.
If PDFs touch a training pipeline, RAG stack, or document ingestion flow in your org, register here: openxdata.ai/
#OpenXData #DataEngineering #MLInfra #AIPipelines #AISafety


Vinoth Chandar retweeted
Hudi Newsletter #23 is out 🚀
📊 Uber's trillion-record Hudi deployment — native Record Index, no HBase
🔄 AWS guide to multi-table CDC ingestion on EMR
⚡ Hudi 1.1 deep dive: async instant time generation for Flink
hudinewsletter.substack.com/…
#ApacheHudi #DataLakehouse #DataEngineering

Vinoth Chandar retweeted
[New Blog] Your streaming pipeline ingests data every minute. A nightly GDPR job kicks off. By 3 AM you're paged—the deletion job keeps failing, burning compute while ingestion wins every commit race. This is the retry storm problem with OCC.
@apachehudi NBCC solves it 👇
Blog by @_xushiyan : hudi.apache.org/blog/2025/12…
