
software engineer working on exchange infrastructure
Dubai
Joined February 2026
- Tweets167
- Following294
- Followers129
- Likes611




Pinned Tweet
Whitepill: a solo engineer with a good agent can still move surprisingly fast on serious systems work - even against a $20B company’s engineering team.
I came across this tweet about Polymarket’s new Rust matching-engine targets: 200k orders/s, with a path to 400k. I had to do a double take and dug up a matching engine I built with Fable 5 over one weekend in July as part of a larger prediction-market arbitrage system.
9.65M commands/s on a 6-core i5. 2.25µs command-apply p99.
A throughput number 25–50x higher from something built in a hobbyist capacity.


Honest post: the Polymarket DeFi CLOB is full of tech debt. It grew fast, got hacked together, and most of the team inherited it that way. Since joining and building out the team, we have scaled it 10x and made it 3x faster, but it’s not enough; the core foundations of how it’s been built are wrong in almost every way. You try to fix one thing, and another thing goes wrong; the conclusion now is that the codebase can’t be saved long-term.
The exchange is the heart of Polymarket; everything runs through it. If we want to be the best exchange in the world, it must be fast, stable, and scalable. We can’t keep patching the old one, where these core foundations are generally missing throughout, so we’re rewriting it from scratch in Rust.
Early numbers: 10-20x faster on p99 than today, 200,000 orders per second (15x what we have now, with room to reach 400,000+), and stability under load. This will put us faster than most exchanges, including CEXs.
Building it in Rust gives us memory safety with no garbage collector. No GC means no random pauses and no random latency spikes; the tail latency in the benchmarks is the tail latency you get in production, alongside a strict compiler that enforces correctness up front. Data races and memory corruption (the bugs that take exchanges down) can’t exist in the first place.
Polymarket has to take it seriously that we are an exchange; this is people’s money, not a joke. To succeed, we have to fix this; otherwise, we will fail. It’s as simple as that. I joined to build the best software in the world, not to maintain some of the worst, and I will do everything I can to make Polymarket a serious exchange.
We are aiming to have the exchange ready sometime in Q4 (mid to end). I'll communicate progress as we go so you all know the status. Breaking changes will be minimal for all integrators and will be communicated in advance. We will maintain the existing CLOB and keep trying to improve it as we build this side by side. We can’t wait to throw away the existing CLOB; we dislike it as much as you all do.
Make Polymarket fast, finally.
wait lemme get this straight? Kalshi pauses their exchange every week for 2 hours preventing people from cancelling their resting orders and when the exchange comes back online the stale liquidity can be sniped even if the event is settled...


with all these security vulnerabilities coming out, need to stay on top of keeping everything up to date while at the same time not updating immediately to avoid the increasing threat of supply chain attacks lol
compute markets will be the most liquid markets in a few years

spent the last few weeks deep in compute markets and the more i look the more bullish i get
agents are about to be the biggest buyers of compute in the world. they run 24/7, call models nonstop and pay per request with their own wallets
but right now they all buy at whatever price the pricing page says. no way to lock in a rate, hedge a spike or borrow against future usage
no business would run like that and agents won’t either
the teams building spot, forwards and credit for compute are building the cme of the ai economy
great chat about orchestration, trusting agents and being more meditative about your setup

Super excited to be interviewing @poteto, live, in ~48 hours on YouTube.
We'll be nerding out about skills, high-velocity software factories, and learning SOTA techniques for shipping with agents.
This Friday - 9AM PT. Don't miss it!
youtube.com/live/MN9dGgmLyso

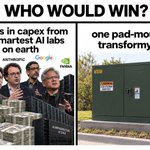
pad-mounted transformer bottleneck? how do i long these


Data center lead times getting beyond control
As shared by Cushman & Wakefield / Hyundai Securities, it’s not down to GPUs or even memory.
- Copper, aluminum: ~4–10 weeks
- Most HVAC / chillers: ~15–30 weeks
- UPS, LV/MV switchgear: ~35–60 weeks
- Generators: up to ~100 weeks
- Pad-mounted transformers: up to ~115 weeks
One can construct building faster than getting the transformer that powers it.
#DataCenters #AIInfrastructure #SupplyChain

ALT Made with AI

This is why benchmarks don't matter anymore. Some LLM's are way better at facilitating work than others:
- eagerness
- the way they talk
- not overengineering everything
Same way that optimal strategy for choosing coworkers is not IQ

With LLMs, we like to think of "smart" and "dumb" as one axis (because we think of humans this way).
I'd like to argue against this framing. Instead, try to think of "smart" and "dumb" as two different axes. A model can be incredibly smart AND dumb at the same time.
For a good example of this, look at a Gemini model. They are incredibly smart: you can bench them and see the capability. The amount of knowledge Google bakes into their models is incredible. Yet when you ask it to do work, the amount of stupid things the models will do is similarly incredible. They are "smart" and "dumb" at the same time.
Similarly, look at a model like Fable 5.1. It is not quite as smart as Astra, but it is significantly less dumb. Astra is still the smartest model available today, but it is also one of the dumbest, regularly doing things that make literally no sense whatsoever.
Finding the right balance of both "smart" and "dumb" is a challenge that everyone needs to figure out, from users to researchers. If we stop thinking of it as either-or and instead realize both can exist together, understanding model behavior gets much easier.
strongly believe coffee shop working is a trauma response for wage cage escapees. they're stuck in a perpetual performative larp
not productive

i simply do not understand how ppl get any serious work done in a coffee shop, cafe, or any space that is constantly noisy, inconsistent, & unpredictable.
conversations, espresso machine noise, music, ppl coming & going, random phone calls, god damn. every few minutes your brain gets context switched by something.
lots of coffee shop work seems more like productivity larping than any real work. kudos to those who can actually pull it off. i need a real office where i can have my perfect environment setup where i don’t have to bring anything, move the mouse & i’m ready to go.


source: harnesstax.github.io/
defo feels like Jev will replace these use cases where a rigid interface and super specific task was being codified.
a lot of llm's were being abused for classification type (rigid) tasks since llm's are so flexible
