
research @cohere_labs | phd from @UvA_Amsterdam | prev @Amazon @nx_ai_com
Amsterdam, The Netherlands
Joined April 2009
- Tweets137
- Following1.1K
- Followers310
- Likes1.6K


David Stap retweeted

Check out our paper on @askalphaxiv with a nice summary and a 5-min podcast!
alphaxiv.org/abs/2609.10445
Tiny Aya L2-Thinker beats models 2-7x its size on in-language reasoning rate and task accuracy on data-scarce languages.


Happy to present Tiny Aya L2-Thinker, a massively multilingual model at 3.35B scale with 32K context length trained for in-language reasoning in 45 languages. 🌎
We take a data-centric approach, combining multilingual reasoning, non-reasoning, and English reasoning data and achieve above 90% in-language reasoning rate evaluated on 60 languages across 6 benchmarks covering math, open-ended generation, cultural and commonsense reasoning, and instruction following.
We're releasing the model weights + multilingual reasoning data covering 44 languages besides English, the largest coverage of multilingual reasoning data we’re aware of.
Read the thread to learn about our findings. 🧵
arxiv.org/abs/2609.10445

David Stap retweeted

Comparison of sub-quadratic architectures xLSTM, Mamba-2, and Gated DeltaNet: arxiv.org/abs/2606.12364
Comparison of xLSTM, Mamba-2, and Gated DeltaNet on code pre-training, distillation, and time-series.
xLSTM outperforms the others due to its gating scheme and state tracking.

David Stap retweeted

New paper "On Subquadratic Architectures: From Applications to Principles" 🙌
On commonsense & reasoning benchmarks, xLSTM, Mamba-2 & Gated DeltaNet perform nearly indistinguishably.
Therefore, we analyse them where structure genuinely matters: on code & time series.👇

David Stap retweeted

After the enthusiasm of the shared task last year, we are running another shared task to create a community-made, culturally relevant multilingual benchmark! The deadline to contribute is August 1 AoE. See more details below.

David Stap retweeted
We are releasing an expanded version of Global PIQA! It now covers 141 language varieties and includes parallel and non-parallel splits. We are also releasing an updated preprint.

David Stap retweeted
📢 Call for Papers:
6th Multilingual Representation Learning Workshop at EMNLP in Budapest, Hungary!
Join us and submit your works relating to multilingual NLP
Speakers to be announced, so stay tuned! 👀
More info in the CFP:
🔗 sigtyp.github.io/ws2026-mrl.…

David Stap retweeted
xLSTM Distillation: arxiv.org/abs/2603.15590
Near-lossless distillation of quadratic Transformer LLMs into linear xLSTM architectures enables cost- and energy-efficient alternatives without sacrificing performance.
xLSTM variants of instruction-tuned Llama, Qwen, & Olmo models.


David Stap retweeted

The call for papers is out for the 5th edition of the Workshop on Multilingual Representation Learning which will take place in Suzhou, China co-located with EMNLP 2025! See details below!

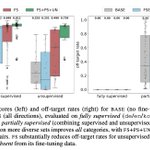
🔍 How does language diversity affect LLM fine-tuning for translation?
We fine-tuned LLMs and found that MORE diversity consistently improves performance - even for language pairs that less diverse models were specifically trained to handle!
arxiv.org/abs/2505.13090

7/8 But there's a sweet spot! When scaling beyond 132 directions to 272 directions, we found benefits plateau or even slightly decrease for well-represented language pairs, while still helping underrepresented languages.
David Stap retweeted

x.com/sethjsa/status/1844737…
Actually we find LLMs learn most/all translation ability from parallel sentences in the book, not the grammar.
And we can predict translation performance just from prompts' test set vocab coverage!
But we do find that grammar can help *linguistic* tasks

Our work “Can LLMs Really Learn to Translate a Low-Resource Language from One Grammar Book?” is now on arXiv! arxiv.org/abs/2409.19151 - in collaboration with @davidstap, @diwuNLP, @c_monz , and Khalil Sima'an from @illc_amsterdam and @ltl_uva 🧵

David Stap retweeted
Our work “Can LLMs Really Learn to Translate a Low-Resource Language from One Grammar Book?” is now on arXiv! arxiv.org/abs/2409.19151 - in collaboration with @davidstap, @diwuNLP, @c_monz , and Khalil Sima'an from @illc_amsterdam and @ltl_uva 🧵