

@ddalcu
🇺🇸Account based in
About this account
- Account based in
- United States
- Connected via
- United States App Store
Account-level information from X, not a live location or the device used for a specific post.
I build OpenSource things, local LLM engines & UI’s. Created https://xitter.cf/t.co/qxuPXH75o1 for Desktop and iOS - https://xitter.cf/t.co/Mdoym1KQbp
Joined June 2010
- Tweets1.1K
- Following931
- Followers2.8K
- Likes2.3K




Pinned Tweet
github.com/ddalcu/mlx-serve/…
Many new models
DeepSeek-V4.1-Flash is much faster
Chat on the Neural Engine
Meeting notes from the menu bar
Speech to text transcriptions api
RDMA
Images, video, music and 3D up to twice as fast on M5 Macs
Frontier models on a 128 GB Mac via Streaming
David Dalcu retweeted

There are so many DiT text-to-image models out right now I had to compare them all!
Seven open models, same prompt, same seed, stock ComfyUI INT8 on my 5090. 1024x1024.
My numbers (seconds per image):
- Z-Image Turbo: 1.4 s
- Qwen Image 2.1 Turbo: 1.8 s
- FLUX 3 Klein: 1.9 s
- Krea 2 Turbo: 2.5 s
- Qwen Image 2.1: 4.2 s
- MOSS-Image SFT: 5.8 s
- FIBO 2 Dev: 17.7 s
Honest take: every one of them nailed the scene. On this seed all seven spelled both signs right. The gap now is style and speed. Qwen 2.1 Turbo kept up with base Qwen at 2.3x the speed, and FIBO 2 is the slow one but has the most natural light and nailed the composition. MOSS-Image is a bit over saturated but has the most intrigue.
All local.
Which one would you choose?


Currently working on 2 things.
1. Full re-write of MLX-Serve to be composable, support plugins/engines. 'mlx-serve plugin install deepseekV10'
2. Full re-write of the Swift code, can be powered by any endpoint(s). Both CLI + GUI, cross-platform.


Btw new MLX-Serve is out, it supports FastH3 Omni, @Recursive_SI Flint, and much more.
github.com/ddalcu/mlx-serve/…


As promised, FastVideo open-sources @MiniMax_AI FastH3 Omni, training code included! 🚀
- Real-time gen @ 12x faster on NVIDIA Blackwell
- NVFP4/FP8 for Spark + RTX!
- ComfyUI day-0
Collab with @NVIDIAAI , Nuva Lab @nuvalab and Reactor @reactorworld
Open source must win! ♥️
David Dalcu retweeted

🚀 Introducing Hy-Nomas: An Open Source Free-Form Interactive Video World Model
Key Features:
* Free-form interaction with text prompts and camera trajectories
* Long-horizon generation with world memory
* Lightweight LoRA adaptation for specialized domains such as robotics
* Optimized for Inference on Consumer GPUs
Test it and drop feedback anytime!
🔗 Website: hy-nomas.hy.tencent.com/
💻 GitHub:github.com/Tencent-Hunyuan/H…
🤗 Hugging Face: huggingface.co/tencent/Hy-No…
🎥 Demo: hy-nomas.hy.tencent.com/demo
#Hy#WorldModels #VideoGeneration #GenerativeAI

Both of these UI's are native code.
One is Swift ~80MB only works on Mac
One is Zig ~10MB works on Mac/Linux/Windows


David Dalcu retweeted

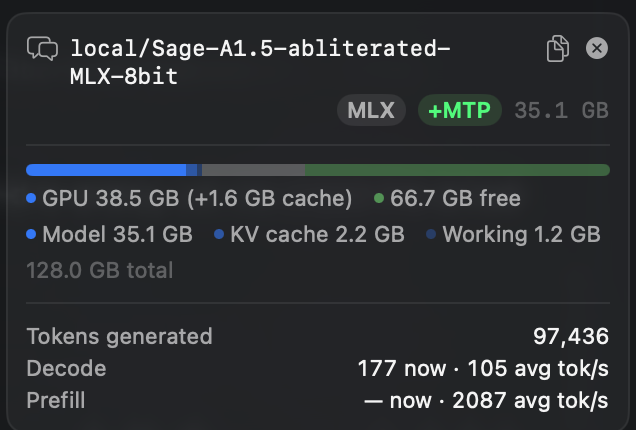
Abliterated (for cybersecurity) Sage-A1.5 hitting peaks of ~140 TPS running on @ddalcu's mlx-serve. Tested with writing php2shell exploit chain, as well as setting up its own test container to run it against. After completion it was still averaging over 100 tps decode and 2k prefill. Will post the hf link for the abliterated model in the comments when I get some more tests done.
This is crazy, all local generated 🤯
MLX-Serve + all the models it supports can make some really cool games !
Deepseek 4.1 @deepseek_ai
Moss image gen @Open_MOSS
Trellis for 3D @MSFTResearch
Yue2 for music @abc43992899
Stability AI SFX @StabilityAI


Picture -> 3D Rendered GLB models don't get enough love.
Claude / ChatGPT / Deepseek 4.1 are good at games, but takes a very long time to create a good looking 3D model.
With an Image model + Trellis2 and Pixal3D it takes a few seconds. Coming soon...


Krea 2 Turbo vs MOSS... I think these might be the best image models right now.
Which one do you think looks better ?


Ivan FTW ! Thanks, merging soon !
Some more performance additions from my poor 5060ti and pushing the merge button.
MLX, DGXSpark, 5060.. Linux... what is going on 🤯 ... oh Windows too... 🤣
github.com/ddalcu/mlx-serve/…


David Dalcu retweeted

Confirmed 24K context on iPhone with both K/V on int8. Delta net stays FP16. Decoding also peaks at 70 tok/s with easy to predict context.
Apple Neural Engine on A20 is fast 🚀

Qwen 3.8- 27B on iPhone 18 Apple Neural Engine.
Added draft model , dflash-2 at ~ 2.8 bpw ( mixed 2-4 vector quantization with small drop in acceptance rate)
Base is @PrismML Bonsai-2, 1.585 bpw requantized to 1.5 bpw ( VQ 6 bits per 4 weights)
Decoding speed is 15-60 tps. Fixed context size 16K.
We might push it to 24K.
6GB to 7GB iOS App ceiling is the main limiting factor.
I like this as PoC .
Any suggestions for actual iPhone App on ANE?