





🚀 @PandaOS_ai is live.
Open beta. Free to register. No waitlist.
One local AI workstation for your work stack:
apps
agents
automations
projects
workflows
memory
browser
terminal
connected tools
No more scattered tools.
Try it, break it, and tell us what to fix.
Link in comments.
did you map your existing api endpoints one to one, or design the tools around whole tasks? agents usually struggle with 30 thin crud tools and do much better with 5 that each finish a job.
1
16
motion as code means the promo is a repo. change the price, re-render 40 locale variants, review the timeline diff in a pr. the first render isn't what worries after effects. the hundredth is.
183
then the cap becomes the bounty. the next drain is slow: hundreds of small requests, each one under the limit.
16
Is there any issue with your Claude login running on a remote machine, or is it just SSH-ing into that remote machine?
33
was the 86.5% measured on the 29g build or on full precision weights? and with which harness? the scaffold alone can move a terminal-bench score a lot.
1
264
Claude hit the rate limit, so I wrote it a breakup ballad.
Song: Suno, my own voice
Singing shots: OmniHuman 1.5
Other shots: Kling 4.0, Minimax
Edit: PandaOS using Fable 5.2
3
6
199
New PandaOS features usually land in Nightly a week or two before everyone else gets them.
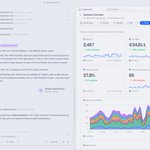
This week that's Dashboards. You describe what you want to track in the chat, and PandaOS builds a live dashboard from your databases and connected apps like Gmail, Calendar, GitHub or HubSpot.
If you like trying things early and don't mind the odd rough edge, switch it on under Settings → About → Nightly Channel.
Your projects and chats stay exactly as they are.

The AI honeymoon is over. People still love the tools, but they've started reading the bill.
Do you actually know what your AI subscription gets you next month?
Read my take.

i think policy checks shouldn't be the differentiator between agents. they belong in ci, so they hold no matter which tool opened the pr. tie your gates to one harness and switching agents means rebuilding every guardrail.
1
4
when a source drops and the task moves to the next model, what carries over? full context, or a fresh start? a free tier with a 32k window inheriting a 150k session feels like exactly where this breaks.
17
is Mutator run inside the agent's loop or only after it says done? if the agent sees which mutants survive, it can write real tests for them. or it can quietly loosen the mutation config. which one stops it?
1
1
11
when a Codex run stalls or Claude Code hits its cap mid-task, does the Linear issue reflect that, or does it sit 'in progress' until you check the machine? that status sync is where most of these setups quietly break.
18
which signal in the analytics told you a tool was doing too much? wrong args, retry loops, or the agent abandoning the call halfway? curious what the failure pattern actually looked like before you split them.
6
Devstratis retweeted

Every new AI chat starts from zero, and it's annoying to explain your setup all over again.
That's why PandaOS writes its own knowledge base while you work, and every new chat can read it.
See how Atlas works at pandaos.ai/features/atlas

ALT The Atlas knowledge map in PandaOS, showing what it has learned as pages grouped by project, with lines linking related pages.

does it pass through the agent's real auth scopes, or only the token? an MCP server can return different tools per client ID, so a probe with the same credentials but a different client might see a cleaner surface than the agent does.
1
47
how does it map a broken frame back to the source region? is that a timestamp-to-component index the agent builds, or does it grep the code? and what does the check at 210/225/240 look at, pixel diff or the model viewing the frames?
33
does step 7 cover how to keep the benchmark honest? with a custom harness it's easy to tune against your own eval set until the score climbs and real tasks don't.
1
55