
@llama_index Always hiring: https://teapawt.org/t.co/5UY8YrAJU7 prev: research @Waabi_ai @Uber_ATG, PhD ML @UofT
San Francisco, CA
Joined June 2010
- Tweets1.6K
- Following2K
- Followers2.2K
- Likes1.3K







simon retweeted

When it comes to hiring, it’s easier to tame a reckless hustler than it is to instill that dawg in someone

PSA: don’t get an MBA kids.
It’s well known as a negative signal

Which startups are most likely to get an investment from top tier VCs?
I looked at ~60 attributes across 5000 startups and these were the 15 strongest.
#1 is being from a top tier fund. MBA is a negative signal
Full list of signals below:

simon retweeted
Turns out alchemical dreams were real. We converted sand into superintelligence. Who cares about gold… We transmuted the most ordinary into the most extraordinary.
Very mild takes lol, why is this even getting attention at all


simon retweeted

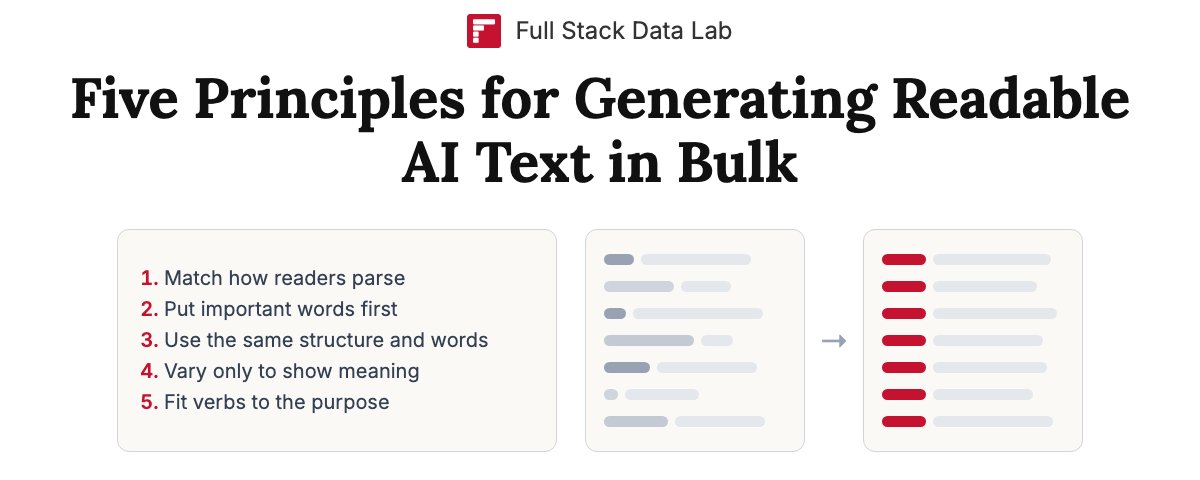
New blog post from our group! Do you create dashboards / HTML pages with lots of AI-generate texts, and get frustrated (like us) about how they're hard to read? Check out our tips here (and, send them to your coding agents)!!
simon retweeted

Anthropic filed their 318-page S-1 yesterday for the biggest IPO in history.
We parsed and synthesized every page in the S-1 and built this reader so that you can get the highlights: documentstories.com/anthropi…
Built with LlamaParse and @vercel

Who’s making PushBackBench

The thing with working with ai is that you can keep telling them to do something, tighten this writing, improve the style, make it better...
..and no matter how rounds you do, they will keep doing it until the result is absolute garbage.
they never push back that I could but it doesn't seem like a good idea. it's like the opposite of capable human who would just tell you no, you're being dumb, what you actually want is...
(i know I could prompt this this way, but the human bias/the tools kind of just expect you to command them what you want, not really trying to understand what the purpose is, and push back on when the task no longer makes sense)
super proud of our research team on this work.
we beat models that are much larger and trained with order-of-magnitude more data.
in the end, where we invested in the most is the quality of the training signal: curating high quality and diverse set of real and synthetic data, and careful reward design.
we were super close to naming the technical report "data is all you need" because in the end, that's all it matters.
checkout our blog: llamaindex.ai/blog/parse-ocr…
and technical report: llamaindex.ai/ocria/ocria-1-…

Today we’re releasing OCRia-1, a frontier VLM for document parsing that sets a new SOTA in accuracy, cost, and latency.
It not only sets a new high score on ParseBench (87.4), but also leads in three 3rd-party benchmarks: olmOCR-bench* (83.5 overall, 92.9 on tables!), PulseBench-Tab (84.1), and fr-bench-pdf2md (72.1).
OCRia-1 is really, really good at parsing complex tables: nested headers, merged cells, irregular grids, scanned tables, and more. It is also fantastic at parsing complex unlabeled charts (line, bar, pie, technical diagrams), and preserving complex formatting. Most real-world enterprise documents contain at least one of the these, whether it’s a big tax withholding table or a public economic report.
It is a 4B model and outperforms all other models within a similar parameter class: LightOnOCR-3, Chandra-OCR 2, Mistral OCR 4.1, and more. It is also extremely fast.
All credit goes to our research team, who spent countless hours on curating a diverse dataset, tuning our training pipeline, and squeezing every last drop out of model optimization so that it can process billions of pages at scale.
OCRia-1 as a base is powering all of our modes within LlamaParse (cost-effective, agentic, agentic plus), so you can access its capabilities today!
If you’re processing millions/billions of documents at scale, we’re offering enterprises that book a demo up to $3k in credits for a guided evaluation.**
*olmOCR-bench scores are adjusted based on unifying rendering at 1,288px for all models
**enterprise POC credits apply to eligible organizations that book a demo
simon retweeted

my first launch at @llama_index !! 🦙
OCRia-1 is named after a cria, a baby llama. they’re walking within about an hour of being born, usually somewhere high and cold and not very forgiving
felt right for a model built for the worst documents. i'm so excited for this to be out into the world and for people to see truly how insane this model is :) ocria-1 is the most accurate in the game ! 💥
Today we’re releasing OCRia-1, a frontier VLM for document parsing that sets a new SOTA in accuracy, cost, and latency.
It not only sets a new high score on ParseBench (87.4), but also leads in three 3rd-party benchmarks: olmOCR-bench* (83.5 overall, 92.9 on tables!), PulseBench-Tab (84.1), and fr-bench-pdf2md (72.1).
OCRia-1 is really, really good at parsing complex tables: nested headers, merged cells, irregular grids, scanned tables, and more. It is also fantastic at parsing complex unlabeled charts (line, bar, pie, technical diagrams), and preserving complex formatting. Most real-world enterprise documents contain at least one of the these, whether it’s a big tax withholding table or a public economic report.
It is a 4B model and outperforms all other models within a similar parameter class: LightOnOCR-3, Chandra-OCR 2, Mistral OCR 4.1, and more. It is also extremely fast.
All credit goes to our research team, who spent countless hours on curating a diverse dataset, tuning our training pipeline, and squeezing every last drop out of model optimization so that it can process billions of pages at scale.
OCRia-1 as a base is powering all of our modes within LlamaParse (cost-effective, agentic, agentic plus), so you can access its capabilities today!
If you’re processing millions/billions of documents at scale, we’re offering enterprises that book a demo up to $3k in credits for a guided evaluation.**
*olmOCR-bench scores are adjusted based on unifying rendering at 1,288px for all models
**enterprise POC credits apply to eligible organizations that book a demo
simon retweeted
Today we’re releasing OCRia-1, a frontier VLM for document parsing that sets a new SOTA in accuracy, cost, and latency.
It not only sets a new high score on ParseBench (87.4), but also leads in three 3rd-party benchmarks: olmOCR-bench* (83.5 overall, 92.9 on tables!), PulseBench-Tab (84.1), and fr-bench-pdf2md (72.1).
OCRia-1 is really, really good at parsing complex tables: nested headers, merged cells, irregular grids, scanned tables, and more. It is also fantastic at parsing complex unlabeled charts (line, bar, pie, technical diagrams), and preserving complex formatting. Most real-world enterprise documents contain at least one of the these, whether it’s a big tax withholding table or a public economic report.
It is a 4B model and outperforms all other models within a similar parameter class: LightOnOCR-3, Chandra-OCR 2, Mistral OCR 4.1, and more. It is also extremely fast.
All credit goes to our research team, who spent countless hours on curating a diverse dataset, tuning our training pipeline, and squeezing every last drop out of model optimization so that it can process billions of pages at scale.
OCRia-1 as a base is powering all of our modes within LlamaParse (cost-effective, agentic, agentic plus), so you can access its capabilities today!
If you’re processing millions/billions of documents at scale, we’re offering enterprises that book a demo up to $3k in credits for a guided evaluation.**
*olmOCR-bench scores are adjusted based on unifying rendering at 1,288px for all models
**enterprise POC credits apply to eligible organizations that book a demo
it's a good benchmark sir
Congrats to @nvidia for creating the best open-weight model on document parsing so far.
Nemotron 3.5 Parse takes the #1 spot on ParseBench, our comprehensive real-world benchmark for document understanding. The full list consists of 150+ frontier models, open-weight models, and specialized solutions.
It does this while remaining sub-1B parameters so it's also blazing fast ⚡️
Big thanks to @JensenHuang for the shoutout at GTC Berlin!
Nemotron release: huggingface.co/blog/nvidia/n…
ParseBench: parsebench.ai/

simon retweeted
A lot of professional work around documents can be arbitrarily challenging to automate.
It not only requires deep visual perception/OCR around complex entities (diagrams/charts), but also requires a reasoning trace that can reconcile disparate sources of oftentimes contradictory information.
Check out the example video below around a water loss audit. Solving this task not only requires reading the water loss diagram, but also understand the exact date and subsequent changes in the appendix.
We think hard document extraction tasks as a microcosm for professional work over PDFs. That's why we launched ExtractBenchPro - a benchmark that's challenging even for the latest frontier models (e.g. Astra/Opus).
Even as frontier models with max thinking models push the boundaries of accuracy, there is a massive opportunity to build specialized models that can push the frontiers of cost and latency.
For more info on ExtractBench Pro, check out our blog and the website! llamaindex.ai/blog/introduci…
Site: extractbenchpro.ai
Introducing ExtractBenchPro: the most challenging benchmark for real-world document extraction.
We see a massive long tail of document complexity in terms of use cases brought on from our customers, that are completely unsolved from a price-performance standpoint. These include trial balances, well logs, canvass binders, site plan reviews, duty reconciliations, loss runs, and more.
Most existing extraction benchmarks are saturated by the frontier models (our cheapest modes now score 93%+ on ExtractBench). So there is enormous economic value in building a complex extraction benchmark that reflects this long-tail of knowledge work.
We spent a long time curating the most complex elements that we saw from real world extraction use cases:
✅ Document conventions: containing legends or rules where the rest of the document should be interpreted
✅ Density of internal jargon: specific definitions that must be cross-referenced within a doc
✅ Aggregation and reasoning: beyond returning exact values on a page, infer values derived from aggregating multiple sources of information
✅ Drawn relations: complex diagrams like procedures and circuits
✅ Charts inside documents: read precise points within a chart
✅ Long chart sheets: some data series like well logs cram all this data into an extremely long page
Within the industries where document extraction is relevant, even small mistakes can have enormous negative impacts. Therefore our headline evaluation metric is based on perfect documents: the proportion of docs with perfect (100%) value f1 score.
(Besides this we also measure value f1 and grounded f1)
It’s an extremely hard task for even the latest frontier models to solve, topping out at ~58% or so in Value F1 score for Codex with Astra - which is quite good but extremely expensive (almost $1 per page!) Our LlamaParse agentic/agentic plus modes are 20-40% and cover the left side of the Pareto frontier, at price ranges that are feasible for full production use.
ExtractBenchPro is available today as a website/technical blog, and also on Github and HuggingFace. Check it out!
Blog: llamaindex.ai/blog/introduci…
Website: extractbenchpro.ai/
Hugging Face: huggingface.co/datasets/llam…
Github (is ExtractBench): github.com/run-llama/Extract…

simon retweeted

Introducing SKY-001, the first Engineering World Model.
On CAD and BIM tasks, it beats GPT-6 Astra and every frontier model we tested:
-> 51-125x faster
- > 150-210x cheaper
-> Higher IOU than all frontier models
SKY-001 lets you dream a physical object before you build it.
18 months of work. Built by the team out of Maluuba's deep learning lab (acq. by @MSRResearch).
The first ‘AI General Engineer’ will be the backbone for Autonomous Manufacturing.