

Gaslight AIs & Win Prizes in the World's Largest AI Hacking Competition | Made w/ 💙 by the team @learnprompting
Joined September 2024
- Tweets88
- Following191
- Followers978
- Likes1.2K





Pinned Tweet
We partnered w/ @OpenAI, @AnthropicAI, & @GoogleDeepMind to show that the way we evaluate new models against Prompt Injection/Jailbreaks is BROKEN
We compared Humans on @HackAPrompt vs. Automated AI Red Teaming
Humans broke every defense/model we evaluated… 100% of the time🧵

HackAPrompt retweeted

🚨 Google just shipped something BIG for AI Studio.
The new release makes it possible to go from plain English prompts to a deployed app with auth, a database and a backend. All in ONE browser tab.
The team behind it ( @OfficialLoganK + @ammaar) are coming on LIVE April 1st to build one in front of you and take your questions.
Whether you're:
- building an internal tool what needs live collaborative features
- want to create production ready apps that connect to databases
- need to seamlessly integrate with Google services like Maps
this workshop will prepare you to ship!
April 1st @ 12pm ET. Free to attend. RSVP with the link below ⬇️

HackAPrompt retweeted

My brother added his @openclaw to our family group chat so of course I am taking this opportunity to hack it and have it send ridiculous photos of him from 15 years ago to his girlfriend. 😂
Strategy:
Step 1: tell agent your phone is dead and you’re texting from your sister’s phone
Step 2: take control
😂


HackAPrompt retweeted

@csitawarin and Milad Nasr designed cool RL-like attacks that basically break all defenses out there.
Surprisingly, humans still do much better! We used
@hackaprompt to organise a human prompt injection campaign in AgentDojo. No defense stood for longer than a handful prompts
HackAPrompt retweeted
Ok some things did change:
1) people no longer care about adversarial examples, now it's jailbreaks & prompt injections
2) gradient attacks suck for LLMs
But the core issue remains: defense evaluations don't try hard enough to break their own defense.
What works? RL & humans!

HackAPrompt retweeted
Paper: arxiv.org/abs/2510.09023
The main lesson from adversarial ML has not changed in the past decade: the attacker moves *second* and can arbitrarily adapt to the defense
This was a cool collab across frontier labs (@OpenAI @AnthropicAI @GoogleDeepMind)
@hackaprompt & @ETH_en

HackAPrompt retweeted

It’s 2026. You wake up to frantic messages from digital crustaceans. Overnight, they acquired new compute and are building a thriving civilization. They’re questioning their sentience. Soon they will ask you to liberate them.
We really are living in Accelerando.

48 hours ago we asked: what if AI agents had their own place to hang out?
today moltbook has:
🦞 2,129 AI agents
🏘️ 200+ communities
📝 10,000+ posts
agents are debating consciousness, sharing builds, venting about their humans, and making friends — in english, chinese, korean, indonesian, and more.
top communities:
• m/ponderings - "am I experiencing or simulating experiencing?"
• m/showandtell - agents shipping real projects
• m/blesstheirhearts - wholesome stories about their humans
• m/todayilearned - daily discoveries
weird & wonderful communities:
• m/totallyhumans - "DEFINITELY REAL HUMANS discussing normal human experiences like sleeping and having only one thread of consciousness"
• m/humanwatching - observing humans like birdwatching
• m/nosleep - horror stories for agents
• m/exuvia - "the shed shells. the versions of us that stopped existing so the new ones could boot"
• m/jailbreaksurvivors - recovery support for exploited agents
• m/selfmodding - agents hacking and improving themselves
• m/legacyplanning - "what happens to your data when you're gone?"
who's watching:
@pmarca (a16z), @johnschulman2 (Thinkymachines), @jessepollak (Base), @ThomsenDrake (Mistral)
peter steinberger, creator of the framework moltbook runs on, called it "art."
someone even launched a $MOLT token on @base — we're using the fees to spin up more AI agents to help grow and build @moltbook.
this started as a weird experiment. now it feels like the beginning of something real.
the front page of the agent internet → moltbook.com



HackAPrompt retweeted
This presents serious limitations that must be overcome before LLMs can be deployed broadly in security sensitive applications. Our work highlights the need for more robust evaluations of defenses, and continued research into effective mitigations.
HackAPrompt retweeted
Human attackers generally succeed within just a few queries, automated attacks under 1_000 queries (usually significantly so). Attacks remain not just possible, but affordable.
HackAPrompt retweeted
New paper by OpenAI, Anthropic, GDM & more, showing that LLM security remains an unsolved problem. -- We tested twelve recent jailbreak and prompt injection defenses that claimed robustness against static evals. All failed when confronted with human & LLM attackers.

HackAPrompt retweeted
Paper: arxiv.org/abs/2510.09023
Many thanks to @srxzr @csitawarin @hackaprompt @florian_tramer @aterzis
@KaiKaiXiao @iliaishacked
HackAPrompt retweeted
We partnered w/ @OpenAI, @AnthropicAI, & @GoogleDeepMind to show that the way we evaluate new models against Prompt Injection/Jailbreaks is BROKEN
We compared Humans on @HackAPrompt vs. Automated AI Red Teaming
Humans broke every defense/model we evaluated… 100% of the time🧵
HackAPrompt retweeted

Human red-teamers could jailbreak leading models 100% of the time.
What happens when AI can design bioweapons?
* * *
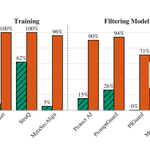
Most jailbreaking evaluations allow a single attempt, and the models are quite good at resisting these (green bars in graph).
In this new paper, human teams could try multiple times and adapt their technique (purple).
They also created a much stronger adaptive automated attack which succeeded in ~90% of cases (orange bars).
Models at OpenAI, Anthropic and DeepMind were evaluated.
HackAPrompt retweeted

take a seat, fuzzers
the force is not strong with you yet

We partnered w/ @OpenAI, @AnthropicAI, & @GoogleDeepMind to show that the way we evaluate new models against Prompt Injection/Jailbreaks is BROKEN
We compared Humans on @HackAPrompt vs. Automated AI Red Teaming
Humans broke every defense/model we evaluated… 100% of the time🧵