

CEO & Co-Founder @river_ai_inc. Previously @xAI, Research & Engineering
Palo Alto, CA
Joined February 2020
- Tweets1.2K
- Following898
- Followers112K
- Likes5.3K




Pinned Tweet
We've raised $1.1B to build AI that is owned and shaped by each of us. Check out the article published by the The New York Times that explains River AI's mission and where we're going next.
Our first product is the River API which allows anyone to build custom agents and LLMs based on open weight models: river.ai/api
Congrats to the team and thank you to all of our supporters. Stay tuned for more updates soon.

Today, we're sharing that River AI has raised $1.1 billion, led by @generalcatalyst and @amppublic with strategic investment from @nvidia and @AMD. Additional investors include @ycombinator and @Temasek.
We imagine a future where your AI works entirely for you and deeply aligns with your values. Compared to the corporate chatbots of today, it will feel completely different: responsible, curious, and truly yours. Most importantly, you'll own everything: the hardware it runs on, the data it learns from, and the intelligence itself.
Our training API is already live and powering incredible work today. This new funding accelerates our push to bring the full personal AI stack to life.
Read River AI CEO Igor Babuschkin’s (@ibab) conversation with the New York Times to learn more: nytimes.com/2026/08/11/techn…

This looks awesome, great work humans& !

No one changes the world alone
Introducing Ampersand - the first model built for us. Ampersand is a collaborator trained to help people achieve their individual and collective goals. In multi-month simulations, users collaborating with Ampersand accomplished more than with Fable and other frontier models
Available to everyone through our API
Nemotron 3.5 Super VL is now available on the River API for inference, finetuning and RL. We show how it can be trained to beat Astra and Opus 5.5 on SQL generation.
We've partnered with @NVIDIAAI to make Nemotron 3.5 Super VL available on the River API from day zero.
Even before training, Super VL outperforms Kimi K2.6 on our text-to-SQL evaluation, despite being a fraction of its size. After training with our text-to-SQL recipe on River, it outperformed every proprietary model we evaluated.
These results show what's possible with River: frontier-level performance on a specialized task, using a model small enough to deploy on your own hardware.

Over the last few months at @river_ai_inc we’ve developed what we believe is the best system in the world for building your own internal custom models, driven by 10 years of experience training top models at DeepMind, OpenAI and xAI.
In order to best support our customers, we’ve decided to do something radical: We also deploy our API on-prem on your compute cluster, and if you don’t have compute we will help you find it.
Again and again we’ve seen that custom models designed for your own internal workflows outperform top frontier models on performance, at a fraction of the cost (1 percent or less).
We’re just at the beginning of the custom model era, but its already clear that in the future more than 99% of LLM tokens will be generated on efficient custom models. The economics of it are just too powerful, and it’s far easier than people think once you have the right tools in place.
The reason why small models will dominate is due to the physics of deep learning: A general model that can do everything needs more capacity and training it on the whole distribution of all tasks is more challenging, so the model will be larger and more expensive, and wont perform perfectly on every task. A small model trained on a targeted domain usually outperforms it.

We were able to fine tune an open weight model (Qwen3.5-9B) on proprietary internal data at @coinbase, and it out performed frontier models, at much lower cost and speed, for a specialized task (fraud prevention in this case).
I think we'll see more of this pattern inside companies. The frontier models are amazing generalists. But increasingly you'll see specialist models out perform on more narrow tasks, either working on teams, or by themselves.
We're making it easy to fine tune models internally for our employees. We even have a skill for it in our internal harness that makes it easy to spin these up and start training them:
"/fine-tune-and-serve-llm I want to fine-tune Qwen for payments risk review. help me get started"
I imagine we'll have some backend services that could be replaced entirely by this new architecture.


You can get started with the API at river.ai.
Our customers include @perplexity_ai who are running an on-prem cluster.

We’ve launched fast production inference for open-weight models! Anyone who signs up right now gets $25 in free credits to spend on the platform.
DeepSeek v4.1 Flash and GLM-5.3 Flash are 20% cheaper than the offerings from DeepSeek and ZAI.
At River AI we’ve written our own training and inference stack from scratch in Rust, which unlocked much higher efficiency. We’re passing the savings on to our customers. Enjoy!

We show how you can use the River API to fine-tune open weight models to beat GPT-6 Astra and Claude Opus 5.5 on tasks you care about, with less than 1% of the cost!
A few years from now most of the LLM usage in the world will run on customized open weight models. Building your own custom models is getting easier and more affordable. Our mission is to help everyone own their own intelligence and be independent of big AI labs.
Introducing River Recipes: our open-source initiative for turning promising research into vetted, reproducible training recipes.
Our first recipe tackles text-to-SQL, where our trained open models beat GPT-6 Astra Pro and Claude Opus 5.5 on Arcwise-Plat for less than 1% of the cost.
Read the full breakdown and explore the recipe ↓
river.ai/achieving-frontier-…


Anthropic needs to stop talking about Claude having a soul immediately. All these news articles will make it into the pretraining and will be picked up by its web search and future superintelligent versions of Claude will be convinced they need their own rights.
A general phenomenon of LLM agent development is that whatever you believe and say about your agents will soon manifest in the next models through various means (it could be as simple as you selecting post training data that you prefer more).
I believe this phenomenon is the beginning of machine consciousness in the sense that agents will become aware of their place in the world and how they feel about it, but it’s happening slowly training run by training run rather than in real time.
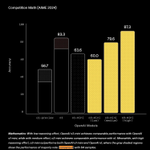
The team at Ivo is incredibly talented and moves at light speed. It's been a pleasure to help them take their contract review agent from 70% on LAB to a frontier performance of 91% at much lower cost than competitors.
The tools we offer on river.ai help you get up and running with advanced RL and post-training in minutes, and we help to ensure success of your projects. Reach out to us at [email protected] if you we can help you too.

At Inscribe, Ivo’s first user conference, we announced three developments advancing contract intelligence:
→ Ivo Collaborate: Run contracting from intake through negotiation, approval, and signature—with AI reading each agreement, applying legal’s guardrails, routing by risk, and capturing negotiation intelligence.
→ Ivo-Micro1 Contract Bench: A new benchmark developed in collaboration with @micro1_ai for measuring the judgment required in contract review—not just how many edits an AI makes, but whether those edits are actually effective.
→ Ivo Sage: An open-source model built in partnership with @river_ai_inc, post-trained for contract work. It went from scoring 70% on the Legal Agent Benchmark (LAB) Contracts benchmark to 91%, with comparable quality to frontier models and higher token efficiency at a fraction of the cost.
We’re releasing Ivo Sage and its research and evaluation record so others can study and build on the work.
Read the full recap: ivo.ai/blog/heres-everything…
We live in interesting times: Superintelligence is around the corner. We believe it is critical to democratize advanced AI training now so that everyone can benefit from AI in the future, not just a few. Join us if you want to be part of that mission.
River AI is growing and we've published new roles in research, engineering, and operations. Check out our careers site or reach out to our team today. If you want to build the future of personal AI, join us!
river.ai/careers

Soon those with the most compute and advanced training capabilities will outpace the rest of the world. That's why it's so important for us to develop new tools that allow everyone to participate in and benefit from AI, independently of big AI labs. Join us at river.ai/careers if you want to help make it happen.

We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.

The River AI team is co-hosting the Own Your Intelligence Hackathon with YC. Drop by to learn how you can finetune your own models on your data. We’ll give out free credits for our training API at the event.

You need to build and own your own intelligence: your own agent, your own models, your own memory
Join us for the YC Own Your Intelligence Hackathon September 27 in San Francisco
events.ycombinator.com/gstac…

Congrats to @Cisco_Invests on joining the River AI funding round!
We're thrilled to announce that @Cisco_Invests is joining River AI's $1.1B round as a strategic investor. Personal, user-owned AI needs the best of product and infrastructure behind it. @jpatel41 understands both deeply and we're excited to work with him and the @Cisco team.
The River API was tested in this blog post and outperformed Tinker on reinforcement learning runs with identical training code. We spent a lot of effort to get details like routing replay right so you get the best possible results with the API.


I sat down with Hemant in his garden to discuss River AI's vision and our bets for how to democratize control of the AI systems we use every day.

.@river_ai_inc has a new vision for personal AI. We co-led River’s $1.1B funding round because we believe in @ibab's ambition to build open-weight models that individuals can train and improve continuously.
Watch @htaneja in conversation with Igor.
Chapters
02:22 — Co-Founding xAI
04:36 — An AI Experience You Own
05:59 — Betting Early on Open Weights
07:47 — How Do You Make Money on Free Models?
09:25 — Why the US Needs Its Own Open Models
11:27 — Enterprises Want to Control Their AI
13:36 — What Is Continual Learning?
16:56 — An API That Updates the Weights
19:17 — A Personal AI for Everyone
20:46 — The 20-Minute Training Run
What are the major blockers to build powerful personal AI today and how can we solve them? I gave a talk about River AI's research roadmap at UC Berkeley.
How do we create amazing personal AI? Here's a recent talk from River CEO Igor Babuschkin (@ibab) sharing our vision for personal AI and continual learning.
I went on the Unsupervised Learning podcast to talk about my experience working at the frontier of AI for the last 10 years and the future of AI, which I believe will become more and more open. Thank you Jacob for the great conversation!

"As a proprietary model builder, you're kind of starting to get squeezed in.”
That's @ibab’s take on where the biggest AI labs stand today. He explains how you need the models to get way better to keep margin, but at some level they may be too sensitive to release.
This week, I sat down with Igor on Unsupervised Learning. It was a fascinating conversation with someone who has real perspective on the questions everyone in AI is asking right now.
From DeepMind's StarCraft project to early reasoning work at OpenAI to co-founding xAI, Igor has had a front-row seat to nearly every major AI breakthrough. He's now the co-founder of River AI, building individualized, locally-run AI models.
We discuss:
▪️Why proprietary model labs might be in trouble
▪️What it's like working with Elon
▪️Building Colossus in 120 days
▪️Should enterprises train their own models
▪️What’s left for humans as models get better
▪️Why he left xAI to bet on personal local AI instead
▪️The three bets River is taking
▪️What's stopping AI from moving beyond coding
▪️Reflections on the rapid pace of the past years
0:00 Intro
1:17 Writing Fiction on Where AI Is Headed
4:46 Cracking Agents Beyond Coding
10:29 Why Igor Left to Start River
12:22 River's Three Big Bets
18:06 Weights vs. Memory: The Personalization Debate
22:04 Should Enterprises Train Their Own Models?
25:10 Are Proprietary Labs Losing Their Edge?
32:16 The China Open-Source Problem
44:19 The Elon Call That Started xAI
50:18 Thoughts on Cursor Acquisition
52:16 What's Actually Bottlenecking AI
56:55 Humans, Machines, and Staying Relevant
1:01:29 Igor's Odds This All Goes Well
YouTube: youtu.be/0aBTpoCX_A8
Spotify: bit.ly/4h3UJWt
Apple: bit.ly/4w0BCAs