

Crafting Decision Superintelligence (DSI) 👾 I train models and eval | Prev @Wallet @AlibabaGroup | @hkust PhD Quit @Johnshopkins Alum | @0xUclub
Joined May 2022
- Tweets1.6K
- Following2K
- Followers1.9K
- Likes1.5K




One thing I learn from Moonshot AI dude @Bobby___Young few month earlier: rewrite every lines of code /w most advanced model every quarter. Polymarket did that as well.

At the end of August, I said our Polymarket DeFi CLOB couldn't be saved, and we were rewriting it from scratch in Rust 🦀
Today I'm excited to announce Nex, our new exchange built from the ground up.
We've been sprinting on it since August. A Nex instance has been running in shadow mode on production traffic for the last week, side by side with the current exchange. It mirrors every order the current exchange gets, so we can measure latency, stability under load, and validate matching correctness against live production flow.
The numbers below are internal exchange timings, not e2e (those are coming soon), but we wanted to show how big the difference is.
p99 current CLOB → Nex:
- Place order: 1.55s → 3.76ms (412x faster)
- Cancel orders: 627.92ms → 3.20ms (196x faster)
- Cancel market orders: 810.16ms → 5.14ms (158x faster)
- Cancel all*:
↳ Response (current CLOB) vs complete (Nex): 35.70ms → 3.14ms (11x faster)
↳ Full cancel all: ~636ms-2.04s → 3.14ms (~200-650x faster)
p95 current CLOB → Nex:
- Place order: 341.84ms → 1.59ms (215x faster)
- Cancel orders: 78.22ms → 1.58ms (50x faster)
- Cancel market orders: 84.89ms → 2.27ms (37x faster)
- Cancel all*:
↳ Response (current CLOB) vs complete (Nex): 6.20ms → 1.58ms (4x faster)
↳ Full cancel all: ~606ms-2.01s → 1.58ms (~380-1,270x faster)
*Cancel all: the current CLOB responds immediately and cancels in the background, so when you get the response, your orders aren't cancelled yet. Nex responds only after everything is actually cancelled. Full cancel all on the current CLOB depends on how many orders you have, but it usually adds another 600ms-2s.
We also rewrote our WebSockets in Rust. This is the feed you see the market through: book changes, price moves, your fills. Fall behind it, and you're trading on old prices, and your quotes get picked off.
- Write latency p99: 44.5-88.1ms → 0.099ms (~449-889x faster)
- Slow readers/sec: 48.7-75.6 → 0.01 (~4,870-7,560x fewer, basically 0)
Scale: The current CLOB in stable state can handle 10k commands/s with 15k bursts → Nex can handle 100k commands/s with 150k bursts. 10x more, and with a few optimisations we can get to 200k commands/s with 250k bursts; with more low-level core changes, we can get to 1M commands/s over the next year. Not needed yet, but the headroom is there.
Startup time: 5 mins → 15s (20x faster)
The old CLOB had many race conditions and wasn't deterministic. Nex is deterministic by design and removes the race conditions in the old CLOB.
We also skipped some easy wins for launch to get this out faster that could make p95 and p99 another 5x faster, and we'll start work on that in Q1 next year to keep pushing these numbers down.
We wanted to build this without any breaking changes for MMs or builders; Nex has no breaking changes to requests or responses, so we just need to swap out the binary on our side and it will go live.
We want everyone to be on this journey with us, with the ability to relay feedback and test it against the existing CLOB, so we've opened a Nex Sandbox. Fill out the form and test it yourself: docs.polymarket.com/nex
We'll run 4 weeks of shadow mode on production traffic to make sure everything is perfect, then if everything is good, we will go live mid-December. We can roll out WebSocket improvements without the full exchange, so we may do that sooner.
We've been rebuilding every system around the exchange for months, and we've seen huge benefits, but the exchange is the heart of Polymarket DeFi. Nex fixes most of the pain traders have had.
Really proud of the team on this one.
Make Polymarket fast, finally. It's coming.


3
235
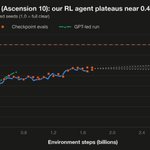
Running an auto-research loop to train a model that can beat Slay the Spire 2 on Ascension 10 (the hardest difficulty). Wish me and @yoshua_wang some luck!

1
3
262


Yishu🌴 retweeted

Couldn’t agree more. It strikes me that most AI adoption in finance has focused on automating or accelerating existing workflows, rather than questioning whether those workflows are optimal in the first place.
As an analyst, I understand the appeal of getting to an answer faster. But surely the more interesting question is whether AI can help us arrive at fundamentally better answers?
I’ve always been fascinated by the idea of an interconnected investment brain. Something akin to Obsidian, but purpose-built for investing, where companies, industries, themes, mental models, investment hypotheses and evidence exist within a continuously evolving knowledge graph.
I’ve actually started experimenting with a prototype of this concept, which I’m calling Labyrinth.
Imagine discovering something material about one business and being able to trace its implications across an entire network of companies, assumptions and investment theses. Rather than research existing in isolated notes, PDFs and spreadsheets, knowledge becomes interconnected, cumulative and increasingly useful.
Now combine that with probabilistic modelling.
Instead of a financial model producing a single target price based on point estimates, imagine one that represents a distribution of possible outcomes, understands the dependencies between assumptions and updates those probabilities as new evidence emerges.
The analyst’s role shifts from manually maintaining models and processing information towards challenging assumptions, evaluating evidence and exercising judgement.
I suspect Excel will eventually become less central to the investment process, replaced by something more dynamic, interconnected and probabilistic.
Perhaps the biggest opportunity for AI in investing isn’t helping us do the same work faster.
It’s fundamentally changing how we think, connect information and make decisions under uncertainty.


This is so bang on, a lot of investing involves far too much false precision, and it's because it simplifies it for human understanding...this is why I'm excited about AI's use in investing
when you think from first principles, it seems crazy to be putting a precise number on something we know is uncertain...
analysts assign target prices, estimate “fair value” and forecast cash flows five years into the future. The model gives us an answer like $47.83.
but take a step back and think about what went into that number
we don’t know exactly how quickly revenue will grow. we don’t know what margins will be, how much the company will need to reinvest, or what return investors will demand in five years. Every assumption has a range of possible outcomes.
We choose one number for each, run the calculation, and end up with an answer that looks way more certain than anything we put into it.
We all know that investing is about gaining confidence that the probabilistic range of outcomes has a favourable skew
This is why I’m so excited about compute changing how we do this work.
Modelling is part of the problem, it's unfathomable for each cell in excel to have a probabilistic range of outcomes and for you to update those probabilities constantly as information emerges
But AI and newly written software will genuinely make this possible, not to mention the most advanced systems being able to ingest information and update those weights
of course, judgement still exists about the assumptions and their likelihood but I'm really excited to see how this evolves
All you need is context maximizing. Let it cook.
Our agent really shines with our in-house research connector—tapping into tons of podcasts, substack posts, expert interviews, and sell-side research.

Substack might be the best source of alpha.
Claude has found over 12,000 posts so far and automated 149 of them, attempting to replicate the authors' results.
It's pretty crazy.
The less efficient the market and the more heuristic-driven the instrument, the higher the potential Sharpe ratio.
But the harder it becomes to find a way to actually trade it.

1
2
307
Wishing you all the best in your next chapter, Haider! I’ve felt that you brought something truly unique to the company, with an incredible sense of taste in marketing and brand, a vibe that felt different from the rest.

After almost seven years at @OKX, I am stepping back from my role to take a meaningful break, focus on my family and personal priorities, and make space for what comes next.
It has been an incredible privilege to help build the @OKX brand and see its growth. I am deeply grateful to Star Xu @star_okx for his trust, partnership, and the opportunities he created for all of us.
And thank you to every OKX employee I have had the privilege to work alongside. I am proud of what we built together and excited to see the company continue to grow.
This is not goodbye. It is simply the next chapter.

3
656

Welcome to the decision intelligence family!

You already gave the LLM the answer. So why is it writing it out from scratch?
Introducing a new AI model architecture: Constrained Decoding Models (CDMs)
LLMs were built to write. Most production workloads just need an answer: fast, consistent, and affordable.
CDMs are purpose-built for 1 task each. They read your input once and skip the token-by-token generative loop that makes LLMs slow and expensive.
Not just a decision model, but a family of 3 CDMs live today:
• Classify: define your labels and get back a calibrated probability + reason for each. Used for routing, tagging, and intent detection.
• Extract: describe the entities in natural language and get back well-formed JSON with confidence scores + citations. Used for web scraping, document processing, and PII redaction.
• Summarize: pass in long text, images, or PDFs and get back a consistent summary under 1,000 tokens. Used for context compaction, metadata generation, and transcript digests.
Built for production:
• 1M tokens of multimodal (text + image) input, 31x larger than Jev
• 77.2% on DecisionBench vs Jev's 72%
• 200x faster, 467x cheaper than frontier LLM APIs
• $0.05/M input tokens. Output is free (yes, even for summarize)
Live on your favorite platforms today:
@OpenRouter @vercel_dev @LiteLLM @LangChain @TrustedRouter @itsArthurAI @useRouterPlus
Get 50M input tokens for free (for the first 50 hours) at link below 👀
1
5
439
Yishu🌴 retweeted

You already gave the LLM the answer. So why is it writing it out from scratch?
Introducing a new AI model architecture: Constrained Decoding Models (CDMs)
LLMs were built to write. Most production workloads just need an answer: fast, consistent, and affordable.
CDMs are purpose-built for 1 task each. They read your input once and skip the token-by-token generative loop that makes LLMs slow and expensive.
Not just a decision model, but a family of 3 CDMs live today:
• Classify: define your labels and get back a calibrated probability + reason for each. Used for routing, tagging, and intent detection.
• Extract: describe the entities in natural language and get back well-formed JSON with confidence scores + citations. Used for web scraping, document processing, and PII redaction.
• Summarize: pass in long text, images, or PDFs and get back a consistent summary under 1,000 tokens. Used for context compaction, metadata generation, and transcript digests.
Built for production:
• 1M tokens of multimodal (text + image) input, 31x larger than Jev
• 77.2% on DecisionBench vs Jev's 72%
• 200x faster, 467x cheaper than frontier LLM APIs
• $0.05/M input tokens. Output is free (yes, even for summarize)
Live on your favorite platforms today:
@OpenRouter @vercel_dev @LiteLLM @LangChain @TrustedRouter @itsArthurAI @useRouterPlus
Get 50M input tokens for free (for the first 50 hours) at link below 👀
🤖 Made with AI
Yishu🌴 retweeted

The economics of a Neolab.
A neolab is loosely defined as a startup of AI researchers who raises a lot of money pre-production to be able to finance GPU compute to take on a large AI problem.
To buy 1000 GB300s or ~14 NVL72 racks will set you back $125-150M for 3yrs with 15-30% upfront. That’s about ~2-2.5MW.
Thats about enough to do 10^25 flops a quarter and get to a GPT-4 level model which is 1-2 OOMs off frontier for pretraining.
If you post-train on a great open source model, you have a better chance of getting to frontier. The risks are a) you need to spend millions on RL environments too and b) being lapped by another model release while being tied to a base model.
For this to payback, you need to give your customers a better and ideally cheaper inference service than a base model and serve them for long enough to recoup your large investment. Even at 50% margin on inference, to recoup $10M in training means serving ~10T tokens (!) if you price like Fable / Astra given a standard cache read / input / output split ($2/M blended). And you have to justify being better than a release like Opus 5.5 which is even cheaper. Often, you end up charging your customers a huge premium in terms of platform fees and compute fees on top of pure inference.
Meanwhile, every hour you’re not utilizing your GPUs you are burning money so you typically resell this compute back to a broker or run inference for open models / resell spot instances. At below a ~60% utilization on spot, you will still lose money.
Add to that insane cost of talent.
So what can you do with the compute?
- Not play the model game at all.
- Play an entirely different model game (Jev, World Labs) that if big labs played, would either a) cannibalize their business or b) be incrementally not significant revenue c) would cause too much distraction from the main main thing
- Acquire a proprietary data set (Peridodic Labs) in enough volume in a domain of usefulness to eclipse frontier quality. Often happens in robotics, biology, chemistry.
If you do overcome the challenge of building a model that is useful and well priced beyond big labs models, given the huge price of compute, you still need to play in an area where the revenue / compute ratio is signficant and market demand is large enough to payback your compute spend.
It is a difficult game.
That’s bargaining agent, I was doing evaluations and post-training on these matters for @AlibabaGroup last summer.

How important is AI to Meta? Here’s one easy tell:
One of the launch features of the Muse app was auto-negotiating for stuff on Facebook Marketplace.
The poor product manager who owns Marketplace knows that millions of bots lowballing sellers will eventually kill the product.
But this was escalated to Zuck by the Muse team and he said: “OK, we’ll poison Marketplace…but just a little.”
1
360
Yishu🌴 retweeted

my companies have accumulated $1.4B in market cap over the years.
i've raised in every kind of market there is.
in 2017 my investors made 30x in a year.
earlier in my career i built a unicorn that didn't survive.
i've had pitches that wouldn't land, products that wouldn't sell, and rounds that closed in under 10 days.
every situation is different. a few things hold.
1. raising is sales. you need 10, 20, 50, 100 calls to hone the pitch. there is no version where you nail it on call three.
2. raising is sales. every pitch gets cut for the person across the table. ai is very good at this now, so there's no excuse for a generic one.
3. raising is interviewing for a job. you'll be better in round 30 than round 1. order your meetings accordingly.
4. you need a deck. but with ai now manage it as a live artifact, not a pdf. living, breathing, never stale.
5. data rooms are dynamic now too. every question any investor asks goes into the deck and the dd room in real time, for everyone.
6. ship fast and furious always, but especially during a raise.
7. traction. of any and every sort. momentum drives the raise.
8. raise on your schedule, not theirs. everyone appreciates a well organized process.
My GPT6-astra just pass Slay the Spire 2 on its hardest difficulty, A10 and NoSL.
Honestly, this results surprises me greatly. Fable and GPT5.6 can’t pass act 2 in previous run.
I’m building environment and bench around in-game decision-making. If you’re interested, DM me!
1
304

Judgement and decision making are not exclusive to human beings 👨💻

1987: AI can't win at chess—planning is uniquely human
1997: AI can't win at Go—intuition is uniquely human
2016: AI can't win at poker—bluffing is uniquely human
2023: AI can't get IMO gold—reasoning is uniquely human
2026: AI can't make wise decisions—judgment is uniquely human


1
234
glad to see ur guys sharing the training recipe for AI forecasting

We've shared research on fine-tuning forecasters, now you can try it for yourself: a cookbook recipe for training a model to predict event probabilities given reference information.
Start with the provided dataset from @ProphetArena, then try your own.
github.com/thinking-machines…
183
Quite a coincidence — I was actually in the room.
Right after the host asked the question @GenAI_is_real mentioned here, I got to ask @cz_binance another one:
“How do early-stage founders attract the best people? And when the founders are all engineers, how do you attract top talent from completely different fields like marketing or design?”
His answer was: you need to sell the vision and have founder charisma to attract them,
Early on, people join because they believe in the future you’re describing and in the founders themselves. For younger talent, referrals from friends matter a lot too.
And having a one-dimensional founding team isn’t necessarily a problem at the beginning — just start building. He mention the example that google was founded by engineers too. Eric Schmidt joined much later.

I came across a conversation CZ (Changpeng Zhao, founder of Binance) had at a book club event in Hong Kong today, and found it deeply inspiring:
"A lot of students at the event wanted to join Binance, and his answer was just two words: be proactive. Binance is fully remote — you can slack off, and losing a few hours a day is easy. But if you're not proactive enough, two months down the line you may have nothing to show for it."
"I touch a lot of things, jumping from one to the next, and some things I forget right after I've mentioned them. I generally don't track people. If someone doesn't proactively come to me with updates, I'll simply forget. But maybe two months later it comes back to me and I ask — and if the answer is 'we worked on it for a week and then it went nowhere,' I'll fire that person."
"I never follow up. I need them to push updates to me."
He summed it all up in one verdict: "If you proactively go after something, you will succeed. If you only act when your boss comes around to check on results, you won't."
The fun part: the host drove the point home on the spot — everyone sitting in that room had been selected only after personally emailing the organizers again and again and submitting questions. Proactivity itself was the ticket in.
CZ further broke proactivity down into two deeper underlying principles:
80% is showing up. In life, 80% of success comes from showing up. You have to be in the game — if you don't participate, there's no opportunity at all.
What you don't do matters more than what you do. Most people today never think about what not to do. Someone sends them a message, and they feel obliged to reply... So many of these things could be cut entirely, yet people never cut them.
I read CZ's book Freedom of Money a while back and was deeply inspired by it. In my view, growing an open-source community demands the same enormous proactivity: proactively initiating projects, proactively seeking collaboration, and owning the final outcome. Proactivity is a tremendous driving force.
And at the same time, once you've proactively taken on the responsibility, the corresponding authority naturally follows — after all, matching authority with responsibility is the basic principle that keeps our community thriving over the long run.
Someone who can drive a project end-to-end, cleanly from start to finish — to me, that's the strongest calibration there is. Even without any AI infra experience, anyone with that kind of proactivity is a friend absolutely worth collaborating with.
3
398

Yishu🌴 retweeted

2/ Train yourself to go from 10 to 40 to 100 hours of focused work a week. I did this for months building an automated trading system from scratch. 5am-10pm 7days/week
99% of people need #WorkLifeBalance or whatever, and that's great. But I'm talking to the people on a mission.