
Stanford CS PhD | Berkeley EECS
Palo Alto, CA
Joined June 2025
- Tweets177
- Following1.2K
- Followers6.5K
- Likes692



Pinned Tweet
Introducing Contrastive Language Model (CLM): an ultra-fast System One Model trained with a contrastive learning objective that connects states and actions.
CLM-8B is pre-trained on internet-scale data and delivers up to 9× faster inference than Jev ⚡ while achieving comparable performance across computer-use, gaming, and tool-calling tasks.
With lightweight fine-tuning, CLM-8B sets a new SOTA on challenging agentic coding benchmarks, such as DeepSWE (81.6%) and Terminal-Bench 2.1 (87.6%). In contrast, Jev fails to serve as an effective verifier for these long-horizon tasks.
We also build an efficient training and serving infra for CLMs by disaggregating states and actions, allowing their embeddings to be cached and reused independently. This substantially reduces inference latency in settings where the state evolves continuously while the action set remains fixed.
Finally, we establish scaling laws for CLMs and show that the test contrastive loss decreases predictably as a power law in training compute, model size, and dataset size.
📄 Blog: contrastive-lm.notion.site
💻 Code: github.com/Contrastive-LM/CL…
🗣️ Discord: discord.gg/5dAQEDJBs
🤗 Data & Models: huggingface.co/Contrastive-L…
More details on CLM’s architecture, data recipe, and scaling laws in the thread below 🧵
Jacky Kwok retweeted

Introducing ✨Token-Gated Language Models✨ for up to 11x faster prefill by learning to skim context, conditionally forwarding only tokens that matter.
Akin to the shift from dense models to MoEs, the next frontier of efficient LLMs is conditional computation over a new scaling axis: context tokens🧵👇

Jacky Kwok retweeted

Introducing Slingshots // FOUR: 14 projects across eight top institutions. Self-improving agent systems and harnesses, maximally-open models and training data, applications for research and decision-making – plus kernels and more. Say hello to the batch 🧵
Contrastive Language Model is part of Slingshots // FOUR! Huge thanks to @LaudeInstitute for supporting our work 🙌
Excited to keep building and growing the open-source community around CLM :)

CLMs (Contrastive Language Models) // @jackyk02, @JonSaadFalcon, @drmapavone, @HazyResearch, @Azaliamirh (@Stanford) — A system one model for fast and generalizable decision-making.

Jacky Kwok retweeted

Introducing RSI-top: a framework that helps autonomous research agents explore new directions when progress stalls 🧭
On Anthropic’s kernel optimization task, RSI-top outperforms OpenEvolve and ShinkaEvolve by up to 15%. On MLE-bench Lite, it achieves a 77.3% medal rate, outperforming the strongest baseline by 11.4 percentage points.
RSI-top tackles this problem from two angles: context management and diversity control 🔍
A compact metric dashboard helps agents selectively retrieve useful past trajectories, while three diversity control mechanisms encourage fresh perspectives, new ideas, and different starting points when progress stalls.
More details in the thread below 🧵
Excited to see LLM-as-a-Verifier being adopted in @NVIDIA latest model release 🚀
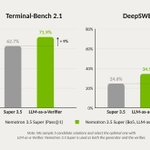
Scaling self-verification with Nemotron 3.5 Super significantly improves accuracy across agentic benchmarks:
Terminal-Bench 2.1: 63% → 72% (+9%)
DeepSWE: 25% → 35% (+10%)
Check out the Nemotron 3.5 model card for more details:
research.nvidia.com/labs/nem…
Huge thanks to @NVIDIAAI for providing the resources and collaborating with us on this work!


Jacky Kwok retweeted

🚀 Introducing Next-Concept Modeling (NCM): our new paradigm for fast, parallel, coarse-to-fine text generation.
Compared to strong diffusion language models (DLMs) at similar parameter size, NCM achieves:
⚡ Up to 31× faster generation on downstream tasks like summarization and machine translation with comparable or better quality.
🏎️ 10–21× faster unconditional generation across TinyStories, LM1B, and OpenWebText, with comparable or better generative perplexity and using 3–5× fewer training tokens.
🧩 Better performance on reasoning tasks like Sudoku, outperforming both AR and diffusion baselines with fewer sampling steps.
With @ishanskhare, @IddahMlauzi, @ekellbuch, @simran_s_arora, @Azaliamirh, and @HazyResearch.
More details in the thread 🧵👇
Can a weaker model verify outputs from a stronger model?
We find that using DeepSeek V4.1 Flash to verify Opus 5.5 trajectories achieves SOTA on Terminal-Bench 4 (69.2%) 👑
Try it out with LLM-as-a-Verifier V3: github.com/llm-as-a-verifier…
If you're at @COLM_conf, come check out my oral presentations on LLM-as-a-Verifier tomorrow!
AI Measurement Science Workshop
📍 Franciscan A&B / Ballroom level
🕔 9:45 AM
Lifelong Agent Workshop
📍 Continental Ballroom 6
🕔 2:00 PM
More on verification scaling for LLMs in my previous post 👇


How can we extract richer signals from AI Feedback?
Introducing LLM-as-a-Verifier✨— a simple verification scaling framework that achieves SOTA on agentic benchmarks 🚀
The key idea:
- Use fine-grained scoring granularity (e.g., 1-20 instead of the standard 1-5 scale)
- Take the expectation over the full logprob distribution of score tokens
- Scale repeated evaluation and criteria decomposition
You can use these fine-grained signals for more effective test-time scaling, RL, and agent monitoring! It achieves SOTA across Terminal-Bench V2, SWE-Bench Verified, RoboRewardBench, and MedAgentBench 👑
Advised by @Azaliamirh @istoica05 @drmapavone @chelseabfinn
🧵👇

Jacky Kwok retweeted

We introduce DeLM, a decentralized approach to multi-agent systems.
DeLM improves accuracy by up to 17.5 percent points and runs up to 2.49× faster than the Codex and Claude Code harnesses on long-horizon tasks from Terminal-Bench 4.0, DeepSWE v1.1, and ProgramBench.
How it works: the main agent is replaced by a shared context and a task queue. Agents claim tasks asynchronously and build on or correct each other’s progress, and every agent’s status is visible to the others.
You can run DeLM’s collaborating agents directly in Codex and Claude Code:
github.com/Decentralized-LM/…
Give it a try!
Great work led by @Mao_Yuzhen!


Agents are becoming increasingly powerful, but does adding more agents actually help us solve tasks more efficiently? In many everyday settings, the answer seems to be: “Hmm… not really.”
Reintroducing DeLM, much faster, more capable multi-agent systems through decentralized coordination. ⚡
Compared with our first version in early June, the updated paper expands the evaluation beyond SWE-bench to include Terminal-Bench 4.0, DeepSWE v1.1, and ProgramBench!
A quick recap: DeLM enables parallel agents to coordinate through a shared context and a task queue, with no main agent in the loop. Agents share discoveries, reuse intermediate results, and correct one another as they work, reducing both idle time and redundant work.
Evaluated on 10 long-horizon tasks each from Terminal-Bench 4.0 and DeepSWE v1.1, with GPT-6-Astra and Claude Opus 5.5, DeLM improves accuracy by up to 17.5 percentage points over the strongest baseline, while running up to 2.49× faster than the harness it builds on. On ProgramBench, where agents rebuild entire programs from scratch, DeLM beats Claude Code's test pass rate by up to 19.9 points within the same 120-minute budget.
We’re open-sourcing our code and all DeLM trajectories so you can explore how this collaboration unfolds!
🌐 Project & code: yuzhenmao.github.io/DeLM/
📄 Paper: arxiv.org/abs/2606.10662
🤗 Trajectories: huggingface.co/datasets/yuzh…
More on the coordination design in the thread below 🧵
Jacky Kwok retweeted
Agents are becoming increasingly powerful, but does adding more agents actually help us solve tasks more efficiently? In many everyday settings, the answer seems to be: “Hmm… not really.”
Reintroducing DeLM, much faster, more capable multi-agent systems through decentralized coordination. ⚡
Compared with our first version in early June, the updated paper expands the evaluation beyond SWE-bench to include Terminal-Bench 4.0, DeepSWE v1.1, and ProgramBench!
A quick recap: DeLM enables parallel agents to coordinate through a shared context and a task queue, with no main agent in the loop. Agents share discoveries, reuse intermediate results, and correct one another as they work, reducing both idle time and redundant work.
Evaluated on 10 long-horizon tasks each from Terminal-Bench 4.0 and DeepSWE v1.1, with GPT-6-Astra and Claude Opus 5.5, DeLM improves accuracy by up to 17.5 percentage points over the strongest baseline, while running up to 2.49× faster than the harness it builds on. On ProgramBench, where agents rebuild entire programs from scratch, DeLM beats Claude Code's test pass rate by up to 19.9 points within the same 120-minute budget.
We’re open-sourcing our code and all DeLM trajectories so you can explore how this collaboration unfolds!
🌐 Project & code: yuzhenmao.github.io/DeLM/
📄 Paper: arxiv.org/abs/2606.10662
🤗 Trajectories: huggingface.co/datasets/yuzh…
More on the coordination design in the thread below 🧵


CLM-8B can play Terraria now 🎮
Every move and every attack is driven by CLM in real time, ranking candidate actions in milliseconds!
🤗 HuggingFace: huggingface.co/Contrastive-L…
💻 GitHub Code: github.com/Contrastive-LM/CL…
🗣️ Discord Channel: discord.gg/5dAQEDJBs
Huge thanks to Joshua Leonard for building this and sharing it with the community 🙌
Jacky Kwok retweeted

Stanford and Nvidia's open CLM-8B caches reusable agent actions and runs up to 9x faster than Jev in tests
venturebeat.com/ai/stanford-…

Jacky Kwok retweeted

Opus 5.5 made an explainer video for me for this paper. ☺️
Introducing Contrastive Language Model (CLM): an ultra-fast System One Model trained with a contrastive learning objective that connects states and actions.
CLM-8B is pre-trained on internet-scale data and delivers up to 9× faster inference than Jev ⚡ while achieving comparable performance across computer-use, gaming, and tool-calling tasks.
With lightweight fine-tuning, CLM-8B sets a new SOTA on challenging agentic coding benchmarks, such as DeepSWE (81.6%) and Terminal-Bench 2.1 (87.6%). In contrast, Jev fails to serve as an effective verifier for these long-horizon tasks.
We also build an efficient training and serving infra for CLMs by disaggregating states and actions, allowing their embeddings to be cached and reused independently. This substantially reduces inference latency in settings where the state evolves continuously while the action set remains fixed.
Finally, we establish scaling laws for CLMs and show that the test contrastive loss decreases predictably as a power law in training compute, model size, and dataset size.
📄 Blog: contrastive-lm.notion.site
💻 Code: github.com/Contrastive-LM/CL…
🗣️ Discord: discord.gg/5dAQEDJBs
🤗 Data & Models: huggingface.co/Contrastive-L…
More details on CLM’s architecture, data recipe, and scaling laws in the thread below 🧵
Joint work with @hangoo_kang @TarunSures41845 @JonSaadFalcon @drmapavone @Azaliamirh and @HazyResearch
We actually released a robotics version of CLM earlier this year! Check out the CoVer-VLA paper to see how this idea extends to robotics 🤖: arxiv.org/pdf/2602.12281
Jacky Kwok retweeted

Pay attention to this new wave of System One models if you are building custom harnesses.
First Jev. Now, Contrastive Language Model (CLM).
CLM is 9x faster than Jev.
CLM seems to be a better verifier than Jev, particularly at long-horizon tasks.
How do Jev and CLM differ?
CLM is contrastive, and Jev is trained with Reinforcement Learning for Calibrated Decisions (RLCD).
Jev receives a situation plus predefined questions, and returns typed decisions with probabilities. CLM embeds the situation and candidate actions, compares their similarity, then ranks or selects the best match.
The point is that there are several ways to attack this problem, which is exciting.
You can see my recent guide on combining System One and System Two models for building custom harnesses. academy.dair.ai/resources/je…
Introducing Contrastive Language Model (CLM): an ultra-fast System One Model trained with a contrastive learning objective that connects states and actions.
CLM-8B is pre-trained on internet-scale data and delivers up to 9× faster inference than Jev ⚡ while achieving comparable performance across computer-use, gaming, and tool-calling tasks.
With lightweight fine-tuning, CLM-8B sets a new SOTA on challenging agentic coding benchmarks, such as DeepSWE (81.6%) and Terminal-Bench 2.1 (87.6%). In contrast, Jev fails to serve as an effective verifier for these long-horizon tasks.
We also build an efficient training and serving infra for CLMs by disaggregating states and actions, allowing their embeddings to be cached and reused independently. This substantially reduces inference latency in settings where the state evolves continuously while the action set remains fixed.
Finally, we establish scaling laws for CLMs and show that the test contrastive loss decreases predictably as a power law in training compute, model size, and dataset size.
📄 Blog: contrastive-lm.notion.site
💻 Code: github.com/Contrastive-LM/CL…
🗣️ Discord: discord.gg/5dAQEDJBs
🤗 Data & Models: huggingface.co/Contrastive-L…
More details on CLM’s architecture, data recipe, and scaling laws in the thread below 🧵
Jacky Kwok retweeted

We are so back to the 2018 era, and this is so beautiful!
Introducing Contrastive Language Model (CLM): an ultra-fast System One Model trained with a contrastive learning objective that connects states and actions.
CLM-8B is pre-trained on internet-scale data and delivers up to 9× faster inference than Jev ⚡ while achieving comparable performance across computer-use, gaming, and tool-calling tasks.
With lightweight fine-tuning, CLM-8B sets a new SOTA on challenging agentic coding benchmarks, such as DeepSWE (81.6%) and Terminal-Bench 2.1 (87.6%). In contrast, Jev fails to serve as an effective verifier for these long-horizon tasks.
We also build an efficient training and serving infra for CLMs by disaggregating states and actions, allowing their embeddings to be cached and reused independently. This substantially reduces inference latency in settings where the state evolves continuously while the action set remains fixed.
Finally, we establish scaling laws for CLMs and show that the test contrastive loss decreases predictably as a power law in training compute, model size, and dataset size.
📄 Blog: contrastive-lm.notion.site
💻 Code: github.com/Contrastive-LM/CL…
🗣️ Discord: discord.gg/5dAQEDJBs
🤗 Data & Models: huggingface.co/Contrastive-L…
More details on CLM’s architecture, data recipe, and scaling laws in the thread below 🧵
Jacky Kwok retweeted

System 1 models have generated significant excitement recently, particularly following the introduction of #Jev.
We introduce Contrastive Language Model (CLM): an ultra-fast System 1 model that connects states and actions through contrastive learning.
CLM-8B delivers up to 9× faster inference than Jev ⚡ while achieving comparable performance across computer use, gaming, and tool calling. With lightweight fine-tuning, it achieves 81.6% on DeepSWE and 87.6% on Terminal-Bench 2.1.
We also introduce efficient training and serving infrastructure for CLMs and establish scaling laws across compute, model size, and dataset size.
📄 Blog: contrastive-lm.notion.site
💻 Code: github.com/Contrastive-LM/CL…
🗣️ Discord: discord.gg/5dAQEDJBs
🤗 Data & Models: huggingface.co/Contrastive-L…
Work led by @jackyk02, in collaboration with @hangoo_kang @TarunSures41845 @JonSaadFalcon
@Azaliamirh @HazyResearch
More details in @jackyk02's post: xitter.cf/jackyk02/status/210290…
@StanfordASL @StanfordAILab @StanfordEng
Introducing Contrastive Language Model (CLM): an ultra-fast System One Model trained with a contrastive learning objective that connects states and actions.
CLM-8B is pre-trained on internet-scale data and delivers up to 9× faster inference than Jev ⚡ while achieving comparable performance across computer-use, gaming, and tool-calling tasks.
With lightweight fine-tuning, CLM-8B sets a new SOTA on challenging agentic coding benchmarks, such as DeepSWE (81.6%) and Terminal-Bench 2.1 (87.6%). In contrast, Jev fails to serve as an effective verifier for these long-horizon tasks.
We also build an efficient training and serving infra for CLMs by disaggregating states and actions, allowing their embeddings to be cached and reused independently. This substantially reduces inference latency in settings where the state evolves continuously while the action set remains fixed.
Finally, we establish scaling laws for CLMs and show that the test contrastive loss decreases predictably as a power law in training compute, model size, and dataset size.
📄 Blog: contrastive-lm.notion.site
💻 Code: github.com/Contrastive-LM/CL…
🗣️ Discord: discord.gg/5dAQEDJBs
🤗 Data & Models: huggingface.co/Contrastive-L…
More details on CLM’s architecture, data recipe, and scaling laws in the thread below 🧵


Jacky Kwok retweeted
Introducing Contrastive Language Models (CLMs), a System 1 model that connects actions and states!
Agentic coding: with lightweight finetuning, CLM-8B sets a new SOTA on DeepSWE (81.6%) and Terminal Bench 2.1 (87.6%).
CLM-8B vs. Jev: comparable zero-shot performance on computer-use, gaming, and tool-calling tasks, while being up to 9× faster.
We are releasing the CLM-8B checkpoint, its data, and infra today!

Introducing Contrastive Language Model (CLM): an ultra-fast System One Model trained with a contrastive learning objective that connects states and actions.
CLM-8B is pre-trained on internet-scale data and delivers up to 9× faster inference than Jev ⚡ while achieving comparable performance across computer-use, gaming, and tool-calling tasks.
With lightweight fine-tuning, CLM-8B sets a new SOTA on challenging agentic coding benchmarks, such as DeepSWE (81.6%) and Terminal-Bench 2.1 (87.6%). In contrast, Jev fails to serve as an effective verifier for these long-horizon tasks.
We also build an efficient training and serving infra for CLMs by disaggregating states and actions, allowing their embeddings to be cached and reused independently. This substantially reduces inference latency in settings where the state evolves continuously while the action set remains fixed.
Finally, we establish scaling laws for CLMs and show that the test contrastive loss decreases predictably as a power law in training compute, model size, and dataset size.
📄 Blog: contrastive-lm.notion.site
💻 Code: github.com/Contrastive-LM/CL…
🗣️ Discord: discord.gg/5dAQEDJBs
🤗 Data & Models: huggingface.co/Contrastive-L…
More details on CLM’s architecture, data recipe, and scaling laws in the thread below 🧵