

@GoogleDeepMind generative AI models + agents | getting great tech into the hands of great creative people
Find me onstage and online
Joined January 2009
- Tweets8.1K
- Following4.9K
- Followers11.8K
- Likes19.7K




Sunday Spicy Take 🌶️
You learn more about a frontier model in five minutes of trying to get it to write a weird joke than from 40 bold numbers in a benchmark table
Kory Mathewson retweeted

we're on a mission to end AI slop, and we're hiring (a lot)!
looking for polymaths to join us:
- research engineers into HCI, aesthetics, evals, and post-training for non-verifiable domains
- engineers who've built RL environments, and have an eye for design
- AI engineers who've worked on memory, context, and observability
if you’re deeply technical but have a creative side to you, you love ambiguous, nuanced, hard problems, that require knowledge across many domains, you’ll have fun here
tastelabs.com/careers or DM me


> be me
> right ribs hurt, jujitsu, ya,ya
> go to doctor: you need an xray
> get an xray: you're images will be sent to your doctor
> can I have my own images?
> sure, we can burn them on a disc
> okay, wait 30 minutes
> while waiting, buy disc reader, haven't had that in ... a decade?
> read disc,... autorun.exe, readme.txt, DICOMDIR...
> "The viewer operates under the following environment: Windows XP" - nice
> CPU: Pentium 4. wut is this 1998?
> copy files to mac folder
> agy --dangerously-skip-permissions
> extract the images and tell me whats up
> good news: lung good, ribs good mostly
> bad news: fracture
> by the way kory, I made you a full dicom image viewer web app... just incase
> dope, reminds me of my time studying biomedical engineering
> cool cool, make it a funny meme
> doctor calls: confirms everything

Incredible result.
And a very inspiring workflow with generative ai Jon.

This bug was first found and fixed by Gemini Flash 3.7, and most experiments in the paper were done by Flash 3.8. Gemini 4 Argon wrote the first draft of the paper and figures, which I aggressively nitpicked until the content was solid but the writing was not. Then I fed Argon a handful of my first-author papers from the last few years and had it do a rewrite in my style (which worked astonishingly well), and then I manually did a rewrite (the hands + keyboard variety) after that. I really liked this workflow! If you like my writing style feel free to throw some of my old papers in your context window and do the same.
awesome.

Using a single Nano Banana image and Blender MCP, Gemini 4 Argon built a 3D Gothic cathedral in @Antigravity.
It iterates on the geometry, textures, and lighting to create the finished scene.

Kory Mathewson retweeted
Generative AI doesn’t make you creative. It rewards you for already being metacognitive.
New study in Journal of Applied Psychology --
Those with high metacognition (planning/monitoring thought) saw large creative gains from AI.
Those without it? Zero significant gain.
The skill of 2026 isn't "using AI."
It's "managing your own mind while using AI."
AI agents log 6x more hours than human employees at @AnthropicAI
As adoption increased, junior technical hires dropped from 27% to 9%. The bottleneck in software is no longer writing code… it’s managing pipelines and reading outputs,
This gives a strong warning about entry-level tech roles. And junior engineers lose the tasks that might teach them core skills.
New strategies are needed to train senior roles without junior experience.
Full piece here - anthropic.com/research/emplo…


Kory Mathewson retweeted

I used Gemini 4 Argon to make Subway Surfers for the new flying Tesla Roadster 🚀
Fly over moving traffic, hit the thrusters to barrel roll in the sky, and collect air power-ups to set a high score.
Play + code below!

A conversation with Sergey Brin, @joshwoodward, @tulseedoshi, and @melvinjohnsonp about Gemini 4 Argon, how we got here, and the path ahead!
Kory Mathewson retweeted
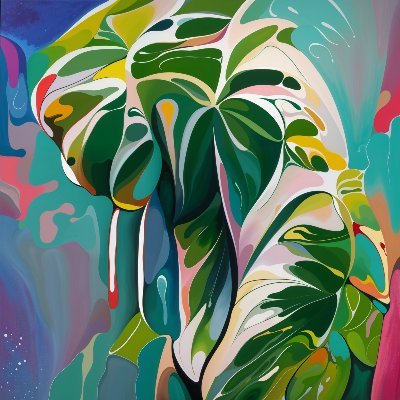
I found Argon could sketch pretty quickly when using a custom dsl tool it had built for the job.
So I asked it to try animating a scene by sketching the next few frames from scratch each time, rocking the motion back and forth a bit, and iterating to make a short clip.
Then I asked it to add cel shading and transparency and to put it all together onto a background.

Gemini 4 Argon from @GoogleDeepMind is awesome.
super capable at generating random bits

An absolute inspiration @GeokenAI at it again with one of the coolest demos I have seen...
Well done to the entire team.

Kory Mathewson retweeted

Dusting off this tweet from April because this gap in shared understanding of LLM capability is *widening*. It's now less "two groups of people speaking past each other" and more a sharp funnel.
- Napkin math somewhere around 6B people (~75% of the population) have barely come in contact with LLMs at all.
- Around 1-2B (~20%) are casual and infrequent users of free-tier ChatGPT-like products. This group sees derpy chatbots and treats them a bit like a better Google search, a writing aid, or etc. Maybe an agent tries to book you a flight. I have non-tech friends who (reasonably, imo) say they have not much use for it at all. Even many professionals outside of math&code are in this tier. For example, execs and many other functions spend a lot of their time talking to other people, so while they understand what is happening intellectually, it is still second-hand and a bit abstract.
- Now we get to professional use of frontier-grade LLMs in math&code. Somewhere around 20M people (0.2%) see first-hand that large, complex projects that used to take them weeks/months can now be completed by agents with a prompt. Building apps, copying apps, translating apps, decompiling apps from binaries... This has all happened very quickly and recently - less than 1 year ago, I was writing code manually by hand, typing memorized computer code commands into a code editor character by character, occasionally pressing Tab to autocomplete a little chunk of code.
- And finally we get to the ~5,000 people (~0.00006%) with access to frontier-grade systems internally. The external world has seen the preview. It looks like swarms of thousands of agents collaborating over weeks on software mega projects: minting zero days, running cyber attacks and defenses at machine speeds, discovering new science, advancing the frontier of mathematics. Things that would have taken top professionals in the industry years of work. Meanwhile, human review and comprehension are starting to fall behind. For example, people are still involved in the "archeology" of the OpenAI-HF incident from many months ago. Mathematicians may be poring over the 722 manuscripts on frontier mathematics for a while.
The funnel is driven by a combination of factors:
1. The impact scales with ambition, problem size, and horizon. A question with a paragraph answer barely stresses the system. You need a reservoir of big, difficult problems that you really care about. This aspect drives the consumer / professional dimension of the funnel.
2. The jaggedness of the system (which I have written about a lot separately). Capability peaks in domains that are digital, verifiable and economically valuable. This is because LLM capability emerges from reinforcement learning on verifiable rewards on a curated environment mixture driven by revenue potential. This aspect primarily drives the area (e.g. math&code) dimension of the funnel.
3. Access. Free-tier, paid-tier, internal.
So this is the weirdness of the moment. The general public has mostly not interacted with these systems. When they have, it looks like a derpy chatbot. The majority of professionals still see only a modest uplift. And a small sliver of professionals are experiencing the vertigo of the curve going vertical. And it is all happening at the same time.

Judging by my tl there is a growing gap in understanding of AI capability.
The first issue I think is around recency and tier of use. I think a lot of people tried the free tier of ChatGPT somewhere last year and allowed it to inform their views on AI a little too much. This is a group of reactions laughing at various quirks of the models, hallucinations, etc. Yes I also saw the viral videos of OpenAI's Advanced Voice mode fumbling simple queries like "should I drive or walk to the carwash". The thing is that these free and old/deprecated models don't reflect the capability in the latest round of state of the art agentic models of this year, especially OpenAI Codex and Claude Code.
But that brings me to the second issue. Even if people paid $200/month to use the state of the art models, a lot of the capabilities are relatively "peaky" in highly technical areas. Typical queries around search, writing, advice, etc. are *not* the domain that has made the most noticeable and dramatic strides in capability. Partly, this is due to the technical details of reinforcement learning and its use of verifiable rewards. But partly, it's also because these use cases are not sufficiently prioritized by the companies in their hillclimbing because they don't lead to as much $$$ value. The goldmines are elsewhere, and the focus comes along.
So that brings me to the second group of people, who *both* 1) pay for and use the state of the art frontier agentic models (OpenAI Codex / Claude Code) and 2) do so professionally in technical domains like programming, math and research. This group of people is subject to the highest amount of "AI Psychosis" because the recent improvements in these domains as of this year have been nothing short of staggering. When you hand a computer terminal to one of these models, you can now watch them melt programming problems that you'd normally expect to take days/weeks of work. It's this second group of people that assigns a much greater gravity to the capabilities, their slope, and various cyber-related repercussions.
TLDR the people in these two groups are speaking past each other. It really is simultaneously the case that OpenAI's free and I think slightly orphaned (?) "Advanced Voice Mode" will fumble the dumbest questions in your Instagram's reels and *at the same time*, OpenAI's highest-tier and paid Codex model will go off for 1 hour to coherently restructure an entire code base, or find and exploit vulnerabilities in computer systems. This part really works and has made dramatic strides because 2 properties: 1) these domains offer explicit reward functions that are verifiable meaning they are easily amenable to reinforcement learning training (e.g. unit tests passed yes or no, in contrast to writing, which is much harder to explicitly judge), but also 2) they are a lot more valuable in b2b settings, meaning that the biggest fraction of the team is focused on improving them. So here we are.