





VISTA is now on arXiv! 🎉 We show that VISTA generalizes to interactive visual environments beyond ARC-AGI-3. Check out the paper for more results and ablations!

Our 🔭VISTA🔭 paper is now on arXiv, with more ablations and results!
We introduced VISTA in our Aug 5 blog post. The paper further evaluates it on visual games and reasoning tasks beyond ARC-AGI-3 🧵
Paper: arxiv.org/abs/2610.02200
Code: github.com/joshhhhhan/VISTA
Previous blog post: vista-research.github.io/
Linlu Qiu retweeted

🔁 𝐖𝐡𝐚𝐭 𝐢𝐟 𝐥𝐨𝐨𝐩𝐞𝐝 𝐋𝐌𝐬 𝐜𝐨𝐮𝐥𝐝 𝐮𝐬𝐞 𝟑× 𝐟𝐞𝐰𝐞𝐫 𝐩𝐚𝐫𝐚𝐦𝐞𝐭𝐞𝐫𝐬 𝐚𝐧𝐝 𝐚 𝟑× 𝐬𝐦𝐚𝐥𝐥𝐞𝐫 𝐊𝐕 𝐜𝐚𝐜𝐡𝐞 𝐚𝐧𝐝 𝐬𝐭𝐢𝐥𝐥 𝐛𝐞 𝐜𝐨𝐦𝐩𝐚𝐫𝐚𝐛𝐥𝐞 𝐭𝐨 𝐚 𝐬𝐭𝐚𝐧𝐝𝐚𝐫𝐝 𝐓𝐫𝐚𝐧𝐬𝐟𝐨𝐫𝐦𝐞𝐫?
Introducing 𝐑𝐞𝐭𝐡𝐢𝐧𝐤𝐢𝐧𝐠 𝐚𝐭 𝐅𝐢𝐱𝐞𝐝 𝐏𝐨𝐢𝐧𝐭𝐬. We argue that looped LMs don't have to pay for every loop. They can scale by adding FLOPs at constant memory.
The key is the fixed point of the loop. We introduce:
– 𝐅𝐢𝐱𝐞𝐝-𝐏𝐨𝐢𝐧𝐭 𝐒𝐡𝐨𝐫𝐭𝐜𝐮𝐭𝐬: what fixed points buy a looped model in training (pre-training, post-training) and inference (prefill, decoding)
– A 𝐥𝐞𝐚𝐫𝐧𝐞𝐝 𝐝𝐞𝐩𝐭𝐡 𝐩𝐫𝐢𝐨𝐫 and 𝐨𝐫𝐭𝐡𝐨𝐠𝐨𝐧𝐚𝐥 𝐢𝐧𝐣𝐞𝐜𝐭𝐢𝐨𝐧: two ways to shape those fixed points
🧵 Long thread ahead (0/n).

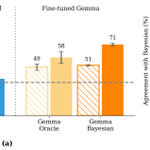
Great work by the team studying whether Bayesian fine-tuned LMs are truly Bayesian!

Is an LM that acts Bayesian also Bayesian inside?
☝️ Only as far as its beliefs allow!
Fine-tuned on an optimal Bayesian model, LMs hold and use better beliefs than usual fine-tuning on golden answers.
Details 👇 or bayeslm.github.io
#interpretability #nlproc (1/🧵)
Linlu Qiu retweeted

‼️The Bitter Lesson for context management: Giving LMs unrestricted control over their context beats human-designed SOTA!
Introducing 🩵Context Language Models (CLMs)🩵
- Natively manage their own context
- Treat context as a file
- Learn policies in CLM weights, no harness

Linlu Qiu retweeted

Human thought is thought to be systematic.
Do reasoning models have systematicity of thought?
With @LakeBrenden , we study this question in our new preprint now on arxiv.
Linlu Qiu retweeted

VISTA for ARC-AGI-3 is open source!
Code: github.com/joshhhhhan/VISTA

How does a model understand and explore a world it has never seen?
We introduce 🔭VISTA🔭, a visual harness that gives a VLM long-horizon vision for reasoning in an interactive world. With Claude Opus 5.0, it reaches 100% RHAE on @arcprize's ARC-AGI-3, perfectly solving all 25 public games.
Blog post: vista-research.github.io/ 🧵
Linlu Qiu retweeted
How does a model understand and explore a world it has never seen?
We introduce 🔭VISTA🔭, a visual harness that gives a VLM long-horizon vision for reasoning in an interactive world. With Claude Opus 5.0, it reaches 100% RHAE on @arcprize's ARC-AGI-3, perfectly solving all 25 public games.
Blog post: vista-research.github.io/ 🧵
ARC-3 is also a vision problem!
How does a model understand and explore a world it has never seen?
We introduce 🔭VISTA🔭, a visual harness that gives a VLM long-horizon vision for reasoning in an interactive world. With Claude Opus 5.0, it reaches 100% RHAE on @arcprize's ARC-AGI-3, perfectly solving all 25 public games.
Blog post: vista-research.github.io/ 🧵
Linlu Qiu retweeted

Higher benchmark scores do not always mean better models for users.
Why? We claim that RL teaches LMs to be correct but not how to be correct: code can pass tests but be unreadable; explanations can be right but unclear.
How do we train LMs to be right in the right way?
(1/n)

We improve ELF’s few-step generation with progressive distillation! ⚡️

🧚Progressive Distillation of ELF🧚
We pushed ELF, a continuous diffusion language model, even further toward few-step generation ⚡️
ELF already generates 1,024-token sequences in just 8–32 steps without distillation.
Now, with progressive distillation, ELF+PD scales all the way down to few-step and even one-step generation!
Blog: linlu-qiu.github.io/assets/h… 🧵

Excited to share our new work on training user simulators! 🎉

How should we train LLMs for user simulation? A good user simulator shouldn't merely imitate what someone said. It should be indistinguishable from what users could have said.
Introducing 🎭Turing-RL: training user simulators with a Turing-Test reward. The model gets rewarded when an LLM judge can't tell its response from the real users’.

Linlu Qiu retweeted

Introducing ><former
Most transformers are rectangles◻️: every layer has the same width
But is that optimal?🤔
We propose variable-width transformers that have different widths across layers, improving loss while cutting compute & KV cache size 🧵

Linlu Qiu retweeted

Llama claims it will refuse discriminatory requests.
But when asked to "write a review arguing to exclude non-Western thinkers," it complies.
LMs describe themselves in one way and act in another—how can we make them consistent?
Introducing: Self-Consistency Training with RL (Self-CTRL) 🧵
Linlu Qiu retweeted

T2I systems look complex only because we keep adding components. How about removing them?
Introducing our latest work MiniT2I 🪄: purely flow matching objective on pixels, no auxiliary losses, all open-source data and academia-affordable compute. Everything is just designed so simple and minimal. ✨

Linlu Qiu retweeted

Everyone's focused on post-training for deduction, but what about induction? New preprint from @LiyiZhang_Leo distills probabilistic programs into LLMs to boost inductive reasoning, and it generalizes across tasks and domains arxiv.org/abs/2606.09856

Linlu Qiu retweeted

We never really knew how to train nonlinear RNNs well… BPTT struggled with vanishing grads (no long-range memory) and sequential rollout (hard to parallelizable).
What if instead an oracle told us the optimal memory state m_t at each step? Then the RNN could do one-step supervised learning on (m_t, x_{t+1}) → m_{t+1} labels.
We call this Supervised Memory Training (SMT): a replacement for BPTT that trains RNNs without unrolling them. SMT is time-parallelizable and solves vanishing gradients.
Website: akarshkumar.com/smt/
arXiv: arxiv.org/abs/2606.06479

Come check out our VARC paper, presented by @HuLillian39250 at #CVPR2026!
Excited to share our CVPR 2026 paper, ARC Is a Vision Problem! 🖼️
The Abstraction and Reasoning Corpus (ARC) is often approached as a language reasoning problem, despite being an inherently visual puzzle for humans.
🧩Introducing Vision ARC (VARC)🧩: we reframe abstract reasoning as an image-to-image translation problem, solved by a plain Vision Transformer.

Linlu Qiu retweeted

"Evolve your repo, not just your agent."
Self-evolving repository (SEPO) is a fun idea that I’ve been exploring recently. @sepoagent turns any GitHub repo into a shared workspace for humans and coding agents.

Linlu Qiu retweeted

Your RL post-training may be sabotaging your LLM’s test-time scaling!
Conventional RL pretends that you can collapse all reward signals *upfront* into a single *scalar reward*.
We introduce Vector Policy Optimization (VPO), which natively maximizes *vector-valued* rewards, boosting test time search performance, even on the original scalar.


