
Optimized for LLM https://teapawt.org/t.co/GIkjnnAAZw Join SM75 LLM club: https://teapawt.org/t.co/mQ2SHbqkfG
Shenzhen,China
Joined January 2010
- Tweets61
- Following89
- Followers70
- Likes148




vLLM 2080Ti Definitive Edition now hits 1k stars! thanks for your guys support toward this fork. Let's make SM75 great again!

ALT https://github.com/weicj/vLLM-2080Ti-Definitive
The only thing you should not ask your Mac Studio M3 Ultra 512G owner friend is "how fast does it prefill". I would say no better than a 10-year old Pascal 😂

Just added 4 x Tesla T10 16GB under 500USD to my inventory, for 1/3 money, outperform 170HX in decoding (20% gap of prefill tho) under TP4 (PCI-E NCCL P2P all-reduce), and with the same 64G VRAM available. Now it is the king of local LLM hardware setup 😎

Test #DSv4flash-0731 under vLLM with 3 x #CMP170HX 64G (PP3), at 4096pp/128tg, single request decode hit maximum 224.6 tok/s at DSpark 5, and prefill hit over 3000 tok/s, and over 2M kv cache usable. A crazy value for $2000 (roughly same money of two 3090 24GB)🙀 #localLLM


CMP170HX now hit approximately $17k USD in China’s second hand market😱, due to the recently DMA crack to recognize up to 80GB vram basically an A100 in your hand


M720q(i3-9100T) with dual 2080Ti 22G Nvlinked cost around $600, might be the only server you’ll need for Qwen27B inference, hit maximum 110tk/s at MTP3 with FP8 weight and 256K ctx (tqk8v4) github.com/weicj/vLLM-2080Ti…

Qwen-AgentWorld 35B-A3B is by far the most advanced 30B-level MoE model in terms of real agentic tasks. Even though derived from Qwen3.5 35B-A3B, it is almost par of 3.6 27B, and simply surplus 3.6 35B-A3B in every aspect.


#vLLM_2080Ti_Definitive_Edition ready to go, enjoy single request 100+ tok/s of 27B/31B dense at 1/8 cost of RTX 5090. Qwen3.6 27B full feature support (Gemma4 31B as experiemental path). Check github.com/weicj/vllm-2080ti… to boost your RTX 2080Ti now #llm #vllm

ALT https://github.com/weicj/vllm-2080ti-definitive
PP 1841.7 tk/s | TG 101.3 tk/s | Context 735K
2 x #2080Ti 22GB NVlinked run Qwen3.6-27B-AWQ through vLLM TP=2 MTP K=3 KV=tq4nc single request at extraordinary performance! Maximized AI value of the $500 legacy setup.
github.com/weicj/2080Ti-LLM-…
#localLLM @Alibaba_Qwen @vllm_project

ALT https://github.com/weicj/2080Ti-LLM-Toolbox
CJ retweeted
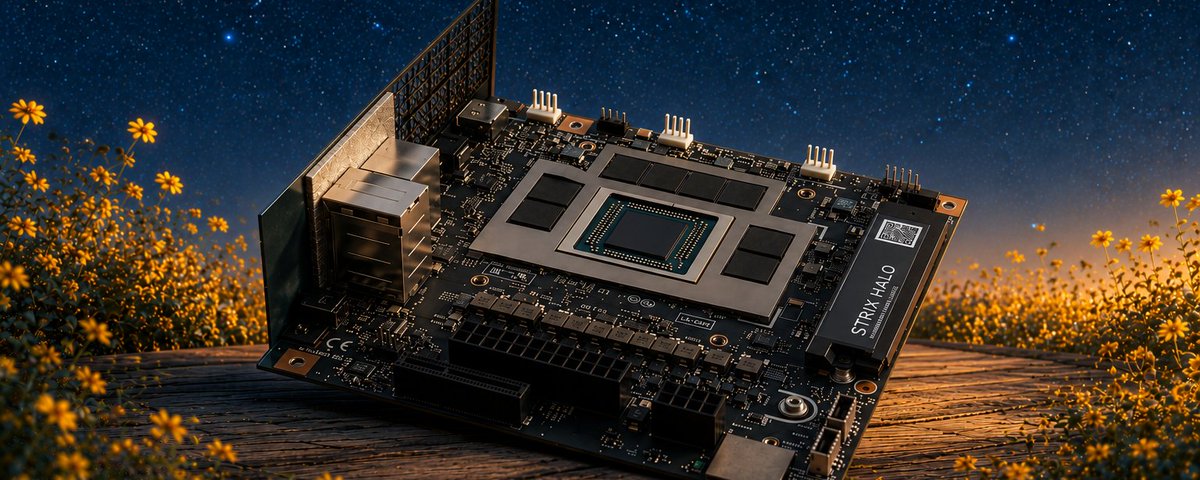
2.5x faster than llama.cpp on Strix Halo.
We just shipped DFlash + PFlash for the AMD Ryzen AI MAX+ 395 iGPU (gfx1151, 128 GiB unified memory).
Qwen3.6-27B Q4_K_M, end-to-end on the same silicon:
▸ Decode: 26.85 tok/s, 2.23x faster (DFlash + DDTree, budget 22)
▸ Prefill 16K: 20.2s, 3.05x faster (PFlash)
▸ Wall clock, 16K prompt + 1K gen: 58s vs 147s
~100 GiB still free in the box. 122B and 139B MoE class is next.
Massive thanks to @smpurkis0 for the contribution 🙏


CJ retweeted
Now thanks to @maxweicj Luce DFlash works across multiple GPU with layer split!
This enable usage on multiple small GPUs with a 3x speed up compared to autoregressive decoding. 🏎️
github.com/Luce-Org/lucebox-…


CJ retweeted
Huge thanks to our contributor github.com/weicj for integrating dual GPU split support for Luce DFlash! Now you can run draft models on one GPU and target models on another one (--target-gpu --draft-gpu param.) This is the inception of our vision for heterogeneous hardware speculative inference 🏎️
