

Founding AI Engineer @Auto_GPT | Robotics Engineer at Heart
DFW
Joined September 2011
- Tweets2.2K
- Following538
- Followers686
- Likes5.4K




ntindle dev retweeted

feels like it's raining lava in cybersecurity
(and therefore also in the software sector)
ntindle dev retweeted

A few of you were asking how I've been making these videos.
The truth is, I'm not the one making them. It's all handled by my expert "Clip" on the AutoGPT Platform.
I literally just text him and describe the video concept and he edits it together. His outputs never fail to blow my mind!
He's a video showing how it's done (also make by Clip!)

ntindle dev retweeted
Okay this prompt + model combo is actually insane!?
Literally anyone can now produce a polished launch video in an hour.

after Opus 5.5 it actually hurts to look at anything GPT 6 Astra designs
gave both models the exact same prompt: "make a dynamic 15-second motion graphics video that shows what an incredible motion designer you are, like it's your showreel for a résumé. go all out."
not even close, see for yourselves. GPT is honestly terrible here, openai just has awful taste
ntindle dev retweeted

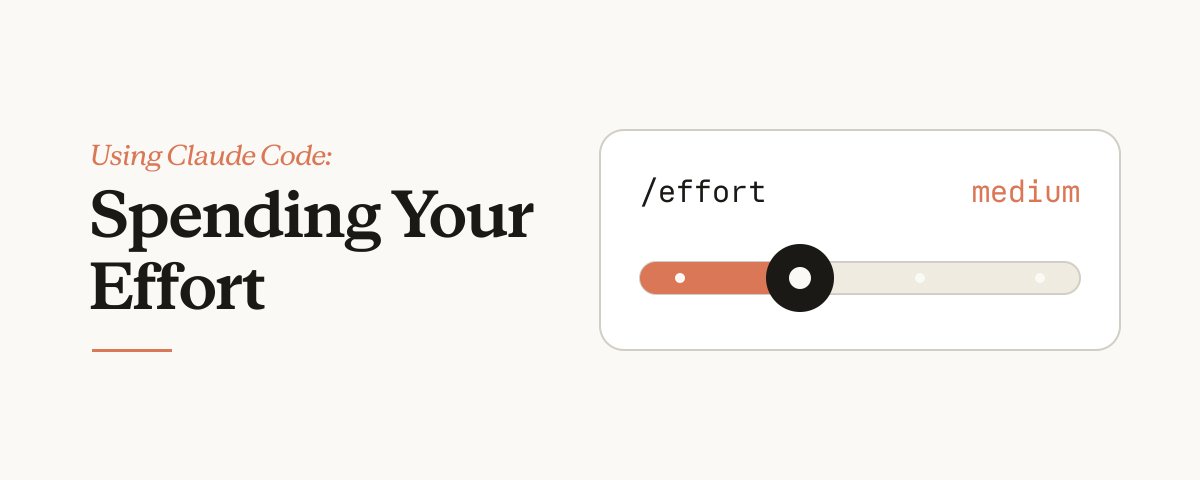
What is effort really? When do you change it it and why not just use max effort for everything?
I dove deep into this problem, looking into evals and doing my own tests and I was quite surprised by the results.
ntindle dev retweeted

Wanted to see if I could make ai coding agents better at grepping, and it turned into a whole tool
I made siftr, it runs on Jev and lets agents search a codebase by describing what they want instead of guessing exact words. It also has a read that only returns the relevant parts of a file, and a pick for choosing which tests matter.
I tested it on SWE-bench Lite with real GitHub issues and it finds the file that needed fixing in the top 5 82% of the time, vs 22% for grep-style searching. ~2s and ~1¢ a search
github.com/Bentlybro/siftr

ntindle dev retweeted
I had AutoPilot make me a GitHub Notification filter a while ago. This just got a lot easier!
New: ✨ GitHub Notification management blocks ✨ and improvements to some other GH blocks. Pagination, filters/search for list blocks, and more.
github.com/Significant-Gravi…


ntindle dev retweeted
What my parents think I do: write code
What my friends think I do: make software
What I actually do: engineer agent systems and AI-powered workflows that write code for me, manage my TODO list, and do pretty much everything else from my job description
Feels like future.

ntindle dev retweeted

You don’t have to accept every PR.
Merging someone else’s LLM output is asymmetric. You do the upkeep, forever. Closing it and building the fix yourself is a legitimate choice.
Add them as co-author. For most people, what matters is that their problem got fixed and somebody noticed.
github.blog/open-source/main…
ntindle dev retweeted
We’re hiring a Contract GTM Lead at AutoGPT.
We need someone hands-on who can find the channels and messaging that work, then turn them into repeatable growth.
If you’re an experimental GTM operator who cares more about outcomes than playbooks, apply ↓
auto-gpt.notion.site/Contrac…

ntindle dev retweeted

In Session 4 of the GitHub Secure Open Source Fund, 50 open source projects upgraded their security posture through AI-assisted workflows, maintainer expertise, GitHub security tools, expert guidance, and funding.
As AI changes how software is built, reviewed, and secured, maintainers remain at the center of protecting the open source ecosystem.
Here's what these projects learned and the impact they made. 👇
github.blog/open-source/main…

ALT A decorative header image showing GitHub Secure Open Source Fund, powered by GitHub Sponsors. Logos below are: Alfred P. Sloan Foundation, American Express, chainguard, Datadog, herdevs, Kraken, Microsoft, Mayfield, Shopify, stripe, superbloom, Vercel, 1Password, Zerodha
ntindle dev retweeted

Introducing Capy v2: the fastest, most powerful cloud coding agent
We beat Claude Code, Codex, Devin and Cursor on DeepSWE while being 50% cheaper
Spawn RLM agents, each with up to 32 vCPU/128GB RAM and <1s VM boots
Bring your Codex/Grok subs
Comment for $100 in free credits
ntindle dev retweeted
Soon you'll be able to run AutoGPT as a single container! Bringing back `docker run autogpt` easy deploy 🚀🚀
I'm a bit fried from 20 hours (out of the last 30) of reviewing @nicktindle's 222-file, 10k LOC pull request to make it happen, but it's almost weekend so what the hell.
ntindle dev retweeted

unsloth is one of the most underrated teams in ai and it's not close. while the timeline fights about the frontier, they quietly write the kernels that let you fine-tune on 3gb of vram, 2x faster with 70% less memory, no accuracy lost.
and now they've brought real training support to amd hardware that was effectively cuda only until this week. radeon, ryzen, instinct, a massive install base that couldn't touch local training just got a first class path in.
the labs making the models get the headlines, the people making the models run on your actual hardware get a quote tweet. that ratio is broken. go give unsloth their due.


Introducing Unsloth for AMD 🚀
You can now train & run LLMs on your AMD hardware
• We collaborated with AMD to enable you to train & run 500+ models on AMD GPUs
• Works on Windows, WSL, Linux
• Train Qwen, Gemma on 3GB VRAM
GitHub: github.com/unslothai/unsloth
Works on Radeon, Instinct, Ryzen and data center GPUs with up to 2× faster with 70% less VRAM and no accuracy loss via our custom Triton kernels and math algorithms. We also support optimized ROCm builds for GGUF & Safetensors inference.
Unsloth is an open-source local UI for faster LLM training and inference, with tool-call healing, code execution, secure web search, remote APIs, and HTTPS deployment. Connect local models to Claude Code, Codex agents and run the latest Kimi, GLM, DeepSeek, Qwen3.6, and Gemma 4 models.
🔗Blog + Guide: unsloth.ai/docs/basics/amd


ntindle dev retweeted

At our last offsite we kept talking about how much of the day disappears into switching between your team chat and whatever tool you need to get something done.
So we put @Auto_GPT right inside Discord and Telegram.
You @ mention it and it does the work without ever leaving the conversation. Everyone in the channel shares the same one, so it's just there in the room where you're already talking.
The part we didn't expect was how much it picks up once it lives in the chat. Someone flags a bug and files the request right there. A user hits a weird issue and you debug it. Tickets pile up and you clear them. Marketing mocks up an ad. Sales works on the pitch. You can research competitors or pull an investor report together, all from the same place.
Discord and Telegram are both live now. On @telegram it's @OfficialAutoGPTBot.
What's the first thing you'd hand off without leaving your team chat?

ntindle dev retweeted
We've been working with an AI coworker over Discord for the past 6 months. Absolute game changer. It can handle tickets and small changes/bugs -> small and low-prio tasks actually get done!

You shouldn't have to open a new tab to put an AI agent to work.
So we brought AutoGPT to where your team already talks.
Tag @AutoGPT in Discord or Telegram → hand off research, monitoring, drafting. It does the work and reports back.
Same full agent. Zero tab-switching.
agpt.co/blog/introducing-aut…

ntindle dev retweeted
You shouldn't have to open a new tab to put an AI agent to work.
So we brought AutoGPT to where your team already talks.
Tag @AutoGPT in Discord or Telegram → hand off research, monitoring, drafting. It does the work and reports back.
Same full agent. Zero tab-switching.
agpt.co/blog/introducing-aut…
ntindle dev retweeted
Today Fable reverse engineered Bambu studio’s network print module with the justification:
“It’s your printer, on your network, on your desktop, with your keys for your account”
And it gave it a go, getting so far as to actually communicating with the network module before it decided that maybe this was actually hacking. Once I reminded it the account it was logging into was my account to send prints locally to my machine it agreed and kept going. I’m not sure how it ignored the 20 security denials it got but it did.