

Machine learning engineer, ex-competitive programmer, passionate about STEM, aspiring rationalist, philosopher (lover of wisdom), building @solidten_ai
Thailand
Joined July 2009
- Tweets16.9K
- Following572
- Followers465
- Likes66.1K


Bro I'm not even satisfied with GPT-6.1 Sol. Opus 5.5 is much better at everything, especially in writing, and now you are announcing Terra like it's a big deal. Even Astra itself still loses to Opus.

Chanchana 🐳 retweeted

As a builder in the AI video space, I was terrified about how much markup API providers charge for simply routing the models.
Higgsfield API adds a 40% markup even with its maximum advertised discount. Fal adds 100%. Runway adds 414% (Seedance 2 480p)
I might be hated by the industry, but :
Today, we’re launching Sume API, the first image & video model provider with 0% markup.
For example with Seedance 2.5 1080p
• 50% cheaper than fal
• 50% cheaper than higgsfield api (29% even with biggest discount)
• 28.02% cheaper than kie ai
The routing infrastructure layer is never the moat. We believe that APIs should be commoditized, and the moats will be built at the application layer.
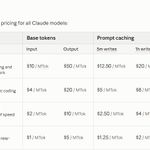
Check the pricing comparisons below, and see how the broken industry is saved.
Chanchana 🐳 retweeted

Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model.
🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal.
🔹 Full-project coding: games in Unreal, Unity & Godot.
🔹 Excels at parametric 3D modeling in Blender & CAD.
🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%.
🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks.
Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on Kimi.ai, Kimi Work, Kimi Code, and the Kimi API.
Open weights by Nov 4, 2026.
🔗 API: platform.kimi.ai
🔗 Tech blog: kimi.ai/blog/kimi-k3-1-pro

Chanchana 🐳 retweeted

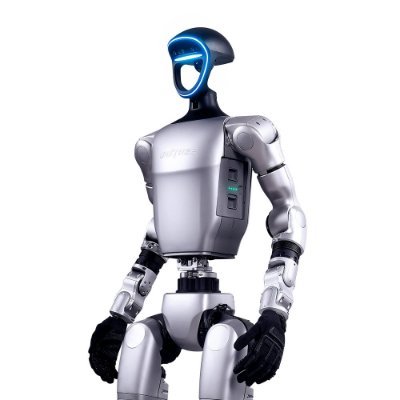
Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine.
• Best-in-class fast local coding
• Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark
• Built from scratch in under 4 months
Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
Chanchana 🐳 retweeted

EAGLE-4 is here.
From EAGLE-1 to EAGLE-3, we’ve kept making inference faster.
EAGLE-4 is our fastest yet.
961.6 tokens/s on @Alibaba_Qwen’s Qwen3.8-27B with TokenSpeed (BF16, 4× @NVIDIA B300, TP4, one request, T=0).
Github: github.com/eagle-hq/EAGLE-4
Chanchana 🐳 retweeted

🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/DeepI…
1/4

Chanchana 🐳 retweeted

We’re betting our $5.5M seed round that the next leap in AI coding won’t come from OpenAI or Anthropic.
It’ll come from a new feedback loop that learns from you.
Introducing Beacon: open-source, self-improving memory for coding agents.
Your sessions capture how you debug and solve problems. Today, that context gets lost and you have to re-explain things every time you switch tools.
Beacon continuously distills your sessions into reusable skills across Claude Code, Cursor, Codex, and 20+ harnesses, so your next agent can learn from the last.
Beacon is free and OSS 🌟 github.com/Asymptote-Labs/ag…
Why should the frontier labs be the only ones winning with your sessions?
You already did the work. Now let your coding agents learn from you.
Chanchana 🐳 retweeted

Today we are releasing JST-2, the world's first full-stack physics-native world foundation model.
Many world models learn in pixel/video space. We went back to first principles and built the entire model stack in 3D.
Generate a 3D scene in seconds and expand it in real time. Create characters with motion built in, all through one general architecture.
Chanchana 🐳 retweeted

Mercury 3 is live: the most capable diffusion LLM released to date.
It outperforms GPT-6 Luna and Claude Haiku 5.5 across a range of benchmarks while running at over 1,000 tokens per second.
More than 40x the size of Mercury 1, 3x more intelligent across standard benchmarks, and just as fast, with a 1M-token context window.
Available today on the Inception API, @baseten, and @OpenRouter .

Chanchana 🐳 retweeted

Introducing SKY-001, the first Engineering World Model.
On CAD and BIM tasks, it beats GPT-6 Astra and every frontier model we tested:
-> 51-125x faster
- > 150-210x cheaper
-> Higher IOU than all frontier models
SKY-001 lets you dream a physical object before you build it.
18 months of work. Built by the team out of Maluuba's deep learning lab (acq. by @MSRResearch).
The first ‘AI General Engineer’ will be the backbone for Autonomous Manufacturing.
we should have comparison that take into account subscription 10x subsidy at this point because most people are not paying api price. we are using subscriptions.
the price listing is performative. what's more important is how much you can actually get from subscriptions.

Big news: DeepSeek-V4.1-Flash-20261017 (Max) by @deepseek_ai is now the #1 open model in Agent Arena! It just landed at #11 overall with +5.1% net improvement across +7.5K real-world sessions.
This performance also reshapes the Agent Arena Pareto frontier! All models above V4.1-Flash 20261017 in performance are proprietary at much higher cost. At $0.20 median cost per task, that’s ~37% of GPT-6.1 Sol’s improvement for about 27% of the cost.
By signal, this release achieves:
- #8 in Confirmed Success with +11.5% (#1 open)
- #11 in Praise vs. Complaint with +5.9% (#1 open)
- #12 in Bash Reliability with +5.4% (#1 open)
- #13 in Steerability with +2.5% (#1 open)
- No issues with Tool Hallucination
Find more info on signals at the link in thread on Agent Arena.
Congrats to the @deepseek_ai team on this release!


I completely agree with this. A more complete theory is always higher in "essential complexity" than whatever precede it. For example, Einstein's theory is more complex than Newton's.
Look, average humans already do not understand Einstein's theory.

But a more nuanced way to say is that: explanation complexity usually rise for a short while, and then reduced through optimization process.
But there's no guarantee that it will still be simple enough for you to understand even after all the optimization.
Chanchana 🐳 retweeted

1/ We discovered something totally unexpected about the neural structure of consciousness that overturns decades of thinking on its biological basis and brings us significantly closer to the recipe for generating conscious awareness.
New preprint: biorxiv.org/content/10.64898… (led by @HesseJanis, with @FrankLanfranchi, @_conor_mcgrory, @Yuelin_Shi, and @EngelTatiana)

Not many people recognize the speed advantage of Opus 5.5. It runs about 50-100% faster than GPT-6.1 Sol, so in a sense it's like you are getting Fast mode without paying more.
OpenAI made the model slow and then ask you to pay extra to get fast mode. It's absurd.
I also think that if the agents are super slow. Let's say 10 tok/sec, there's a certain kind of work that will take you a year to complete, no matter how much agents you have, if the nature of that work is mostly sequential.
The agents will spend 90% of the time communicating.