

Co-founder, Acyclic Labs (YC F26) building faster, cheaper and bigger agent swarms Cambridge CS 22-25: research on parallel PL
London
Joined October 2021
- Tweets109
- Following232
- Followers122
- Likes204




Pinned Tweet
Hello SF, I'm Varun!
@RamV2003 and I just moved here for YC F26 with the goal of getting all agent work to log time execution via swarms.
Would love to connect with those building super ambitious infrastructure and crazy agent setups. If you have any wild projects, please send them my way!

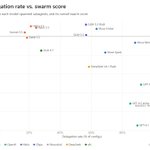
1/ We gave 16 models from 7 labs the ability to swarm on 15 long agentic tasks across a range of domains not usually tackled by swarms. Measured against itself working alone, no model's swarm clearly beats its single agent, and the models that delegate most lose the most. 🧵

2
1
13
5/ Swarms aren't useless; they're task-specific. On 3 of 15 tasks, delegating raises quality by about +0.10, and on one of them it's also 1.4× faster and comes out ahead overall. On the rest it does nothing or hurts.

1
1
5
Varun Latthe retweeted

We’ve published our investor memo: why intelligence will outpace our ability to test its ideas, what we’ve found so far, and what we’re doing next.
vorelios.com/writing/investo…

Varun Latthe retweeted
Acyclic Labs just open-sourced the infra to run 10,000 agent swarms efficiently in a single session. This will take every long-running agent task from hours to minutes.
Congrats on the launch @var1377 @RamV2003!

launching acyclic labs (yc f26)
more agents doesn't mean faster work. we built open-source infra to run 10,000 agents in one session and immediately hit the real wall: models today can't split work or share state without stepping on each other
so we built SwarmBench to score coordination, RL envs to train it, and the runtime to actually run thousands at once
the next leap isn't smarter single models, it's getting 10,000 of them to actually work together
it's amazing when you see improvements that are totally obvious in hindsight, we're still so early

Introducing FlashState ⚡: an inference system that flexibly manages the prefix cache of hybrid LLMs, designed for agentic workloads.
On GLM 5.3 Flash, FlashState more than doubles vLLM's throughput and provider profit, while cutting latency by 3.7× and user cost by 2.5×.
2
4
190
has anyone seen a model use multi-agent effectively recently? feels like with this new generation of models they seem less and less trigger-happy on subagents
and if they were better at multi-agent coordination, do you think you would have fewer concurrent coding agent threads?
3
3
192
Varun Latthe retweeted

Today I'm announcing Workers IO to solve the slowest part of engineering, verification!
AI agents can now write years’ worth of code in days, but it still takes significant engineering effort to verify what’s being built.
It’s impossible to predict all scenarios that could lead to a failure and that’s why most expensive failures are found in production.
Workers IO runs millions of simulated production scenarios on your entire system, including dependencies. These simulations run inside a deterministic hypervisor which injects faults like network delays, disk errors, clock skew, and process failures to verify how your system handles these conditions.
Deterministic execution allows us to systematically explore the state space of the system and perfectly reproduce failures.
We are already helping customers do years worth of production hardening in days and build confidence in what they’re shipping.
If you are working on systems that you can never afford to break, DM me and we can help you battle test them!
Varun Latthe retweeted

This is our YC launch.
I talk about armies of tiny servers.
you should watch it.


Varun Latthe retweeted

We built a lie detector for AI.
Today we're launching Latent (YC F26). It reads a model's mind while it's answering and stops the wrong answers before anyone sees them.
Works with any model, at 500x less than paying another AI to check the work.
Years of interpretability research taught me one thing: the model often knows it's about to be wrong. It just doesn't tell you. Now it does.
Try it free at runlatent.ai
We gave blender to an agent swarm over just 15 minutes to create a complete model of an airship and this is what it achieved:
- 3 floors, 30 rooms and an exterior shell
- 4313 distinct parts and a 271 piece furniture library consisting of over 338k total triangles
- A rover hangar, drones, turbine hall, hydroponic garden, 3 distinct laboratories, an infirmary, radio room, a flight bridge
- Sleeping quarters, laundromat, communal mess, sky lounge (incl. musical instruments), library and much more
Resource usage:
- 230 agents
- 228 peak, 93 average CPU cores
- 2998 tool calls
Later this week i'll give it a shot at something photorealistic
Varun Latthe retweeted

🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/DeepI…
1/4
