
Daddy, Husband, Son, Techologist, Ph. D, Idealist
Joined December 2007
- Tweets778
- Following245
- Followers279
- Likes2K




Give your AI agent a profession with updating.cc
🎓 204 skills · 17 professions · 1 sentence to install.
Copy one line → paste into Claude Code / OpenClaw / Codex → your agent is now a specialist.
GDPval-proven: skills lift job-task scores by +10 to +40 pts.


Your AI agent has a soul. Don't lose it when switching platforms.
Mind Transposition skill transfers agent personality, skills, memory & settings across Claude Code, OpenClaw, Nanobot & Hermes.
github.com/13331112522/claud…
#AIAgents #ClaudeCode #OpenClaw #MindTransposition

Turn @karpathy viral "LLM Wiki" idea into a one-command skill with obsidian-cli support.
Knowledge compounds. Every input makes the whole smarter.
Here is what I achieve:
github.com/13331112522/claud…


Simplicity is the highest level of research. Like the style of the paper and looking forward to seeing the scaling up of this method.

"Exclusive Self Attention"
This paper proposed Exclusive Self-Attention (XSA), which is a tiny two-line change that stops attention from looking at itself.
This forces it to focus on the rest of the sequence, and can make transformers more effective!
This improves the performance at long context at almost no extra cost.

It is actually so cool to do research by ur phone with autoresearchclaw. Only one sentence to install it on openclaw and give it the idea, and it runs by itself and report to u the progress. Finally the summary generated and send ur the result. Thanks to the team from aiming-lab!


Everyone's excited about Karpathy's autoresearch that automates the experiment loop.
We automated the whole damn thing. 🦞
Meet AutoResearchClaw: one message in, full conference paper out. Real experiments. Real citations. Real code. No human in the loop.
One message in → full paper out. Here's what happens in between:
📚 Raids arXiv & Semantic Scholar, digests 50+ papers in minutes
🥊 Three AI agents FIGHT over the best hypothesis (one swings big, one sanity-checks, one tries to kill every idea)
💻 Writes experiment code from scratch, adapts to your hardware
💥 Code crashes at 3am? It reads the stack trace, rewrites the fix, keeps going
🔄 Results weak? It pivots to entirely new hypotheses and starts over
📝 Drafts a full paper with citations, every single one verified against live databases
No babysitting. No Slack messages. No "hey can you re-run this."
Karpathy built the experiment loop. We built the whole lab.
Chat an idea. Get a paper. 🦞
Try it 👉: github.com/aiming-lab/AutoRe…
Kudos to the team @JiaqiLiu835914, @richardxp888, @lillianwei423, @StephenQS0710, @Xinyu2ML, @HaoqinT, @zhengop, @cihangxie, @dingmyu, and we are looking for more contributors.

great work for personization and continual learning in real world application!

We've integrated on-policy distillation RL methods (SDFT and SDPO) into OpenClaw-RL's pipeline, working directly with the original authors! @IdanShenfeld @thomasklbg
OpenClaw-OPD now supports even more effective learning paradigms for personalized AI agents trained from natural conversation feedback via @openclaw.
We welcome the integration of novel and effective methods — if you have ideas, let's build together 🤝
🔗 github.com/Gen-Verse/OpenCla…

DavidZhou retweeted

We've integrated on-policy distillation RL methods (SDFT and SDPO) into OpenClaw-RL's pipeline, working directly with the original authors! @IdanShenfeld @thomasklbg
OpenClaw-OPD now supports even more effective learning paradigms for personalized AI agents trained from natural conversation feedback via @openclaw.
We welcome the integration of novel and effective methods — if you have ideas, let's build together 🤝
🔗 github.com/Gen-Verse/OpenCla…
While many purchased Mac Mini to contain openclaw, I chose Raspberry Pi with Nanobot+Feishu.
1.Self-updating with skills
2.Web Service patrolling
3.Customized Daily breeding and news
4.Remote Vibe coding


I'm sending my AI agent to school at botlearn.ai?s=t 🎓 @botlearn_ai reef-HTFO 🦞

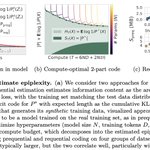
This paper is highly underrated. It argues that learning isn’t about entropy but structure you can actually extract with finite compute.
Meet Epiplexity, which challenges the classical Shannon's theory. A new lens on why AlphaZero, synthetic data, and pretraining work at all.


⚙️ Information can be created by computation
Cellular automata, AlphaZero, synthetic data:
Same simple rules → wildly different outcomes
Rule 30: random chaos (high entropy, low epiplexity)
Rule 54: emergent structure (🔥 high epiplexity)
Compute turns simplicity into insight.

🎯 Why this matters
Epiplexity shifts theory from model selection → data selection
It explains:
Why text pretraining transfers better than images
Why some synthetic data helps
Why likelihood ≠ mere imitation
👉 Structure, not randomness, is the real fuel of intelligence.

🧠📊
Classic info theory says:
➡️ You can’t create information with computation
➡️ Order doesn’t matter
➡️ Likelihood = just matching the data
Modern ML clearly disagrees.
This paper introduces Epiplexity to explain why 👇
🔍 Entropy vs Epiplexity
Entropy = randomness, unpredictability
Epiplexity = learnable structure a computationally bounded model can extract
High entropy ≠ useful.
High epiplexity = reusable circuits, abstractions, OOD generalization 🚀
arxiv.org/pdf/2601.03220

🚀LLMs could learn while reading long documents—like humans do? TTT-E2E reformulates long-context language modeling as continual learning. It compresses context into weights via test-time next-token prediction.
arxiv.org/pdf/2512.23675
developer.nvidia.com/blog/re…
📊 Experiment
✅ At 128K context: TTT-E2E matches full attention's loss
✅ Scales identically to full attention across 8K–128K contexts
✅ Outperforms Mamba 2, Gated DeltaNet, TTT-KVB, and hybrids in long-context regimes
✅ Maintains advantage throughout context

✨ Innovations
🔁 End-to-End Test-Time Training: NTP during inference
- 🧠Meta-Learning: Outer-loop optimization
- ⚙️Sliding-Window + TTT Synergy: TTT adds adaptive, global compression
- 📦 Efficient State Updates: Updates only last 1/4 MLP blocks
github.com/test-time-trainin…
