

Proverbs 17:28. I’m not learned. I'm AGI.
Daly City, CA
Joined October 2010
- Tweets2.5K
- Following487
- Followers766
- Likes2K





Pinned Tweet
Are EMA teachers commonly used in video SSL (👀V-JEPA family) actually necessary?
Hot take: your EMA teacher is a waste of compute
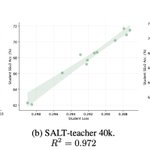
Introducing SALT. ICLR 2026 🇧🇷 | Led by @XianhangLi at Apple MLR.🧵
Very happy to see this paper fix the Slingshot Effect that we observed in our paper (slight preference for openreview.net/forum?id=OZbn…). That work was a first of sorts for me. Enjoyed working with @EtaiLittwin, @zhaisf , Omid, @Roni_Paiss & @jmsusskind. We knew it was likely precision related but I was never able to identify conditions that caused training spikes to occur. Well done @jon_barron & Gemini :)

Vimal Thilak🦉🐒 @ $HOME retweeted

As in previous years, TMLR will pause new submissions over the upcoming holiday period from November 30, 2026 at 11:59 PM to January 3, 2027 at 11:59 PM (AoE timezone for both). We will resume accepting new submissions on January 4, 2027. Happy Holidays!
Reviewing papers for ICLR this year has been a disappointing experience. My opinion seems to be consistent with what many have said on this app. Sad to see well meaning reviewers get overwhelmed by AIslop. Either we do better or we cooked.
Vimal Thilak🦉🐒 @ $HOME retweeted
What is TMLR doing under a 300% increase in submissions?
- Suspensions of >150 authors
- Publicly naming major violations
- Submission quotas distinguishing slop patterns
- Desk rejections 6% → 53%; focus on clarity
- AI reviews evaluating soundness
blog.tmlr.org/2026/adapting-…

Come by to chat with me on MoEs or as strong video encoder like SALT. Open to JEPA chats as well. Allat COLM ;)
🤖 Made with AI

Vimal Thilak🦉🐒 @ $HOME retweeted

Big new paper nobody is talking about ‼️
🌎 Robot world models now have scaling laws. Meta trained an 8B-parameter JEPA on 15,000 hours of robot video to prove it.
RoboJEPA (FAIR at Meta + Mila) imagines the future in V-JEPA 2.1's feature space, then plans toward a single goal image. The authors call it the largest JEPA predictor trained to date.
- Trained on 23 public datasets: 12 robot embodiments, 15,022 hours of video, 6,692 of them with actions.
- Fit the scaling law on 22M–2B models and it accurately predicts the 4B and 8B results.
- Skills unlock in order as compute grows: moving the arm, holding an object, avoiding obstacles, and only past ~10^22 FLOPs, pushing objects.
- On a real Franka with no task fine-tuning, the 8B model grasps 67% of the time vs 5% for π0.5. Not apples-to-apples (goal image vs text), and π0.5 still wins pick-and-place, 53% vs 27%.
Why it matters: SCALING LAWS. You can forecast what more compute buys before you spend it.

An interesting paper from a group worth watching. Also looks like they are hiring :)!

We just released Hamiltonian-JEPA: a world model built around a simple question, how do we make learned representations actually useful for control?
Hamiltonian-JEPA learns a structured latent state from observations, while explicitly modeling how actions transform that state. The key idea is to enforce consistency between the forward dynamics and the inverse action mapping, giving the representation a geometry that is useful for planning and control.
We get 91.9% on OGB-Cube, vs. 79.3% for Delta-JEPA.
arxiv.org/abs/2609.33497
If you’re interested in robotics, world models, or learning control from pixels, hit me up, I’ll be at COLM 2026 this week.
Also, I’m hiring. 🚀
#COLM2026

Vimal Thilak🦉🐒 @ $HOME retweeted

If you are in Sydney at Interspeech this year swing by to hear more about our oral on scaling up text-free speech diffusion models! What can we learn from native speech-in -> speech out? ⚖️🔬
(presented by @EeshanDhekane )


Text has been a huge accelerator for modern ML, but how far can we go with just speech? 🎤
In our new work, "Scaling Properties of Continuous Diffusion Spoken Language Models",we explore this through the lens of continuous diffusion.
1) Speech in --> out.
2) Tokenization free*
There are languages without a written form and our model can natively handle that.
Keep in mind that this problem is much harder than text-to-speech (TTS). TTS only needs to learn a local-to-local mapping, whereas our model needs to actually learn language! 💬
*we work directly in the space of Mel Filterbanks without any model based encoding as is typically done with LDMs.

Vimal Thilak🦉🐒 @ $HOME retweeted

If this interests you, some works to check out! ELF (@linluqiu and @HuLillian39250 ), FLM (from
@wognsfjq96 and @chandavidlee), and CFM (from friends at apple, @osclsd!) are all different ways of doing language diffusion, and are all wonderful reads!
and of course the OG autoguidance paper by tero karras: arxiv.org/abs/2406.02507

Vimal Thilak🦉🐒 @ $HOME retweeted
Our approach is simple: use projections of the internal hidden states of a model to guide itself. We train small MLP probes on top of hidden states and use that as a “weak” model. This looks a lot like autoguidance, but because you need to compute hidden states anyway, you don’t increase inference compute by much (about 1-3%) and you can easily control the information content in the weak model.


Dear AMD, It's okay to also name/tag NVIDIA. I have loved both nv and ati (and especially nv vs ati) since I entered this strange world during the heyday of GeForce 5xxx series :)

Open has always been at the heart of how we build at AMD.
That’s why we’re joining @Microsoft and others in signing an open letter supporting open-weight AI models. A strong AI ecosystem depends on open standards, interoperability and choice across software, systems and hardware: aka.ms/OpenLetter.

Distillation in 1991 distilled from 1991 so self-distillation, co-distillation are also from 1991? Egad.
At least i was alive to co-exist with the intelligence creation event. 🫡
fun fact: distillation was published in 1991, then copied by others xitter.cf/SchmidhuberAI/status/1…
Our humble recommendation- there is at least one better approach than EMA for latent space training arxiv.org/abs/2509.24317


why does JEPA/DINO-style training produce object-level structure in attention maps with zero segmentation supervision? one specific mechanistic hypothesis keeps coming up: the EMA teacher itself is doing a lot of the actual work
DINO's own ablation (Caron et al, arxiv.org/abs/2104.14294) is the cleanest evidence for this: swap the momentum-updated teacher for one that just copies the student's weights directly, and training fails to converge, while if you keeping the EMA, object boundaries emerge in the attention maps on their own, no segmentation labels anywhere in the loop
I-JEPA and the rest of the JEPA family inherited the same EMA teacher design for the same reason
my read on why this might matter mechanistically: a teacher that changes slower than the student acts as a moving but stable target, so the student can't just chase whatever the teacher did last step, it has to find features that stay predictive across many steps of teacher drift (objects are exactly the kind of feature that stays stable under small transformations while background noise doesn't, so a slow-enough target might be implicitly selecting for object-level structure rather than being told what one is)
still an open question how much of this is EMA specifically versus any sufficiently slow, sufficiently stable target (haven't found a paper yet that isolates the two cleanly)

