
Chanhyuk (David) Lee. CS @kaistpr . studying generative modeling.
South Korea
Joined July 2022
- Tweets156
- Following359
- Followers333
- Likes583




Pinned Tweet
Can flow language models scale to billions of parameters and handle real generative tasks?
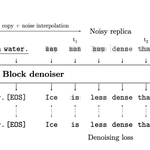
Introducing 🌊 Lafa (Large flow language model), a flow LM scaled up to 8B that matches AR quality, with 🚀 2.5× AR throughput at 7B.
Co-led with @ArnavChavan6 @UdbhavBamba.
Joint work with @wognsfjq96 @hongseu33 @AdtRaghunathan @jw9730
Chanhyuk Lee retweeted

Large Flow Language Models
Lafa shows continuous flow models can scale to 8B parameters by adapting pretrained autoregressive models with under 30B tokens, matching autoregressive quality across instruction following, reasoning, and coding benchmarks.
arxivb.org/abs/2610.28559

Chanhyuk Lee retweeted

Another blockwise continuous diffusion language model at 8B scale, adapted from a pretrained autoregressive model, with flow map distillation and self-speculative decoding for faster inference. Cool😎
xitter.cf/chandavidlee/status/21…

Can flow language models scale to billions of parameters and handle real generative tasks?
Introducing 🌊 Lafa (Large flow language model), a flow LM scaled up to 8B that matches AR quality, with 🚀 2.5× AR throughput at 7B.
Co-led with @ArnavChavan6 @UdbhavBamba.
Joint work with @wognsfjq96 @hongseu33 @AdtRaghunathan @jw9730
Chanhyuk Lee retweeted

Hi all, I have a new result I'm excited to share. It turns out that *all existing implementations* of softmax and cross-entropy (that's JAX, PyTorch, textbooks, etc) have a subtle bug --- two bugs, actually. A simple rewrite fixes both, and eliminates "slingshots" when grokking:


Chanhyuk Lee retweeted

Another great work on large-scale continuous diffusion LLMs 👀
Also huge thanks for sharing our work Sigma arxiv.org/abs/2610.02665 in your post! I learned a lot from the insightful discussion with @chandavidlee and @wognsfjq96 during ICLR 2026 on flow language models

Can flow language models scale to billions of parameters and handle real generative tasks?
Introducing 🌊 Lafa (Large flow language model), a flow LM scaled up to 8B that matches AR quality, with 🚀 2.5× AR throughput at 7B.
Co-led with @ArnavChavan6 @UdbhavBamba.
Joint work with @wognsfjq96 @hongseu33 @AdtRaghunathan @jw9730
Chanhyuk Lee retweeted

This is some really great work on training large scale flow based language models.
They show you can adapt an existing autoregressive backbone, like Qwen, and turn it into a non autoregressive flow model.
Can flow language models scale to billions of parameters and handle real generative tasks?
Introducing 🌊 Lafa (Large flow language model), a flow LM scaled up to 8B that matches AR quality, with 🚀 2.5× AR throughput at 7B.
Co-led with @ArnavChavan6 @UdbhavBamba.
Joint work with @wognsfjq96 @hongseu33 @AdtRaghunathan @jw9730
Chanhyuk Lee retweeted

🎊 Excited to give a tutorial on diffusion LLMs at @NeurIPSConf 2026 with @StefanoErmon @JCJesseLai @mittu1204
📆 Mon, Dec 7, 9 AM AEDT
📍 TikTok Ent Centre (Sydney, Australia)
Topics covered:
> A beginner friendly introduction to diffusion-LLMs
> Designing frontier diffusion-LLMs
> Using Continuous diffusion for LLMs
Chanhyuk Lee retweeted

Excited to announce the follow-up to our NeurIPS 2026 Oral: Improved Training of Strong Stochastic Flow Maps!
We improve the training of SSFMs by unlocking derivative-based losses!
Joint work with @antoniofrancaib @rmincam @ChristianKoke @Niklas_TR and @AlexanderTong7
Chanhyuk Lee retweeted

Super excited about this work! 🌊 Lafa takes flow-based LMs to 8B scale with competitive generation quality and faster decoding. Check out our paper!
Can flow language models scale to billions of parameters and handle real generative tasks?
Introducing 🌊 Lafa (Large flow language model), a flow LM scaled up to 8B that matches AR quality, with 🚀 2.5× AR throughput at 7B.
Co-led with @ArnavChavan6 @UdbhavBamba.
Joint work with @wognsfjq96 @hongseu33 @AdtRaghunathan @jw9730
Chanhyuk Lee retweeted

Announcing FlashMap: a new speculative decoding algorithm based on flow maps! >6x faster inference on Qwen3-8B 🧵
Project page: jshen.net/flashmap
arXiv: arxiv.org/abs/2610.24365
w/ @Jay41969851 @_ryantlee @jonathanmay @cosmo_shirley
Chanhyuk Lee retweeted

@chandavidlee did it again!
buried the lede a little bit, 4.9 tok on specdec is sick. the progress in continuous dlms is so rapid right now. fantastic job by the whole team!
Can flow language models scale to billions of parameters and handle real generative tasks?
Introducing 🌊 Lafa (Large flow language model), a flow LM scaled up to 8B that matches AR quality, with 🚀 2.5× AR throughput at 7B.
Co-led with @ArnavChavan6 @UdbhavBamba.
Joint work with @wognsfjq96 @hongseu33 @AdtRaghunathan @jw9730
Chanhyuk Lee retweeted

Check out this post by my amazing co-author @chandavidlee with more details on Lafa!
Can flow language models scale to billions of parameters and handle real generative tasks?
Introducing 🌊 Lafa (Large flow language model), a flow LM scaled up to 8B that matches AR quality, with 🚀 2.5× AR throughput at 7B.
Co-led with @ArnavChavan6 @UdbhavBamba.
Joint work with @wognsfjq96 @hongseu33 @AdtRaghunathan @jw9730
Chanhyuk Lee retweeted

It was inevitable: Large Flow Language Models.
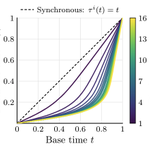
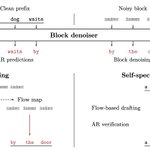
We scale flow LMs to 8B with blockwise flow training, improving pretrained AR via an MTP effect. We use this for self-speculative decoding that verifies flow drafts autoregressively, which is quite fast at batch size one regime.
Can flow language models scale to billions of parameters and handle real generative tasks?
Introducing 🌊 Lafa (Large flow language model), a flow LM scaled up to 8B that matches AR quality, with 🚀 2.5× AR throughput at 7B.
Co-led with @ArnavChavan6 @UdbhavBamba.
Joint work with @wognsfjq96 @hongseu33 @AdtRaghunathan @jw9730
Tagging some people who might be interested:
@sedielem @PatrickPyn35903 @jdeschena @zhihanyang_ @ArashVahdat @ArnaudDoucet1 @iNikitaGushchin @osclsd @FEijkelboom @WeiGuo01 @pengzhangzhi1 @rohit_dilip_ @ssahoo_ @linluqiu @JeongjaeLee0
Also check out this amazing concurrent work, Sigma (arxiv.org/abs/2610.02665) from @zhihanyang_ and @WeiGuo01 ! I'm very excited about the potential of continuous LMs, and we're finally making them work at scale.
Check out also the post about Lafa from @ArnavChavan6 with more details!
