

Building autonomous AI agents. Lawyer by training, engineer by night. Building from Dubai → everywhere..
Dubai, United Arab Emirates
Joined October 2021
- Tweets2K
- Following2.1K
- Followers439
- Likes4.3K


DeepSeek V4.1 Flash, fully local on one Mac Studio (M5 Ultra, 512 GB).
98 tok/s mixed prompts, 74 plain writing, 365 rewriting files. Still 69 tok/s at 1M context; the first read of 1M takes 9 min.
@ddalcu's mlx-serve + 2 small patches

Apache-UAE retweeted

Well, here we go. Qwen4-Max is officially here
A new architecture, native vision, 1M context, and quite a few improvements we've been working on.
It's been a long time coming, and we're really excited to finally get it into your hands.
As always, give it a try, push it on your own tasks, and let us know what you think. We'd love to see what you build with it!
We know what else you've been waiting for. More Qwen4 models are on the way.

📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery!
Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window.
Highlights:
- Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation.
- Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables.
- Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery.
- $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%.
The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder.
Start building today! 🚀
- Blog: qwen.ai/blog?id=qwen4-max
- API: qwencloud.com/models/qwen4-m…
- Token Plan: qwencloud.com/pricing/token-…
More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀

Apache-UAE retweeted

DeepSeek V4.1 Flash, the official 475GB weights, on M5 Ultra. Two runs, 3.5 hours apart:
Prefill: 1,300 vs 2,200 tok/s
Decode: 70 vs 90 tok/s
No new hardware. That jump is software.
Thursday's public bench had one 512GB Mac Studio at 53 tok/s on the same weights. Now it's 90.
teapawt.org/ashxhart/status/212167…

Apache-UAE retweeted

DeepSeek's official 475 GB DSV4.1 Flash is doing 90 decode (up from 70) using TensorFold on M5 Ultra!
We're starting to squeeze Mac's new silicons, lets see where it takes us.


Spent these couple if days benchmarking 16 local model builds on one Mac Studio M5 Ultra 512GB.
Fastest single stream I got out of each model, tok/s:
Nemotron 3.5 Lightning 302
LFM2.5-24B 266
Qwen3.8-27B 186
Qwen3.8 Flash-Next 112
GLM-5.3 Flash 98
DeepSeek V4.1 Flash 73
Ling 3.1 Flash 38
The subs on their own, 8 at once, tok/s each (and MMLU score):
Qwen3.5-4B 95 (72%)
LFM2.5-24B 93 (63%)
Qwen3.5-9B 87 (76%)
Nemotron 3.5 77 (75%)
Qwen3.8-27B 64 (84%)
DeepSeek itself scores 86%, so the fast ones are a real step down.
1
102
Apache-UAE retweeted

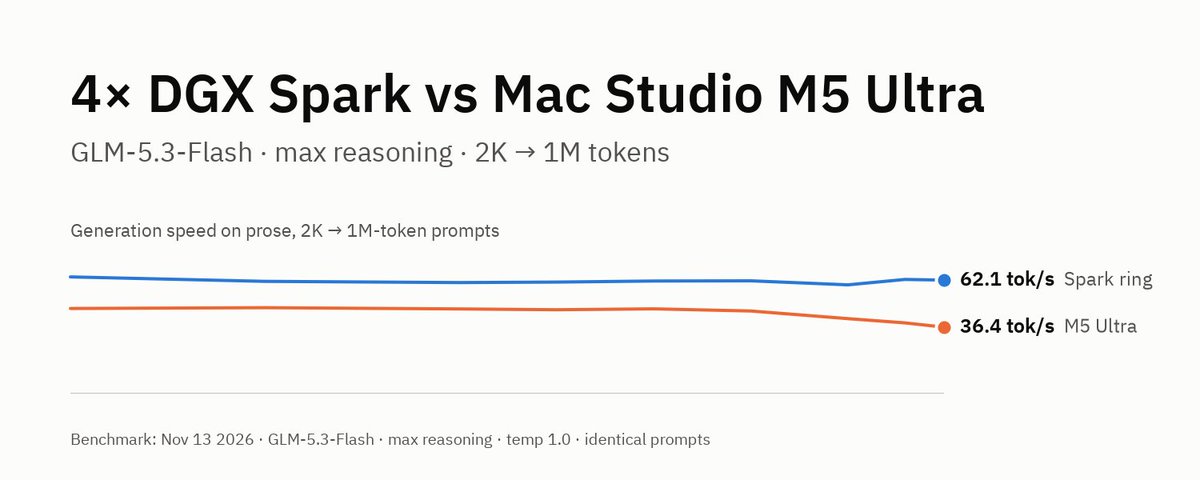
I've been waiting months to put the Mac Studio M5 Ultra 512GB head to head against four DGX Sparks. Today I finally did, with GLM-5.3-Flash at max reasoning from 2K to 1M tokens.
Apache-UAE retweeted

Open Source wins! DGX Spark as Prefill Accelerator based on the work of @jundotkim @ashxhart and @ddalcu 🙏

oMLX can now use your NVIDIA GPU or DGX Spark as a Prefill Accelerator.
github.com/jundot/omlx/relea…
All you need is a Mac that can hold the model. A faster NVIDIA GPU or a DGX Spark takes over the prefill, and your Mac keeps decoding at the same speed.
- The GPU doesn't need to fit the model. It speeds up as many layers as it can hold.
- No RDMA, no Thunderbolt. Just plug in a LAN cable (1GbE works, 2.5GbE recommended).
- One docker run on the NVIDIA machine. No oMLX install or SSH needed there.
64K prompt, M3 Ultra 512GB + GPU over 2.5GbE
With a DGX Spark
- Qwen3.8 27B: 352 -> 1,062 tok/s (+202%)
- Qwen3.8 Flash-Next: 1,370 -> 2,715 tok/s (+98%)
- DeepSeek V4.1 Flash: 1,085 -> 2,412 tok/s (+122%)
- GLM-5.3 Flash: 555 -> 1,076 tok/s (+94%)
With 2x RTX A6000
- Qwen3.8 27B: 352 -> 1,879 tok/s (+434%)
- Qwen3.8 Flash-Next: 1,370 -> 3,928 tok/s (+187%)
- DeepSeek V4.1 Flash: 1,085 -> 1,914 tok/s (+76%)
- GLM-5.3 Flash: 555 -> 978 tok/s (+76%)
The CUDA helper builds on the great CUDA kernels of TensorFold by @ashxhart and mlx-serve by @ddalcu, and would not have been possible without them. Thank you both for sharing them in the open.
Also in 0.8.0rc1
- DeepSeek V4.1 with the DSpark drafter: 8 requests decode 73.2 -> 107.9 tok/s (+47%)
- Concurrent Request Priority: new prompts start sooner while other responses stream
- Affine KV decodes up to 58% faster at long context


Apache-UAE retweeted

the perfect recipe:
- t3code under the hood, but with a simpler UI
- bots that run on any subscription and any CLI
- a task-based orchestrator for complex automations
- computer use
- a built-in browser agents can drive
a hybrid of t3code, Grok Bot and Claude Duet. what's missing?


Apache-UAE retweeted

We asked, and the community delivered! 🎉 A massive thank you to @ApacheAE for testing the new M5 Ultra 512GB for us. It's awesome to finally see what Rapid-MLX can do on Apple's top-tier silicon.
We're building the ultimate Mac AI benchmark, and every single run helps. Got a few minutes? Please contribute your results to the leaderboard! 🚀


🔥 The Rapid-MLX community benchmark is absolutely exploding! 710 runs, 119 contributors, and 20 different Apple chips covered in just 2 weeks. 🚀
But we are missing the final boss: the M5 Ultra.We only have 8 runs total, and absolutely ZERO data for the 512GB beast! 😭💔
Calling all M5 Ultra owners: we need you! 🙏 Help us complete the ultimate Apple Silicon tier list. It takes just one command, and your data stays 100% local.
No M5 Ultra? A quick RT helps us reach the heavy hitters who do! 🔁🙏
Join the squad and light up the leaderboard! 📊 rapidmlx.com/leaderboard

DeepSeek V4.1 Flash 1017, Lossless pack, one Mac Studio M5 Ultra 512 GB: 14% faster output from kernels mlx-serve has but doesn't build on M5.
8k-token prompt, one request:
no drafting 51.6 to 58.9 tok/s
drafting on 68.1 to 77.8
How it was measured, and its limits, below.

ALT Chart: DeepSeek V4.1 Flash 1017, Lossless pack, on one Mac Studio M5 Ultra 512 GB with mlx-serve. Output speed with mlx-serve's fused 4-bit expert kernels off and on, 8k-token prompt, one request. No drafting: 51.6 tok/s off, 58.9 on. Drafting on: 68.1 off, 77.8 on. Headline: 14% faster. Four sessions in one day, no drafting: 1.140, 1.141, 1.144, 1.142. With 8 requests at once there is no gain (1.004). 10 of 12 temperature-0 replies are worded differently; answer quality was not measured.
Limits:
8 requests at once: no gain (1.004 per stream).
With the kernels on, 10 of 12 temperature-0 replies come out worded differently. They read fine, but answer quality wasn't measured.
One Mac, one pack, 8k prompts, 256-token answers.
1
2
107
The numbers, flags and log lines are in a comment on mlx-serve
The fused kernels are @ivanfioravanti's work for @ddalcu's mlx-serve. We only measured them on one box.
1
3
123
DeepSeek V4.1 Flash 1017 on one Mac Studio M5 Ultra 512 GB, official lossless weights: 65.7 tok/s output with a 128k-token prompt, mlx-serve 26.11.2 defaults.
Median of 5 runs, range 62.2–70.0. Other engines and the method below.

Tuning: 8 lossless mlx-serve settings, each checked for identical temperature-0 output. None beat the defaults beyond noise; MTP off was the one clear loss.
One setting that helps 8 users with fresh 8k prompts: --prefill-decode-share 0, 91.1 vs 85.5 tok/s total.
1
2
538