

Building autonomous AI agents. Lawyer by training, engineer by night. Building from Dubai → everywhere..
Dubai, United Arab Emirates
Joined October 2021
- Tweets2K
- Following2.1K
- Followers439
- Likes4.3K


Apache-UAE retweeted

Well, here we go. Qwen4-Max is officially here
A new architecture, native vision, 1M context, and quite a few improvements we've been working on.
It's been a long time coming, and we're really excited to finally get it into your hands.
As always, give it a try, push it on your own tasks, and let us know what you think. We'd love to see what you build with it!
We know what else you've been waiting for. More Qwen4 models are on the way.

📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery!
Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window.
Highlights:
- Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation.
- Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables.
- Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery.
- $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%.
The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder.
Start building today! 🚀
- Blog: qwen.ai/blog?id=qwen4-max
- API: qwencloud.com/models/qwen4-m…
- Token Plan: qwencloud.com/pricing/token-…
More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀

Apache-UAE retweeted

DeepSeek V4.1 Flash, the official 475GB weights, on M5 Ultra. Two runs, 3.5 hours apart:
Prefill: 1,300 vs 2,200 tok/s
Decode: 70 vs 90 tok/s
No new hardware. That jump is software.
Thursday's public bench had one 512GB Mac Studio at 53 tok/s on the same weights. Now it's 90.
teapawt.org/ashxhart/status/212167…

Apache-UAE retweeted

DeepSeek's official 475 GB DSV4.1 Flash is doing 90 decode (up from 70) using TensorFold on M5 Ultra!
We're starting to squeeze Mac's new silicons, lets see where it takes us.


Apache-UAE retweeted

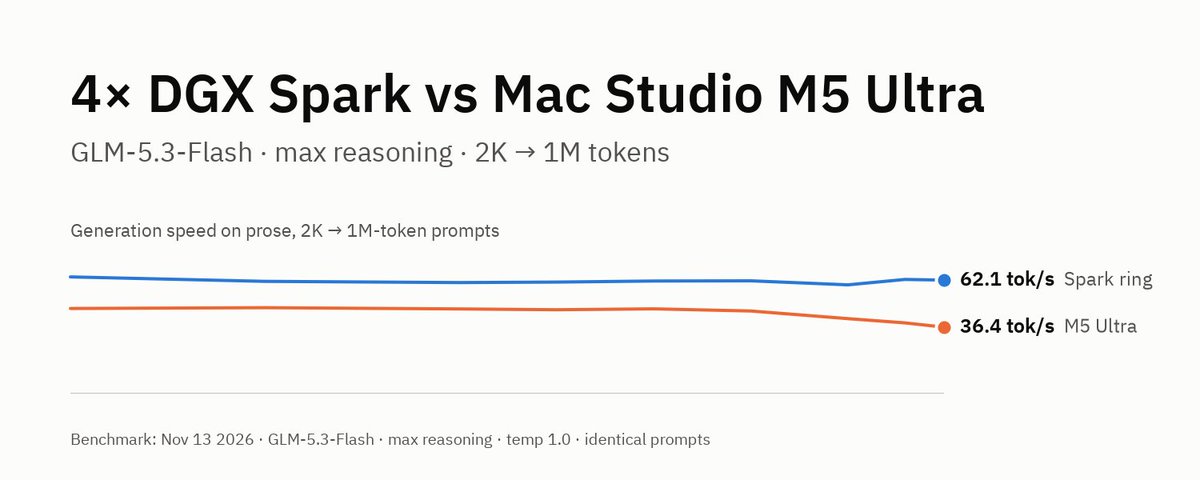
I've been waiting months to put the Mac Studio M5 Ultra 512GB head to head against four DGX Sparks. Today I finally did, with GLM-5.3-Flash at max reasoning from 2K to 1M tokens.
Apache-UAE retweeted

Open Source wins! DGX Spark as Prefill Accelerator based on the work of @jundotkim @ashxhart and @ddalcu 🙏

oMLX can now use your NVIDIA GPU or DGX Spark as a Prefill Accelerator.
github.com/jundot/omlx/relea…
All you need is a Mac that can hold the model. A faster NVIDIA GPU or a DGX Spark takes over the prefill, and your Mac keeps decoding at the same speed.
- The GPU doesn't need to fit the model. It speeds up as many layers as it can hold.
- No RDMA, no Thunderbolt. Just plug in a LAN cable (1GbE works, 2.5GbE recommended).
- One docker run on the NVIDIA machine. No oMLX install or SSH needed there.
64K prompt, M3 Ultra 512GB + GPU over 2.5GbE
With a DGX Spark
- Qwen3.8 27B: 352 -> 1,062 tok/s (+202%)
- Qwen3.8 Flash-Next: 1,370 -> 2,715 tok/s (+98%)
- DeepSeek V4.1 Flash: 1,085 -> 2,412 tok/s (+122%)
- GLM-5.3 Flash: 555 -> 1,076 tok/s (+94%)
With 2x RTX A6000
- Qwen3.8 27B: 352 -> 1,879 tok/s (+434%)
- Qwen3.8 Flash-Next: 1,370 -> 3,928 tok/s (+187%)
- DeepSeek V4.1 Flash: 1,085 -> 1,914 tok/s (+76%)
- GLM-5.3 Flash: 555 -> 978 tok/s (+76%)
The CUDA helper builds on the great CUDA kernels of TensorFold by @ashxhart and mlx-serve by @ddalcu, and would not have been possible without them. Thank you both for sharing them in the open.
Also in 0.8.0rc1
- DeepSeek V4.1 with the DSpark drafter: 8 requests decode 73.2 -> 107.9 tok/s (+47%)
- Concurrent Request Priority: new prompts start sooner while other responses stream
- Affine KV decodes up to 58% faster at long context


Apache-UAE retweeted

the perfect recipe:
- t3code under the hood, but with a simpler UI
- bots that run on any subscription and any CLI
- a task-based orchestrator for complex automations
- computer use
- a built-in browser agents can drive
a hybrid of t3code, Grok Bot and Claude Duet. what's missing?


Apache-UAE retweeted

We asked, and the community delivered! 🎉 A massive thank you to @ApacheAE for testing the new M5 Ultra 512GB for us. It's awesome to finally see what Rapid-MLX can do on Apple's top-tier silicon.
We're building the ultimate Mac AI benchmark, and every single run helps. Got a few minutes? Please contribute your results to the leaderboard! 🚀


🔥 The Rapid-MLX community benchmark is absolutely exploding! 710 runs, 119 contributors, and 20 different Apple chips covered in just 2 weeks. 🚀
But we are missing the final boss: the M5 Ultra.We only have 8 runs total, and absolutely ZERO data for the 512GB beast! 😭💔
Calling all M5 Ultra owners: we need you! 🙏 Help us complete the ultimate Apple Silicon tier list. It takes just one command, and your data stays 100% local.
No M5 Ultra? A quick RT helps us reach the heavy hitters who do! 🔁🙏
Join the squad and light up the leaderboard! 📊 rapidmlx.com/leaderboard


Apache-UAE retweeted

October in a nutshell:
- PHP got hacked
- Railway got hacked
- OpenCode got hacked
- Binance got hacked
- Polymarket got hacked
- GitHub Actions got hacked
- SoftBank got hacked
- Cursor marketplace got hacked
- Coinbase vendor got hacked
- Fireworks AI got hacked
- LiteLLM got hacked
- Capcom got hacked
- npm packages got hacked
- TiDB Cloud got hacked
- Warp's vendor got hacked
happy cybersecurity awareness month
Apache-UAE retweeted
512GB Local AI Showdown: 1x M5 Ultra Mac Studio vs 4x NVIDIA DGX Spark.
Everyone talks about token speed, but nobody talks about what happens when you run inference 24/7.
I ran the math on power, heat, and US electricity bills (at the $0.18/kWh national average).
Here is the real cost of 512GB memory at home:
1. M5 Ultra Mac Studio (512GB)
* Idle power: 9W
* Real 24/7 inference draw: ~280W (385W max peak)
* Daily power used: 6.7 kWh
* US electricity cost: $1.23/day or $37/month
* Heat output: ~950 BTU/hr (Max 1,314 BTU/hr)
2. 4x NVIDIA DGX Spark Cluster (512GB total)
* Idle power: ~95W total (ConnectX-7 NICs stay hungry)
* Real 24/7 inference draw: ~500W (up to 740W if you add an external 200GbE switch)
* Daily power used: 12.0 to 17.8 kWh
* US electricity cost: $66 to $98/month (up to $126 at peak load)
* Heat output: 1,700 to 2,500 BTU/hr
What this means in practice:
The 4x Spark cluster kills the Mac on prompt processing because of massive FP4 compute.
Plus, 500W to 740W is still way better than a 4x RTX 3090 or 5090 rig pulling 1,600W+ from the wall.
600W+ of constant heat from a 4-node cluster plus networking turns a small office into an oven.
You are basically running a small space heater all day, which means paying even more to run your AC.
Meanwhile, the M5 Ultra gives you 1.2TB/s bandwidth in one silent box that barely warms up the room and costs about the price of one streaming subscription per month to run non-stop.
For heavy batch jobs and huge prompts, take the Sparks.
For a 24/7 home server that keeps your room cool and your power bill low, the single Mac Studio is still tough to beat.
Apache-UAE retweeted

TensorFold (app) Beta 6 for macOS is out with lots of new stuff 🔥
TensorFold Beta 6 is live! for macOS 🚀
We've added Bots, easier local model discovery and Kokoro playback so you can listen to chat replies.
You'll also find cleaner chat controls and fixes for memory saving and privacy.
Give it a try: tensorfold.dev
@plotarmordev @MiaAI_lab @volatilemarkts @petruspennanen

Apache-UAE retweeted

MLX-Serve 26.10.1 is out: speed across the board.
Exactly faster. Qwen3.8 27B with its drafter
+66% on an M5 Ultra,
+28% on an M4 Max,
+37% on an M1 Pro.
Qwen Flash Next:
+11% decode on M4 Max,
+51% prefill on M5 Ultra. (up to ~5400 PP!!!!)
Gemma 4, Qwen, LFM2.5, Spark, Bonsai 2 all faster, output byte-identical to 26.9.6 (across 18 models).
New:
* GGUF models run on our own MLX engine, written in Zig and Metal, instead of the llama.cpp fallback. (experimental)
* 🍣 Sushi-format Flash Next packs run directly.
* Qwen-Image 2.1 edits pictures from instructions.
* Drafting is on by default for every model that supports it.
Huge thanks to everyone who filed, tested and fixed this one: @STRML_, @sbusso, @wutang_superfan , lborloz, LXD-8 @alinselea zeeshanhaque21 @Lojza3D, h9q2cyxvgm-ui @kennethrdegraff, @CowboyCoderHQ , codysk, @Beamsters1, @CerebralCoding_, @AjAbsaki , and more.. THANKS ! Please comment if I did not include your name, for visibility, I know people mostly by their GH handle.
Special thanks to @ashxhart and @Spangler3000 for pushing !
Benchmarked and tested across 5 machines: htmlhost.jax.workers.dev/ren…
GH Release Download + Changelog:
github.com/ddalcu/mlx-serve/…
Website: mlxserve.com

Apache-UAE retweeted
Three ecosystems collide 🔥
AMD joins the MCDMA club, as we have now achieved true RDMA. @Apple @NVIDIAAI @AIatAMD
We measured ~10 µs round trip bidirectionally.
Huge thanks to @petruspennanen for giving me access to their Strix and Spark so I could get this up and running.
The next test is running inference across them 👀
mcdma.dev github.com/ashhart/mcdma

Apache-UAE retweeted

هذا موقع لشباب اماراتيين يتضمن وصفات القهوة
وتقدرون تضيفون وصفاتكم عشان غيركم يستفيد
وماتحتاجون تسجلون فيه حتى ..
therecipedrop.ae/

Apache-UAE retweeted

You can now run locally one of the strongest models DeepSeek v4.1 Flash on just one or two DGX Sparks.
- 600k context/ 775k KV cache
- 32 tok/s single stream,
- 42 tok/s with 2 concurrent
- 1000 tok/s prefill.
- EXL3 quantization
One of the best models you can actually run today not need a data center
- github.com/MiaAI-Lab/DeepSee…

Apache-UAE retweeted

📰 A 128GB unified-memory CUDA laptop is coming NEXT MONTH. Think about that. 👀
2 - Models
🟢 Variant 1 - N1X 128GB
🧠 20-core Grace CPU
🎮 6,144-core Blackwell GPU
💾 Up to 128GB unified LPDDR5X
💻 Laptops + mini PCs
🔵 Variant 2 - Smaller N1X
🧠 18-core Grace CPU
🎮 5,120-core Blackwell GPU
💾 Up to 64GB unified memory
💻 Laptops only
@nvidia confirmed the high-end RTX Spark N1X for laptops ...
🧠 20-core Grace CPU
🎮 6,144-core Blackwell RTX GPU
💾 Up to 128GB LPDDR5X unified memory
⚡ Up to 1 PFLOP FP4 AI
🔥 45–80W laptop TDP
🟢 Native CUDA
Until now, if you wanted 100GB+ of memory available to a local model, machines like Strix Halo and Apple Silicon were some of the most interesting options.
Now NVIDIA is bringing 128GB unified memory + Blackwell + CUDA to an actual Windows laptop.
Vendors ...
💻 ASUS
💻 Dell
💻 HP
💻 Lenovo
💻 Microsoft
💻 MSI
Systems begin arriving in October.
Pricing? Not announced yet.
But Local AI laptops are about to get VERY interesting.
Strix Halo vs Gorgon Halo vs RTX Spark N1X might be the hardware fight to watch. 👀
Link in ALT

ALT https://blogs.nvidia.com/blog/local-ai-ifa-next-gen-agents-nv-pair-rtx-spark/?utm_source=chatgpt.com
