
Filip Pavetić retweeted

We’re bringing agentic video understanding to our latest Gemini models.
They can now analyze videos with better accuracy while using up to 88% fewer tokens. 🧵

Filip Pavetić retweeted

Thrilled to share our latest advances in video understanding 📽️: Gemini 2.5 Pro is a truly magical model to play with, excelling in traditional video analysis and unlocking new use cases I could not imagine a few months ago🪄
More in 🧵 and @Google blog: developers.googleblog.com/en…

Filip Pavetić retweeted
Gemini 2.0 Flash's video understanding is here 🚀
Think: search in videos via timecodes, extract text from moving camera footage, analyze screen recordings in real-time interactions with native audio out 🔊
Come and try it aistudio.google.com/ 😀
youtu.be/Mot-JEU26GQ?si=buGM…
Filip Pavetić retweeted

amazing work from video understanding jesus @AntoineYang2 alongside @MarioLucic_ @FPavetic @skprat and many others! they've been bringing better, faster video reasoning to a whole new level and have so much more in store ✨🚀♊

Gemini 2.0 Flash's video understanding is here 🚀
Think: search in videos via timecodes, extract text from moving camera footage, analyze screen recordings in real-time interactions with native audio out 🔊
Come and try it aistudio.google.com/ 😀
youtu.be/Mot-JEU26GQ?si=buGM…
Filip Pavetić retweeted

Attending #NeurIPS2024? If you're interested in multimodal systems, building inclusive & culturally aware models, and how fractals relate to LLMs, we've 3 posters for you. I look forward to presenting them on behalf of our GDM team @ Zurich & collaborators. Details below (1/4)
Filip Pavetić retweeted

🧶PaLI-3 achieves SOTA across many vision-language (and video!) tasks while being 10x smaller than its predecessor PaLI-X.
At only 5B parameters, it's also smaller (and stronger) than the concurrent Fuyu-8B model, though sadly we cannot release the model (props to @AdeptAILabs)

Filip Pavetić retweeted

TL;DR I was too lazy to keep a fork of MHA, and I was too tired of my exps blowing up due to too high LR.
I am still amazed how useful this is even for small models - I can pre-train [Na]-ViT with 1e-2 (previously it blew up at ~5e-3).
Try it out!


QK normalization now available in Flax, thanks to @PiotrPadlewski
github.com/google/flax/commi…

Filip Pavetić retweeted

Sparsity is one of the most promising areas in deep learning (tokens follow different routes in the model). However, these discrete decisions are messy to handle & optimize. Today we introduce Soft-MoE. The idea is simple: Don't route tokens, route linear combinations of them.

ALT https://arxiv.org/abs/2308.00951
Filip Pavetić retweeted

Introducing Soft MoE! Sparse MoEs are a popular method for increasing the model size without increasing its cost, but they come with several issues. Soft MoEs avoid them and significantly outperform ViT and different Sparse MoEs on image classification.
arxiv.org/abs/2308.00951

Filip Pavetić retweeted
I will be at ICML presenting ViT-22B!
Feel free to grab me if you want to chat about it.

Filip Pavetić retweeted

NaViT (arxiv.org/abs/2307.06304) sets us free from square boxes and lets us think outside the box! Let creativity flow and go for the natural designs we've always wanted in ViTs.
I share a few cool ideas that are made possible with NaViT:
xitter.cf/m__dehghani/status/167…


Filip Pavetić retweeted
1/ Excited to share "Patch n' Pack: NaViT, a Vision Transformer for any Aspect Ratio and Resolution". NaViT breaks away from the CNN-designed input and modeling pipeline, sets a new course for ViTs, and opens up exciting possibilities in their development.
arxiv.org/abs/2307.06304

Filip Pavetić retweeted

At CVPR?
Three papers from the Google Deepmind (formerly Brain) Vision team in in Berlin/Zürich/Amsterdam (+collaborators) there.
If interested in the work or the team, track down the authors!


Filip Pavetić retweeted
Quick summary of our recent work on scaling Vision Transformers - solving stability issues, making training more efficient and cool results:
ai.googleblog.com/2023/03/sc…

Filip Pavetić retweeted

Learn about ViT-22B, the result of our latest work on scaling vision transformers to create the largest dense vision model. With improvements to both the stability and efficiency of training, ViT-22B advances the state of the art on many vision tasks → ai.googleblog.com/2023/03/sc…
Filip Pavetić retweeted
2️⃣2️⃣🅱️: We trained a 22B parameter ViT model, and scale continues to prove its merit! I want to zero in on an aspect of this which is useful however at all scales: a method for improving training stability in transformers.
arxiv.org/abs/2302.05442
Filip Pavetić retweeted

Scaling Vision Transformers to 22 billion parameters continues to improve ImageNet and OOD classification. And while ImageNet top1-accuracy seems to saturate short of 91% after fine-tuning, ObjectNet accuracy continues to increase, resulting in better effective robustness.
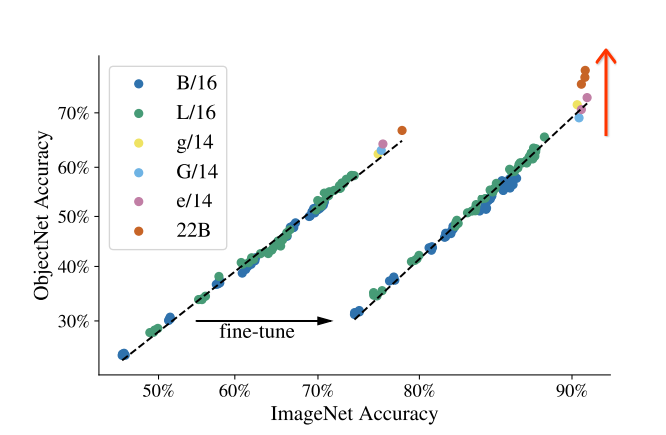
This was a collaboration with an amazing group of people including @PiotrPadlewski, @_basilM, @m__dehghani, @JonathanHeek, @jmgilmer, @AndreasPSteiner, @MJLM3, @mcaron31, @ibomohsin, @RJenatton, @rikelhood, @mechcoder, @anuragarnab, @brainshawn, @giffmana, @mtschannen,...
Filip Pavetić retweeted
1/ There is a huge headroom for improving capabilities of our vision models and given the lessons we've learned from LLMs, scaling is a promising bet. We are introducing ViT-22B, the largest vision backbone reported to date: arxiv.org/abs/2302.05442

Filip Pavetić retweeted
Basil and I will present this work, today at @NeurIPSConf. Join us at 4pm in the 2nd poster session!
