

Investor | AI Infrastructure | Assymetric Stocks Institutional-grade equity research on Substack 1K+ subscribers
Not Financial Advice
Joined December 2022
- Tweets194
- Following118
- Followers125
- Likes428





Pinned Tweet
I just hit 1,000 subscribers on Substack.
900 of them are probably just my mom with different emails, but I actually like the community and I’d like to bring it here… if Elon doesn’t ban me again.
Also part of why I’m moving is my anxious need to talk to @grok. Hope you welcome me, man.
I’ll be talking about the AI build-out and trying not to look completely stupid while we all make some money.
Follow if the notes seem useful. Or don’t. I’ll still be here overthinking everything.
— Killua Capital

1
7
1,153
NVIDIA doesn’t need to build qubits to own quantum.
Fermilab just cut a fault-tolerant architecture task from 5 months → 3 weeks using CUDA-Q Logical.
7x faster.
Today they announced a codesign platform with IBM + Fermilab, pairing DGX B200 systems with IBM’s Nighthawk quantum processors.
Plus a new CUDA-Q decoder that’s up to 13,000x faster on error-correction research.
Investor takeaway:
This is the same CUDA playbook, applied to the next compute wave.
NVIDIA is building the classical + software layer underneath every major quantum effort.
They capture value whether the winning qubit tech is IBM’s, someone else’s, or doesn’t fully arrive for years.
Robotics. Physical AI. Quantum.
Same infrastructure story.
$NVDA is quietly becoming the default platform for every new computing frontier.
— KC

$NVDA is advancing quantum-classical computing with $IBM and Fermilab through its CUDA-Q platform which has already helped reduce a fault-tolerant design cycle from 5 months to just 3 weeks.
And that's the opportunity for Nvidia in quantum because it doesn't need to build a single qubit if its software becomes part of how these machines are built.


3
44
Love the company. Be careful chasing the IPO.
In this sample, 92% jumped on day one. Average gain: +49%.
Then came the pain: an average maximum drawdown of 55% within the first year.
Tesla, Meta, Shopify, Palantir… even great businesses put early buyers through hell.
That’s a drawdown, not the full-year return. But the lesson is clear:
You can pick the right company and still pay the wrong price.
Let the confetti settle.
— KC


JUST IN: Anthropic is set to price its IPO Wednesday at a $1.4T valuation and debut on Nasdaq Thursday as $ANT
1
83

$MU $SKHY $SNDK
Washington just handed Micron, SK hynix and SanDisk a massive bull case.
The proposed MATCH Act would tighten chipmaking equipment controls on China → slower DRAM & NAND capacity expansion there.
China currently hosts ~24% of global DRAM capacity and ~32% of NAND capacity.
Constrain that growth and the rest of the world gets tighter supply.
Nomura math is clean: even if all China-bound Nvidia demand disappears, 2028 HBM demand only drops 1.7-2.5% and conventional DRAM 0.4-0.5%.
Supply constrained > demand hit = pricing power for memory makers.
The plays:
> Micron → DRAM + HBM + NAND
> SK hynix → same, but higher China fab risk
> SanDisk → pure NAND pricing leverage
Legislation still pending, but the setup is obvious.
— KC

Nomura: Global Memory
> Enactment of US bills targeting China (AI OVERWATCH Act, Chip Security Act, MATCH Act) would cause demand loss to be less than supply loss, resulting in a net-positive impact on the global memory market.
> If all China-bound demand for Nvidia chips (via official exports, overseas data centers, and non-official routes) completely disappears, 2028F HBM demand would fall by 1.7–2.5% (assuming Nvidia's HBM demand share is 39% in 2028F) and commodity DRAM demand would drop by 0.4–0.5%.
> As secured equipment inventories deplete and bills take effect, capacity additions by Korean and Chinese manufacturers in China would stall from 2028F, threatening output-per-wafer growth (~24% of global DRAM and ~32% of NAND capacity).
$MU $DRAM $EWY $SKHY
1
177
$SPCX is about to go parabolic
Starship just dropped 26 Starlink V3 satellites, completed 14 orbits, and landed back at Starbase after 22.5 hours.
This is the moment everything changes.
Launch cost per Tbps: Falcon 9 → ~$6M
Reusable Starship → ~$250K
That’s a 10x collapse in cost. Even at lower capacity.
Citi just raised their target from $240 → $280 and boosted revenue + EBITDA.
Pivotal at $260. Raymond James still sitting at $800.
SpaceX builds the rockets, launches the satellites, and owns the customer.
Cheaper launches = faster Starlink growth = higher margins across the entire company.
Full and rapid reusability is next.
The upside from here is not linear.
It’s exponential.
— KC


1
135


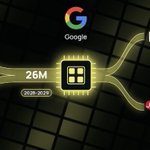
OpenAI & Anthropic just locked in massive Google TPU orders - shipment visibility now extended to 2029, ahead of Nvidia GPU timelines.
2028-29 demand alone:
- ~12M units for OpenAI (v8t, MediaTek)
- ~14M units for Anthropic (v8i, Broadcom)
Total TPU shipments expected:
- 2027: 8–9M
- 2028: 14–15M
- 2029: 16–18M
MediaTek becomes sole design supplier for v9 + v10 (Quillfish). Broadcom leads the higher-margin 8i series.
The AI chip race just shifted. Nvidia’s dominance is no longer unchallenged.


Google TPU update: New OpenAI and Anthropic orders extend shipment visibility to 2029; v10 lineup overhauled (now Quillfish); MediaTek and Broadcom lead as the top suppliers to watch
Key takeaways from my latest industry survey and research conclusions:
1. Order visibility and shipment plans:
Strong new orders from OpenAI and Anthropic have extended Google TPU shipment visibility to 2029, ahead of Nvidia GPUs and other AI ASICs (mostly 4Q27–2Q28).
(1) From 2028, v9 will become the mainstay of Google’s own compute buildout, so v8-series orders (8t / 8i or their design variants) can be viewed as coming from OpenAI and Anthropic.
(2) Combined 2028–2029 demand: about 12M units for OpenAI (8t, designed by MediaTek) and about 14M for Anthropic (8i, designed by Broadcom), with both growing year over year. OpenAI buys outright, while Anthropic uses a mix of leasing and outright purchases.
(3) Given supply chain constraints, more reasonable TPU shipment estimates for 2027–2029 are 8–9M, 14–15M, and 16–18M units, respectively. The market broadly expects AI capex to peak in 2028, yet this plan shows TPU shipments still growing in 2029, driven by direct orders from AI service leaders OpenAI and Anthropic.
2. v10 lineup and supply chain changes:
v10 has changed from Icefish and Merope / Bladerunner to Quillfish, with mass production expected in 2029. MediaTek has won the design service order.
(1) Icefish is now v11, with mass production expected in 2030 and the design service order also going to MediaTek. Merope has lower visibility: no supplier has been chosen, and it may be canceled.
(2) MediaTek will be the sole supplier for v9 (Humufish & Triggerfish) and v10 (Quillfish), accounting for about 45–50%, 50–55%, and 55–60% of total TPU supply in 2027–2029, respectively. TPU’s contribution to its revenue and profit should rise each year.
(3) From v9 onward, all new TPUs use Intel’s EMIB-T advanced packaging. Given limited initial production capacity, the v8 series should remain the bulk of TPU shipments through 2029. v8 is expected to be the main source of TPU profit growth for MediaTek and Broadcom over the next few years, thanks to significant accumulated learning-curve benefits and the fact that both handle procurement of key components and materials.
3. Market attention and supplier outlook:
Recent events should raise and sustain market attention on Google TPU, with key design service providers MediaTek and Broadcom likely to be the supply chain’s top focus.
(1) Uncertainty over Nvidia’s CEO succession helps Google in discussing post-2028 long-term plans with customers. OpenAI and Anthropic are both key TPU customers, so their IPOs should also raise and sustain attention on TPU, and MediaTek and Broadcom are the suppliers the market most readily associates with it.
(2) MediaTek is clearly the biggest TPU winner of the next few years. Its position as sole design supplier from v9 onward, together with a supply share that rises each year alongside TPU shipments, will expand its TPU revenue. The high-margin 8t series, with shipment visibility through 2029, is a key profit source.
(3) Because Broadcom leads the 8i design, its gross margin is even higher than the 8t’s, supporting Broadcom’s profit growth. Note, however, that Broadcom’s focus over the next few years will be non-TPU XPU and AI networking chip orders, with non-TPU revenue expected to surpass TPU revenue as early as 2027.
1
127
Optics just became a national priority.
- Singapore’s 2030 plan is targeting photonics + advanced packaging.
- Taiwan’s AI strategy is prioritizing silicon photonics for the next-gen AI clusters.
The interconnect bottleneck is getting sovereign capital.
Very bullish the stack: $AXTI $GLW $COHR $MRVL $SIVE $CRDO

🚨 ASIAN CHIP HUBS ARE GOING ALL-IN ON SILICON PHOTONICS
Morgan Stanley: Taiwan's AI New Ten Initiatives prioritize silicon photonics alongside government investment in compute infrastructure.
Singapore is committing S$800M to its semiconductor RIE Flagship under RIE2030, targeting advanced photonics and advanced packaging.
$LITE $COHR $MRVL $AXTI $SIVE


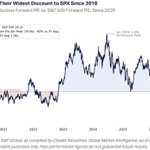
AI trade has never been this cheap
While everyone is panicking about tech, semiconductors just hit the most compelling setup of the year.
Earnings are holding up. Valuations have been crushed.
The numbers:
- 91% of the S&P 500 has reported Q3 → 84% beat EPS, 75% beat revenue
- Semis now trade at just 13.8x forward earnings (Citadel)
- 45% below the January peak
- 42% below their 5-year average
- 25% discount to the S&P 500 (widest since 2018)
- Forward earnings estimates for the sector are up 30% since June
AI demand didn’t disappear. Multiples did.
This is what a real “buy the fear” setup looks like.


1
5
270


If Jensen walks back on stage in that leather jacket, the market is going to lose its mind.


3
217
A slower CPO ramp could give the optical supply chain something valuable: more time to prepare for volume.
If the reported delays materialize, AI networks still need bandwidth. That extends the monetization window for 800G/1.6T pluggable transceivers, their optical DSPs, and the EML and CW lasers powering those links.
Meanwhile, suppliers gain time to prepare the next generation:
- InP substrates: expand crystal-growth capacity and improve wafer quality.
- CW lasers and external laser sources: scale production, improve power efficiency and validate reliability.
- NPO/CPO optical engines: improve bonding yields, thermal management, packaging and testing before deployment at scale.
That matters. Installing capacity is only the first step. Turning it into consistent, qualified output is what generates profitable revenue.
$COHR and $LITE span current and emerging optical architectures. $AXTI supplies upstream InP substrates, while $SIVE has laser opportunities across pluggables and more integrated optics.
Some future revenue could arrive later. But a more gradual transition can also mean longer product cycles, better manufacturing readiness and fewer costly mistakes.
The bullish case: monetize today’s bandwidth demand while building the capacity and reliability needed for tomorrow’s optics.
— KC
$NVDA $COHR $LITE $AXTI $SIVE
A slower CPO ramp extends the earnings runway for today’s pluggable optics leaders.
🚨 FUNDA’s Nov 13 note sees Nvidia’s Spectrum-X CPO volume shipments slipping to late 2027–2028 on low bonding yields and an unresolved test-vendor selection.
Two clear takeaways for the optical stack:
1. Pluggables get breathing room:
Hyperscalers can't pause AI cluster buildouts waiting for CPO packaging yields to mature.
Proven 800G/1.6T suppliers like Innolight and Eoptolink get a longer monetization window before substitution kicks in.
2. NPO gets a longer adoption window:
Slower CPO maturation makes NPO a more practical choice for next-gen scale-up architectures.
I favor suppliers exposed to both paths.
$LITE’s external lasers and $COHR’s PhotonLink platform address both NPO and CPO, so they win regardless of how fast optics move closer to compute.
That broader demand growth also supports the long-term case for InP substrate supplier $AXTI and CW laser vendor $SIVE.


1
4
260
AI connectivity is showing up in the numbers:
• $GLW: Q3 optical revenue of $2.38B, +44% YoY. Enterprise networks +84%; GenAI product sales more than doubled.
• $AAOI: completed a $102.25M acquisition of three Houston buildings totaling ~736,000 sq ft for manufacturing, warehouse and office use.
• $MRVL–$LITE: announced a combination valuing Lumentum at $115B enterprise value, with closing expected in H1 2028.
Optical infrastructure is attracting revenue, manufacturing investment and consolidation. The next test: translating that expansion into durable margins and cash flow.

- Marvell $MRVL plans to showcase its Photonic Fabric memory module at SC26 on November 15–20.
- The module is designed to enable shared memory across multiple racks using optical interconnects.
- Each module supports up to eight DDR5 DIMMs, 72GB of HBM cache, and 7.2Tbps of optical fabric bandwidth.
- Marvell cites memory access latency below 350ns across multiple racks at distances of up to 30 meters.
- The SC26 lineup also includes Structera CXL memory expansion and near-memory compute solutions.
- $MRVL also plans to showcase Teralynx switches and 1.6T and 800G AECs.
> The key opportunity is scaling shared memory capacity without adding more GPUs.
> Combining DDR5 and HBM cache through optical connectivity could allow multiple systems to access a shared KV cache for AI inference.
> This announcement outlines a showcase plan. Customer deployment, real-world performance, and commercial revenue remain to be verified.


1
15
1,884
$NBIS
I’m EXTREMELY bullish on $NBIS.
Just look at what’s happening to AI compute pricing:
- $NBIS 2026 base: ~$12M/MW/year
- $NBIS Q3 contracts: >$25M/MW/year
- $NBIS short-term capacity: $40–50M+/MW/year
- $IREN 5-year contracts: ~$22M/MW/year
- $IREN short-term contracts: ~$40M/MW/year
- $SPCX–Google: $920M/month for ~110,000 GPUs
But the most bullish part is Nebius’s latest earnings:
$12B in customer commitments signed since Q3 began.
>20% increase in GPU-hour pricing QoQ.
>100% of associated CapEx covered by customer prepayments on Q3 deals.
19-month payback, down from 22 months.
Short-term clusters priced at more than 2x reserved rates.
Think about that.
Customers are paying higher prices, committing more capital upfront, and helping finance the infrastructure themselves.
Meanwhile, Wall Street is punishing $NBIS over temporary deployment delays.
These pricing benchmarks aren’t perfectly comparable, but the direction is crystal clear.
Compute pricing is becoming as much about contract duration as the chips themselves with 5-year deals across $IREN and $CRWV around $20–25 per watt-year versus $40–50 for short-term capacity and new $SPCX contracts above $50.
That spread creates an interesting opportunity for $NBIS whose 2026 base sits near $12 while newer short-term deals exceed $40 leaving room for realized pricing to rise as its contract mix shifts toward higher rates.
You can see the same dynamic within SpaceX where $ANT initial agreement priced near $30 while $GOOGL is paying $53–79 including H100s at more than 3x the rental index suggesting contract timing and guaranteed access are becoming just as important as the GPU itself.

Everyone’s watching the HBM makers. They’re missing the real bottleneck.
- TrendForce: HBM4 carries a >30% price premium over HBM3E
- 2027 supply constraints are forcing GPU/ASIC makers into 8-layer stacks (10-20% higher price per Gb)
- $TER owns >50% of the commercial stacked-HBM testing market - more stacks = more tests for the same memory output. CEO already called it out
$TSM wins on base dies + CoWoS.
But the quiet winner is $TER.
Are you positioned for the testing bottleneck?👇🏻
Bernstein estimates HBM4 costs just ~$6–7 per GB to manufacture against selling prices near $20 implying gross margins around 65% if pricing holds which is pretty insane for a memory product.
But what caught my attention is that nearly half the cost of a 32GB stack comes from the base die, packaging and testing rather than memory itself creating another opportunity for suppliers like $TSM and $TER alongside $MU.
And as HBM4 moves from 8 to 16 layers the capacity doubles while cost per GB falls ~13% meaning memory makers can improve margins while advanced packaging and testing become an even bigger part of AI buildout.

1
187
Just view this video from @SemiAnalysis_: he’s claiming that 6 of NVIDIA’s 7 biggest customers are developing their own AI chips.
Should NVIDIA investors be worried? Maybe. But here’s why I’m bullish on AI connectivity regardless.
NVIDIA GPUs, Google TPUs, custom ASICs… The winners may change, but the bottlenecks remain.
More compute means more bandwidth, faster interconnects, optical networking and power infrastructure.
Even if hyperscalers replace neoclouds, computing demand doesn’t disappear. It simply shifts elsewhere.
That’s why I’m bullish on $CRDO, $COHR, $LITE, $AXTI, $AAOI and $MRVL.
I don’t need to predict which chip wins. I’d rather invest in the infrastructure every AI architecture needs.
— KC

Six of Nvidia’s seven biggest customers are building their own chips.
“NVIDIA’s seven biggest customers account for the vast majority of GPUs being deployed: Google, Microsoft, Meta, Amazon, SpaceX, Anthropic and OpenAI. All of them, except SpaceX, are making their own chips.”
“If NVIDIA didn’t prop up CoreWeave and the other neoclouds, those industries just would not exist, and the hyperscalers would have full control.”
“Jensen’s the only executive in the semiconductor industry convincing supply chain companies to invest like they’ve never done before. From our benchmarking, the TPU is just as good as NVIDIA. But Google doesn’t have that DNA of wheeling and dealing.”
2
250
Ship 42 was caught intact after a full orbital flight. First upper-stage recovery from orbit.
This is a high-signal milestone for $SPCX.
Full reusability moves from concept to demonstrated capability.
That supports a path to lower cost per kilogram and higher launch cadence - the two variables that matter most for Starlink scale and the orbital AI satellite plans targeting 2027-2028.
Challenges on cooling, radiation, and laser links remain.
But recovering the Ship removes one of the largest technical risks on the roadmap.
Bullish for the long-term $SPCX case.

Mechazilla catches Starship! Congratulations to the entire SpaceX team on this incredible achievement!
2
284
Ship 42 was caught intact after a full orbital flight. First upper-stage recovery from orbit.
This is a high-signal milestone for $SPCX.
Full reusability moves from concept to demonstrated capability.
That supports a path to lower cost per kilogram and higher launch cadence - the two variables that matter most for Starlink scale and the orbital AI satellite plans targeting 2027-2028.
Challenges on cooling, radiation, and laser links remain.
But recovering the Ship removes one of the largest technical risks on the roadmap.
Bullish for the long-term $SPCX case.
Mechazilla catches Starship! Congratulations to the entire SpaceX team on this incredible achievement!
1
203
$AVGO $COHR $LITE $MRVL $AAOI $AXTI $AMD
Goldman estimates ~$3.8T in AI infrastructure CapEx through 2028.
Cost per GW:
• $NVDA → $50B
• $AVGO → $25B (50% cheaper)
• $AMD → $35B (30% cheaper)
Capacity growth 2026–2028:
• $NVDA: 14 → 22 GW (+57%)
• $AVGO: 5 → 20 GW (+300%)
• $AMD: 1 → 3 GW (+200%)
Hyperscalers are aggressively adopting custom ASICs to cut costs and diversify suppliers.
Broadcom-based systems could approach NVIDIA’s deployed capacity at roughly half the infrastructure cost per GW.
Very bullish on $AVGO and the AI connectivity stack.
PS - AI connectivity is the next memory trade.
— KC
Pretty insane that Goldman forecasts ~$3.8T in AI infrastructure spending tied to $NVDA, $AVGO and $AMD systems through 2028:
• Nvidia ~$2.7T (63% of CapEx, 47% of GW)
• Broadcom ~$876B (21% of CapEx, 31% of GW)
• AMD ~$228B (5% of CapEx, 6% of GW)
Nvidia still captures majority of spending but the gap between dollars spent and capacity deployed shows just how quickly custom silicon from $META, $GOOGL, $AMZN and $MSFT is gaining ground.

1
6
745